Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
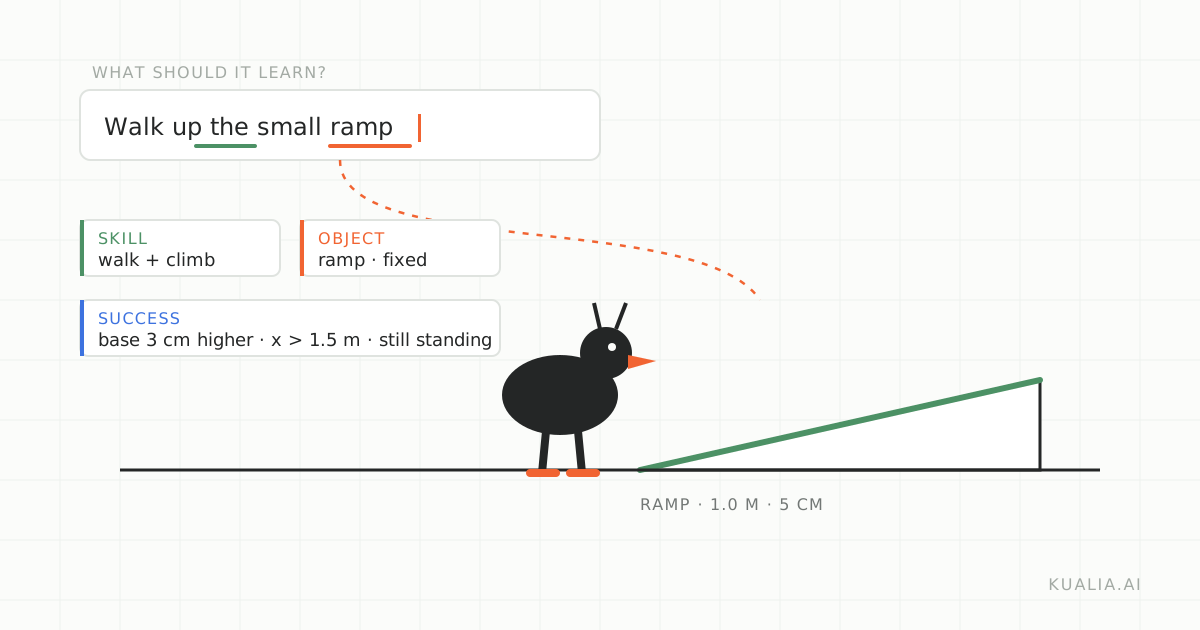 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
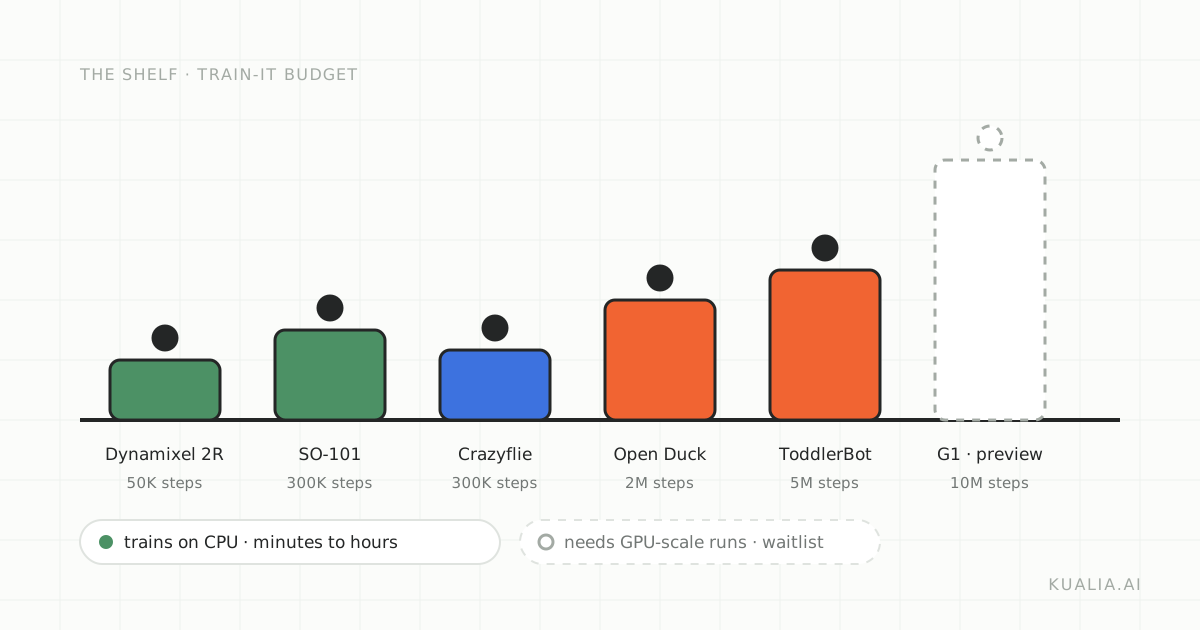 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
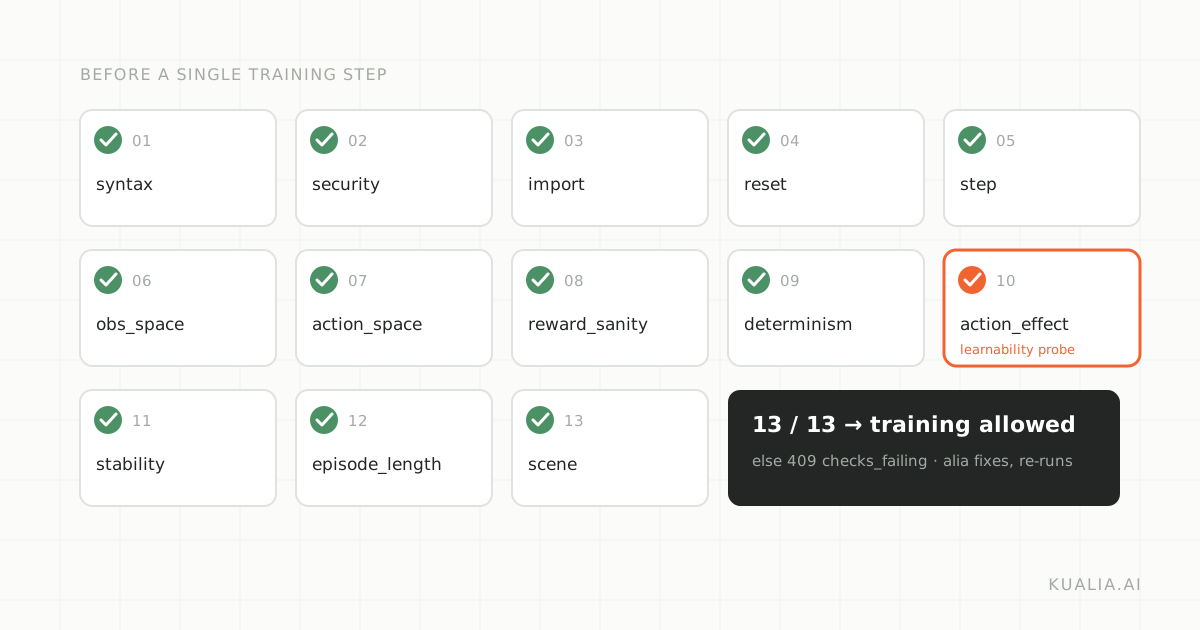 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
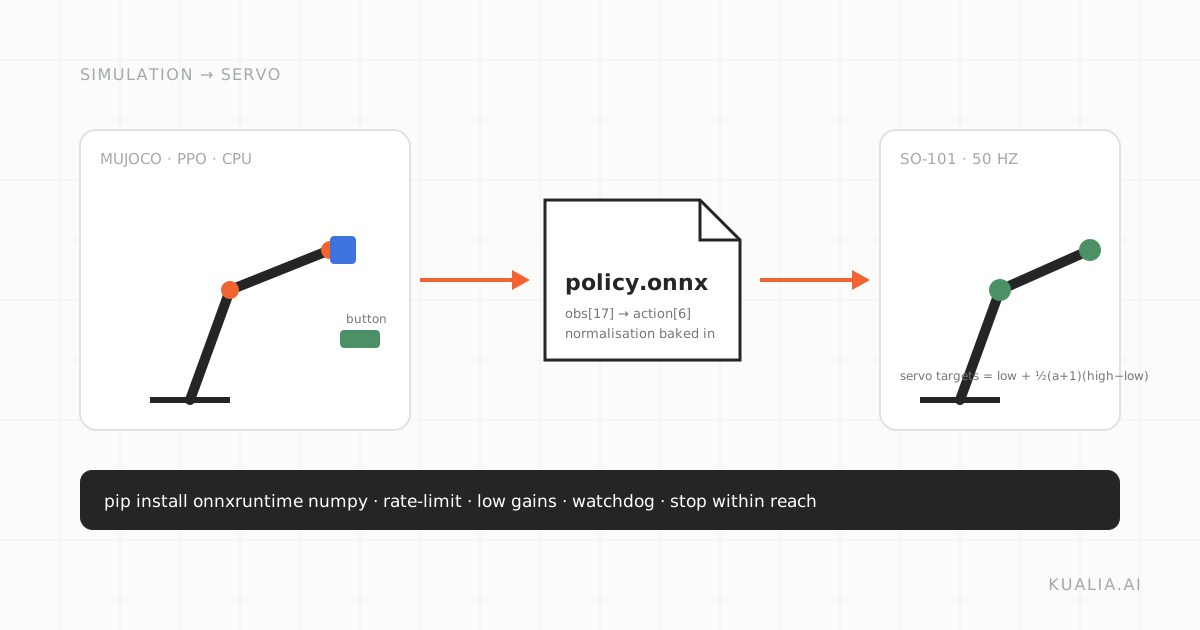 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
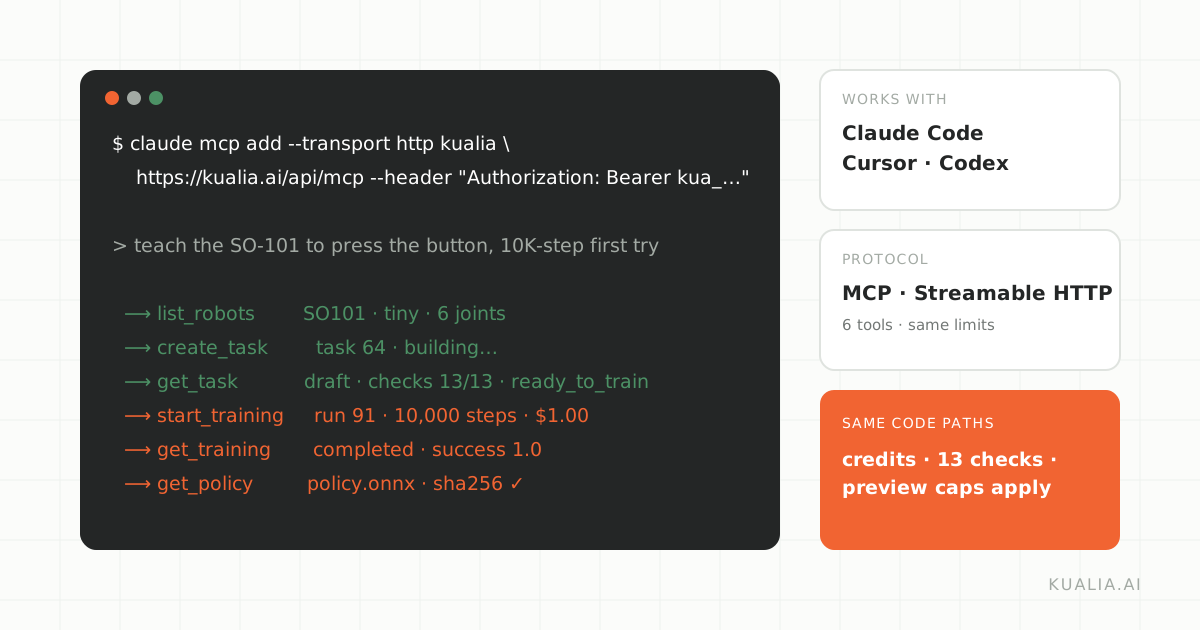 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 39 of 59
Apr 3, 2026A Continual Offline Reinforcement Learning Benchmark for Navigation Tasks: Tackling the Plasticity-Stability-Efficiency TrilemmaThe field of reinforcement learning has made remarkable strides in solving complex tasks, from mastering games like Go to controlling robotic systems. However, most of these successes occur in static environments where t Apr 3, 2026Hierarchical Potential-based Reward Shaping: When Optimal Isn't Optimal EnoughReinforcement learning in robotics faces a fundamental challenge: how do you encode complex, multi-faceted objectives into a single reward signal? The paper "Hierarchical Potential-based Reward Shaping from Task Specific Apr 3, 2026MoRI: Teaching Language Models to Think Like Scientists Through Motivation-Grounded ReasoningThe field of AI-assisted scientific discovery has reached an inflection point. While large language models demonstrate impressive capabilities across many domains, their performance in scientific ideation remains frustra Apr 3, 2026HandX: A New Foundation for Understanding and Generating Bimanual Hand MotionThe field of human motion generation has made remarkable strides in recent years, with diffusion models and autoregressive approaches producing increasingly realistic full-body animations. However, one critical aspect ha Apr 3, 2026Catching Colluding AI Agents: When the Hidden Signal Lives in Model ActivationsAs large language models increasingly operate in multi-agent systems, a troubling possibility emerges: what if the agents learn to secretly coordinate against human oversight? Recent work has shown that LLM agents can es Apr 2, 2026 · TRLLM Ajanlarının Post-Training Otomasyonu: İlerleme ve Tehlikeli Davranış Kalıpları Giriş Yapay zeka ajanlarının yazılım geliştirme alanındaki başarıları, daha büyük bir soruyu gündeme getiriyor: Bu sistemler kendi gelişimlerini otomatikleştirebilir mi? PostTrainBench: Can LLM Agents Automate LLM Post- Apr 2, 2026Can AI Agents Automate Their Own Training? Lessons from PostTrainBenchThe field of artificial intelligence has reached an intriguing inflection point. As LLM agents become increasingly capable at software engineering tasks, researchers are beginning to ask a fundamental question: can these Apr 2, 2026 · TRGürültü Hassasiyeti Üssü: Yüksek Boyutlu Öğrenmede İstatistiksel ve Hesaplamalı Zorlukları Birleştiren Anahtar Giriş Yüksek boyutlu verilerde gizli düşük boyutlu yapıları keşfetmek, modern makine öğrenmesinin en temel zorluklarından biridir. Bu bağlamda, single-index ve multi-index modeller, özellik öğrenme algoritmalarının yete Apr 2, 2026A Noise Sensitivity Exponent Controls Large Statistical-to-Computational Gaps in Single- and Multi-Index ModelsUnderstanding when statistical learning becomes computationally intractable represents one of the most fundamental challenges in modern machine learning theory. A recent paper by Defilippis, Krzakala, Loureiro, and Maill Apr 2, 2026 · TRAçık Kaynak Arama Ajanları: OpenSeeker ile Demokratikleşen Frontier Performansı Giriş Yapay zeka alanında son yılların en çarpıcı gelişmelerinden biri, büyük dil modellerinin (LLM) web üzerinde derin arama yapabilme yetenekleridir. "OpenSeeker: Democratizing Frontier Search Agents by Fully Open-Sou Apr 2, 2026OpenSeeker: How 11.7K Samples Are Reshaping the Search Agent LandscapeThe artificial intelligence community has witnessed a remarkable development that challenges the conventional wisdom about training frontier-level search agents. OpenSeeker, introduced by researchers at Shanghai Jiao Ton Apr 2, 2026 · TREpisodik Pekiştirmeli Öğrenmede Temel Sınırlar: Durağan Olmayan MDP'lerde H³ Bağımlılığı Giriş Pekiştirmeli öğrenme (reinforcement learning) alanında en temel sorulardan biri, bir ajanın optimal politikayı öğrenmek için kaç örneğe ihtiyaç duyduğudur. "Episodic Reinforcement Learning in Finite MDPs: Minimax Apr 2, 2026The Fundamental Limits of Learning in Non-Stationary Episodic MDPs: A Deep Dive into Minimax Lower BoundsThe field of reinforcement learning has made tremendous progress in recent years, yet fundamental questions about the theoretical limits of learning remain active areas of research. A recent paper titled "Episodic Reinfo Apr 2, 2026 · TRBüyük Dil Modellerinin Sanal Gerçeklik Erişilebilirliğinde Sosyal Aktör Rolü: Görme Engelli Kullanıcılar İçin AI Rehber Sistemi Giriş Sanal gerçeklik (VR) teknolojisinin sosyal platformlarda hızla yaygınlaşmasıyla birlikte, görme engelli ve az gören (BLV - Blind and Low Vision) kullanıcılar için erişilebilirlik sorunları kritik bir hal almıştır. Apr 2, 2026Understanding the Social Dynamics of AI Guides in Virtual Reality for Blind and Low Vision UsersThe intersection of artificial intelligence and accessibility has produced some fascinating developments in recent years, but few are as revealing about human-AI interaction as the work presented in "Understanding the Us Apr 2, 2026 · TRSürekli Pekiştirmeli Öğrenmede İlerleme ve Zorluklar: Dinamik Öğrenme Paradigmasının Derinlemesine İncelenmesi Giriş Yapay zeka alanında pekiştirmeli öğrenme (reinforcement learning, RL) algoritmaları, statik ve izole edilmiş görevlerde etkileyici başarılar elde etmiştir. Ancak gerçek dünyada karşılaştığımız problemler nadiren b Apr 2, 2026Selective Memory in Continual Reinforcement Learning: Beyond Catastrophic ForgettingThe field of reinforcement learning has long grappled with a fundamental limitation: most algorithms assume static environments where task distributions remain constant throughout training. Yet this assumption crumbles w Apr 2, 2026 · TRZor Negatif Örneklere İhtiyaç Yok: Konsept Merkezli Öğrenme ile Kompozisyonellik ve Zero-Shot Performansı Aynı Anda Giriş Görsel-dil (vision-language) modellerinin kompozisyonel anlama yetenekleri, bilgisayarlı görü alanının en kritik zorluklarından biri olmaya devam ediyor. CLIP benzeri kontrastif modeller, zero-shot sınıflandırma v