Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
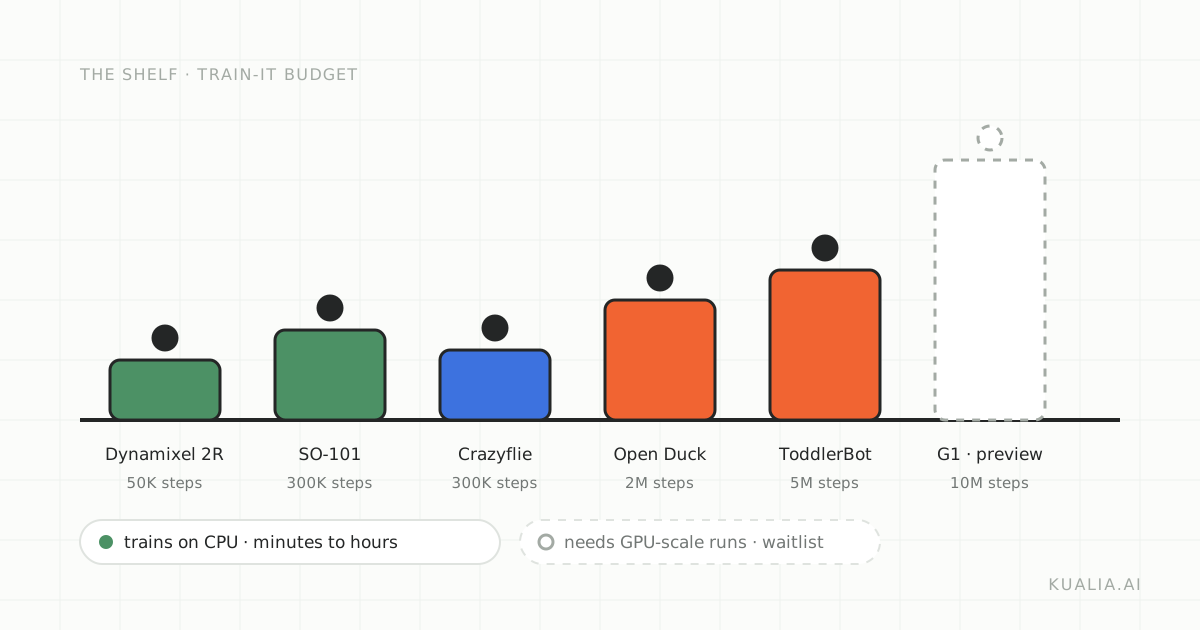 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
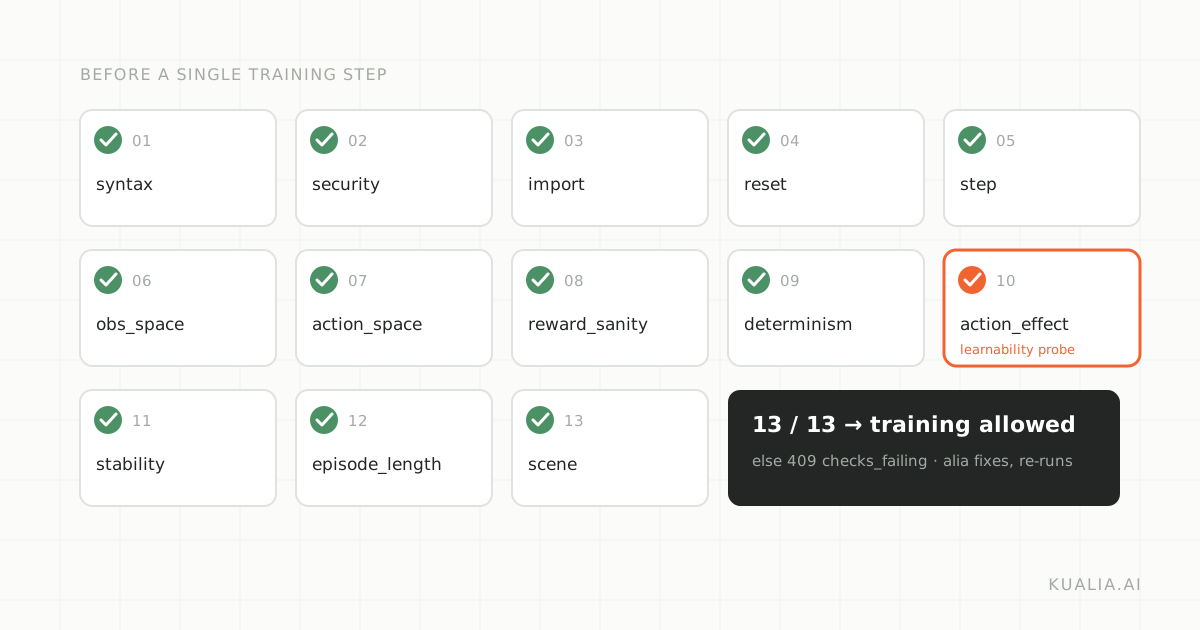 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
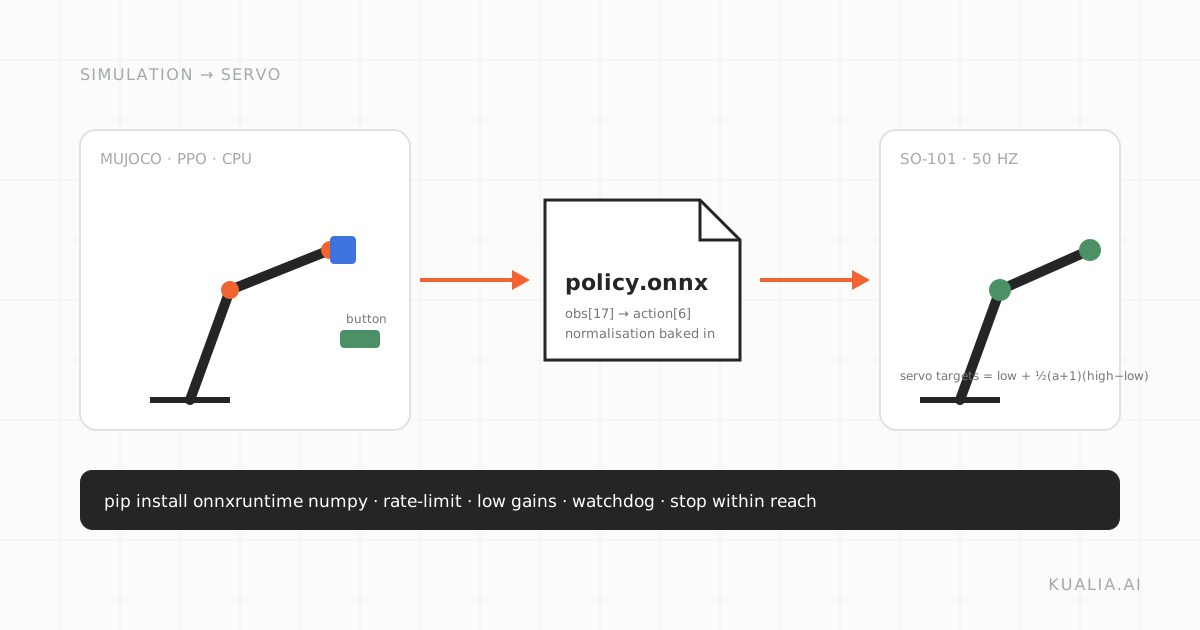 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
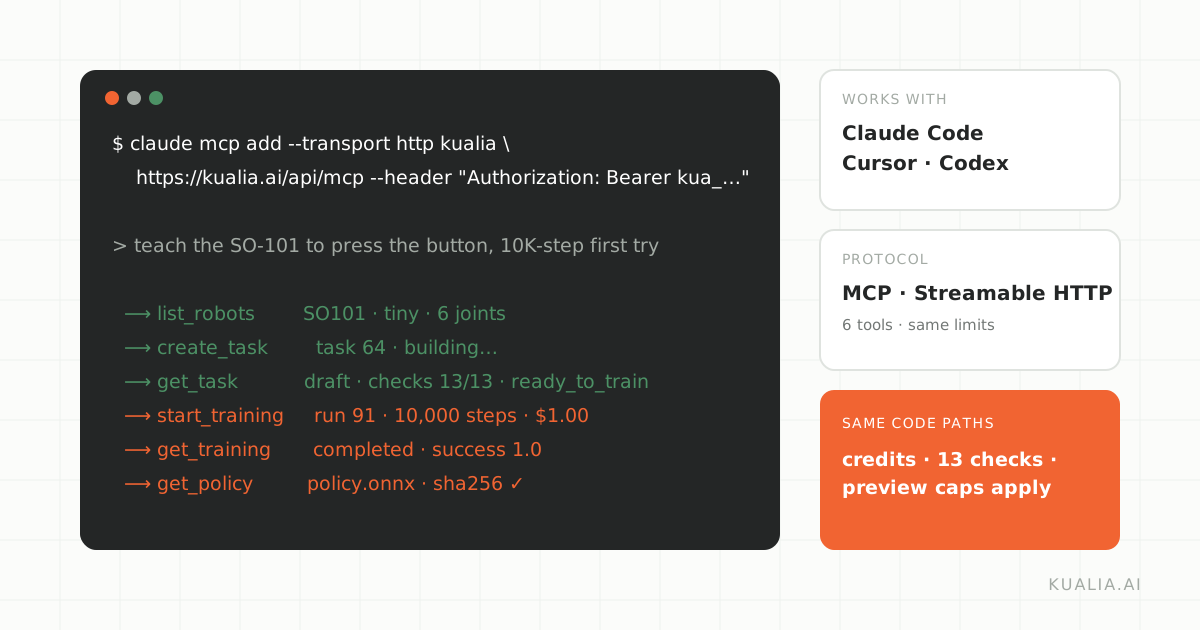 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 1 of 59
Jun 9, 2026Action Blindness: Why Embodied Spatial Intelligence Requires More Than Better PerceptionWhen we talk about spatial intelligence in machine learning, we usually frame it as a perception problem. Give the model better depth estimation, sharper segmentation, more accurate 3D reconstruction, and the spatial rea Jun 9, 2026When the Optimizer Becomes the Bottleneck: A Close Look at IndexCache Introduction Efficiency research in large language models often follows a predictable pattern. We identify a dominant cost, attack it with a clever approximation, and declare victory. Then, sometimes years later, we dis Jun 9, 2026Training Diffusion Models Without Data: A Look at DKDMThe dominant narrative in generative modeling has been that scale wins, and scale here means data. Stable Diffusion was trained on billions of image-text pairs. Imagen consumed over 15 billion images. The implicit assump Jun 9, 2026Decoding Structure, Not Just Category: What EEG-Based Visual Reconstruction Tells Us About the BrainFor more than a decade, the field of neural decoding has been chasing a deceptively simple goal: reconstruct what a person sees from recordings of their brain activity. The fMRI community has made the most visible progre Jun 8, 2026Trustworthy Reasoning as an Organizational Property: Inside the MAKA Architecture for ManufacturingWhen we talk about deploying large language models in high-consequence industrial settings, the conversation usually fixates on the model itself. Is it large enough? Is it fine-tuned on the right corpus? Does it hallucin Jun 8, 2026When Are Two Networks the Same? A Closer Look at Tensor Similarity Introduction One of the quietly foundational questions in mechanistic interpretability is deceptively simple: when do two neural networks, or two parts of a network, compute the same thing? The question matters because Jun 8, 2026Zeroth-Order Fine-Tuning Was an Inference Workload All AlongWhen we think about fine-tuning a large language model, we almost reflexively picture a training loop: forward pass, backward pass, gradient accumulation, optimizer step. The mental model is so ingrained that even method Jun 8, 2026When the Mutation Operator Learns to Think: Analyzing AVOEvolutionary search has a long and somewhat awkward relationship with large language models. For the past few years, the dominant pattern has been to take a powerful coding model and wedge it into a slot that was previou Jun 8, 2026When the Judge Hallucinates: On the Reliability of Learned 3D Consistency Metrics The Problem With Asking a Reconstructor to Be a Referee There is a quiet assumption baked into nearly every multiview 3D pipeline: that the images we feed in are genuine observations of one static scene. We assume the p Jun 8, 2026The UnEmbedding Matrix as a Feature Lens: Why LLM Embeddings Get Distracted by Common Words Introduction Large language models are excellent generalists. They translate, summarize, reason, and code with little task-specific tuning. Yet when we ask them to perform one of the most fundamental operations in moder Jun 8, 2026Learning the Prior: Online Bayesian Meta-Learning for Cognitive Radar Introduction A radar that tracks a single target in a single environment can, in principle, learn an effective transmission policy by trial and error. The difficulty arrives when the world changes. A cognitive tracking Jun 8, 2026Inverse Graphics Without Differentiable Rendering: What Staged Reconstruction Tells Us About VLM PriorsInverse graphics has been one of the oldest aspirations in computer vision, going back to Roberts' "Blocks World" in 1963. The goal is deceptively simple to state and notoriously hard to achieve: take a single image and Jun 8, 2026Why Long Video Generation Needs Explicit Identity, Not Implicit AttentionLong video generation has a memory problem, and it is the same memory problem that long-context language models have. A model generates a coherent opening scene, introduces a character named Nora in a beige sweater, and Jun 8, 2026Why Your VLA Safety Checker Is Watching the Wrong Signal Introduction Robot policies built on vision-language-action (VLA) models have moved fast from research demos to deployable systems, but the engineering scaffolding around them has not kept pace. There is a quiet assumpt Jun 8, 2026Teaching RNNs to Remember Without Unrolling TimeFor three decades, the central obstacle to training recurrent neural networks has not been the architecture itself but the way we assign credit through it. Backpropagation through time (BPTT) remains the default method, Jun 8, 2026Reconsidering the Spectral Story in Graph Neural NetworksFor nearly a decade, the field of graph representation learning has carried two parallel narratives about how its models work. One is the message-passing story, where nodes iteratively aggregate information from their ne Jun 7, 2026Causal Tokenization Meets MeanFlow: A Closer Look at CaTokVisual tokenization sits at an awkward intersection of two design philosophies. Autoregressive language models thrive on causal sequences, where each token depends only on those before it, enabling clean next-token predi Jun 7, 2026TextSeal and the Economics of Watermarks That Survive DistillationWhen a watermarking scheme works, the interesting questions are rarely about whether it can mark a single document. They are about what happens when that marked text travels: through paraphrasing, through translation, th