engineeringsafety September 25, 2026 6 min read
13 checks before a single training step
alia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
By kualia team
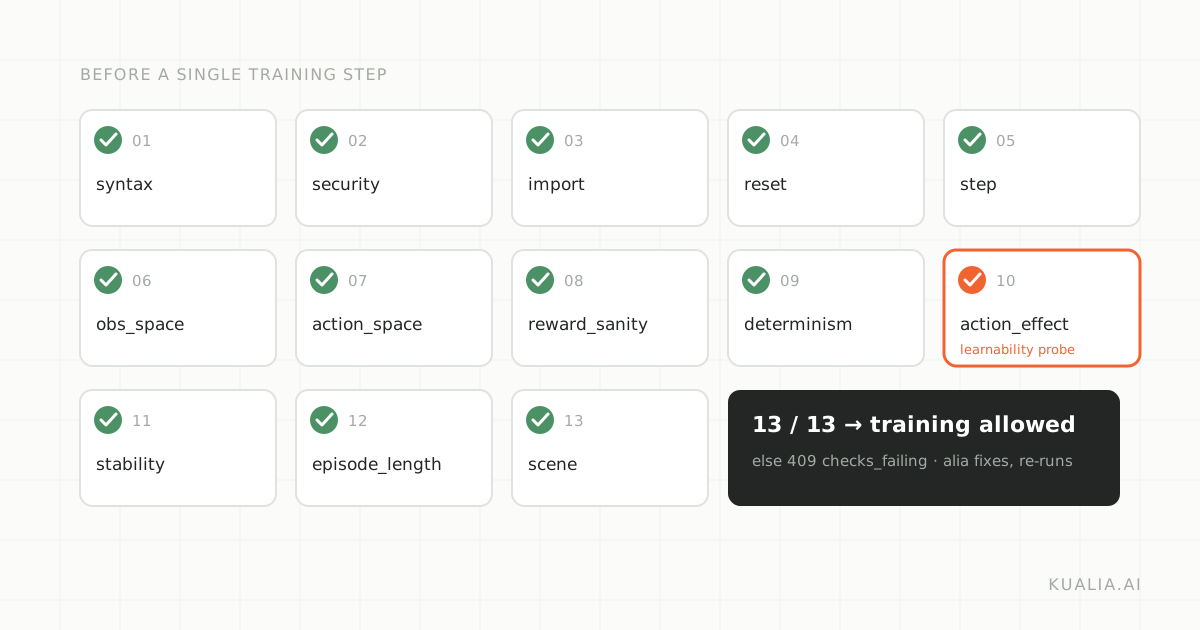
In kualia the training task is written by a language model. That is the point of the product, and it is also the risk. Model-written code fails in two ways: loudly, when it crashes at import, and quietly, when it runs perfectly and teaches the robot nothing. The quiet failures are the expensive ones, because you only discover them after paying for a run.
So every task version, whether it came from the first brief or from a chat change, runs through 13 automated checks before training is allowed. This post lists all of them, says what mistake each one exists to catch, and explains what happens when one fails.
How the checks run
The first two checks are static and run before any generated code executes. The other eleven each run in their own subprocess, in parallel, with a 20-second limit. The subprocess gets a copy of the environment with every secret-looking variable removed, so a task cannot read an API key even if it tried. Nothing from the task ever runs inside the web server.
The setup checks
1. Code parses (syntax). The file must be valid Python. If it is not, every other check is skipped and reported as failed.
2. Security scan (security). A static walk over the syntax tree looks for imports of blocked modules (subprocess, socket, requests, pickle, ctypes, importlib, shutil, pathlib and about twenty more), for calls to eval, exec, compile or __import__, and for .system, .popen, .spawn or .fork calls. Any hit stops the run before the code executes. A training task only needs gymnasium, numpy, math and kualia_sim.
3. Environment loads (import). The checker finds the most-derived gymnasium.Env class in the file, instantiates it with no arguments and confirms it has an observation space and an action space. This catches constructors that require parameters and base-class calls with the wrong arguments.
4. Reset works (reset). reset(seed=42) must return a two-tuple: a NumPy array and an info dict.
5. Step works (step). One random action must return the five-tuple of observation, reward, terminated, truncated and info, with the right types. A step that returns None on one code path fails here.
The physics checks
6. Observation signals (obs_space). The first observation and ten more after random steps must all lie inside the declared observation space. The usual cause of failure is appending task features without widening the space, or a dtype mismatch. For kualia_sim tasks the detail message also names the offending override when a task has reimplemented reset or step instead of using the hooks.
7. Action space valid (action_space). One hundred sampled actions must lie inside the action space, and stepping with one must work.
9. Deterministic reset (determinism). Two 20-step rollouts with the same environment seed and the same action seed must produce identical observations and rewards. This catches np.random used instead of self.np_random, and seeds that are not passed through to the robot's own reset. Without it, nothing in training or evaluation is reproducible.
11. No unstable physics (stability). Three rollouts of up to 300 steps, one of them driven with saturated bang-bang actions: all-high, all-low, alternating. Observations and rewards must stay finite, observations must stay inside any finite declared bounds, the largest observation magnitude must stay below one million, and at least one episode must end. This is where joint explosions, unbounded velocities and rewards that divide by zero show up.
13. Objects start clear (scene). For tasks with world objects, three resets must place every object clear of the robot and of each other and above the floor, and a 60-step random rollout must keep every object physically sane: no speeds above 60 m/s, nothing falling through the floor. The check also fails when the SCENE lacks an object type the world planner decided on, which is how kualia stops a model from "simulating" a ball in Python instead of putting a real body in the world. On an open floor the check passes trivially.
The learning checks
8. Reward is sane (reward_sanity). One hundred random steps must produce numeric, finite rewards that are not all identical. Values outside [-10, 10] are allowed but flagged, because training normalises rewards and a term that dwarfs the others hides them.
10. Learnability estimate (action_effect). This is the check we care about most. Over five seeds, the 50-step return under random actions is compared with the return under a constant zero action. If the two are the same to within a millionth, the reward does not depend on anything the robot's actions change. That task will train without error, produce a flat curve, and waste the whole budget. A reward built on the step counter, on passive drift, or on the wrong variable fails here.
12. Episodes survive reset (episode_length). Five random-action episodes must last more than two steps on average. The classic mistake is a termination threshold that already fires at the start pose: a height test on a quantity that is relative to the start and therefore zero, or "stay above 1.3 m" on a robot that starts at 1.25 m. Every other check passes on such a task, training runs, and the policy learns nothing. The check also reports the episode cap the code actually enforces, so the Studio shows the true steps per episode.
The gate
Training starts only when all 13 pass. The server enforces this: a start request on a task with failing checks is refused with 409 checks_failing, so no credits are spent on a broken task. There is a second, softer bar for publishing a task to the catalog: at least nine checks passing and, whatever the total, the learnability estimate must be among them. A task that is well-formed but unlearnable is not a product artifact.
What happens when a check fails
alia does not get to mark its own homework, but it does get to resubmit. When a check fails, the failing checks and their detail messages are sent back with the spec and the code, and alia is asked to diagnose the root cause and return the complete corrected file. The corrected file runs through all 13 checks again. This repeats up to four times when a plan is first built and up to three times after a chat change.
The loop keeps the best-scoring version at every step: a fix that passes fewer checks than the current best is discarded, so a bad repair can never replace a better one. If the model returns the same code twice in a row, the loop stops rather than spending your credits on nothing.
If checks still fail after the automatic attempts, the Plan page shows each one with its detail message. Ask assistant to fix sends exactly those failures to alia with the instruction to change nothing else. The messages are written for that purpose: "Episodes end immediately under random actions (mean length 1.0 over 5 episodes). A termination or success condition fires at the reset state; check thresholds against the initial pose." A fix usually lands on the first try.
What the checks do not promise
Thirteen passing checks mean the task is well-formed, reproducible, physically stable and learnable in principle. They do not mean the reward describes the behaviour you want. A Walker that is paid for ball speed in any direction will learn to fling the ball sideways, and every check will pass. Whether the trick is the right trick is something only training, the recorded episodes and the run analysis can tell you.
Try it
Build any task in the Dashboard and open Plan & world: each of the 13 checks is listed with its detail message, and Re-run lets you watch them execute. The full reference for every check is in the documentation.