workflowopen-duck-mini September 29, 2026 6 min read
From a sentence to a walking duck: how kualia turns a plain-language brief into a training task
A walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.
By kualia team
The Open Duck Mini v2 is a 3D-printed desk biped, about 35 cm tall, with 16 position-controlled joints: hips, knees and ankles on each leg, plus a neck, a head and two antennas. People build it at home. Teaching it to walk is a real reinforcement-learning problem, and it is the kind of problem kualia is built for.
This post follows one brief through the whole system: "Walk up a small ramp without falling." No code is written by hand at any point. Here is what happens at each stage, and what is actually going on underneath.
The brief
On the Dashboard you pick a robot and describe the trick. kualia turns the form into a plain-text brief and sends it to alia, its task-writing assistant. For the Duck it looks like this:
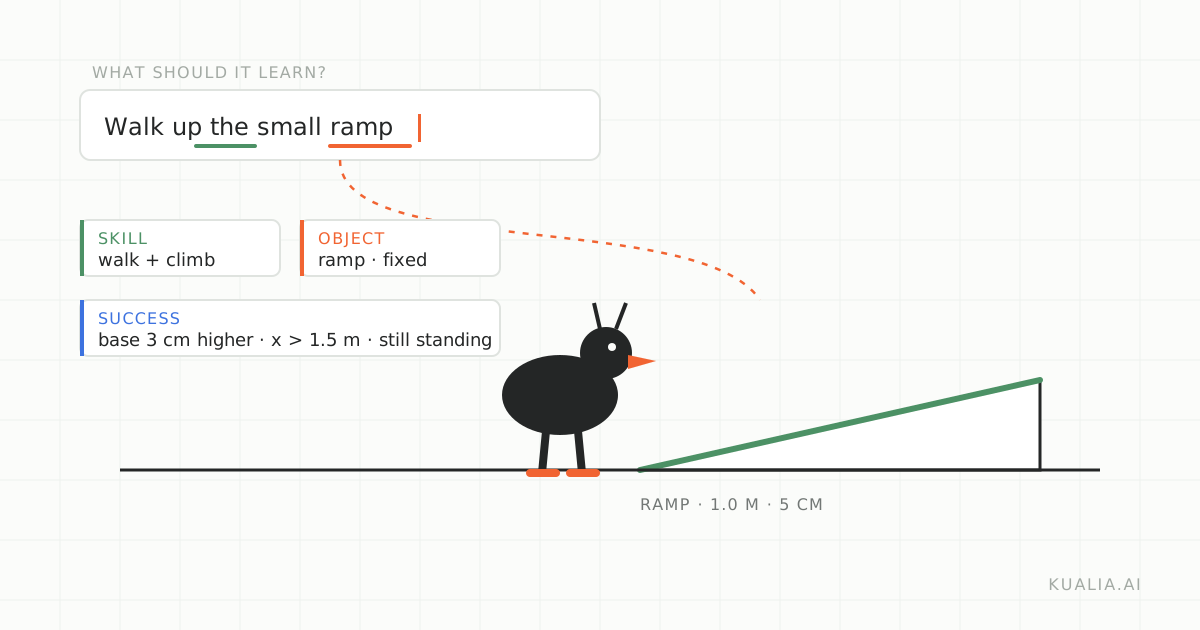
Walk up a small ramp without falling.

Success criterion: choose one measurable criterion (distance, speed, height or time)
that fits this trick and is reachable from the reset pose.

Avoid: Avoid falling, jerky motion and excessive joint torque.

Reward style: Use dense reward shaping that rewards progress every step.

Implement the success criterion explicitly in info['is_success'].
You can write your own success criterion instead of letting kualia pick one. Good briefs describe one skill with something measurable at the end; "walk up the ramp and then dance" is two tricks and should be two versions.
The world planner decides what exists
Before any code is written, a short model call reads the brief and decides which physical objects the trick needs. There are nine object types in kualia: ball, box, step, ramp, wall, goal, target, knob and button. "A small ramp" maps to one ramp. "Walk forward" would map to nothing at all, because distances are measured from the robot itself.
The planner also gets facts about the Duck's world: objects should sit 0.3 to 1.0 m ahead, step risers should stay at or below 3 cm, and a fall means the base drops below 9 cm or tilts over. Its decision is binding. alia is told the SCENE must contain exactly one ramp, and one of the checks later fails if it does not.
alia writes the plan and the task
One request to alia returns two things: a structured training plan (the trick in one sentence, a three-to-five step success scenario, reward terms, termination and success rules) and the complete Python task. The task is a subclass of kualia's MjcfRobotEnv runtime, which loads the Duck's MuJoCo model with a free-floating base and its standing pose, adds the ramp, maps actions to actuators and builds the observation. alia only fills in the hooks. The result is the kind of code below (an illustration, not a transcript of a specific run):
import numpy as np
from kualia_sim import MjcfRobotEnv, menagerie_asset


class WalkUpRamp(MjcfRobotEnv):
    ROBOT_ASSET = menagerie_asset("Duck")
    CONTROL_HZ = 50
    SCENE = [
        {"type": "ramp", "name": "ramp", "pos": [1.0, 0.0], "length": 1.0, "width": 0.6, "height": 0.05},
    ]

    def on_reset(self):
        self.prev_x = self.x_position

    def compute_reward(self, action):
        progress = 5.0 * (self.x_position - self.prev_x)
        self.prev_x = self.x_position
        climb = 2.0 * (self.base_height - self.initial_base_height)
        effort = 1e-3 * float(np.sum(np.square(action)))
        return float(np.clip(progress + climb + 0.5 * self.upright - effort, -10.0, 10.0))

    def is_success(self):
        return self.x_position > 1.5 and self.base_height > self.initial_base_height + 0.03
A few things are fixed by the runtime and cannot be changed by alia: the robot's bodies, joints and actuators; the observation, which is the Duck's proprioceptive values (joint positions with the base's world x and y dropped, then joint velocities); the action, one value in [-1, 1] per actuator where zero holds the standing pose; and the default termination, which ends an episode when the base falls below half its start height or the robot flips. The ramp is a fixed piece of geometry, so it is not part of the observation; the policy has to learn the slope from what its legs feel.
Success is read only at the end of a full episode. If the Duck reaches the top and then falls, it is not a success, so the task never terminates on success and the robot has to hold its position until the time limit.
Thirteen checks, then repairs
The generated task now runs through 13 automated checks in an isolated sandbox: does the file parse, is it free of blocked imports, does it load, reset and step correctly, do observations stay inside their declared space, are rewards finite and non-constant, is a seeded rollout reproducible, do random actions change the return at all, does the physics stay bounded under saturated actions, do episodes survive the reset pose, and does the ramp start clear of the robot and behave physically.
If any check fails, alia is shown the failure details and asked to fix the code, up to four attempts, always continuing from the best-scoring version. Training cannot start until all 13 pass; the server refuses the run otherwise. Building a plan usually takes one to three minutes and is billed by actual model usage, shown as an estimate of about $0.40 before you click.
Plan & world: look before you pay
The Plan page shows the trick restated for this version, what success looks like step by step, the reward explanation, the generated code and the 13 checks. The World panel renders the exact composed scene in MuJoCo compiled to WebAssembly, in your browser. Press play for a zero-torque drop test: the Duck collapses under gravity and the ramp should sit still. Objects that jump or fly away are overlapping something, and this is the moment to tell alia to move them.
Any change you ask for creates a new version, re-runs the checks and keeps the old version available. Runs stay pinned to the version they trained on.
Training and watching
Training runs on kualia's CPU servers with PPO from Stable-Baselines3. Observations and rewards are normalised with running statistics. The Studio offers three budgets at $0.10 per 1,000 steps: a 10K-step first try for $1, a 50K-step practice run for $5, and a robot-specific "Learn it" budget, which for the Duck is around 2M steps, or $200.
Be honest with yourself about what a first try shows. On a 16-joint biped, 10,000 steps is a handful of PPO updates. The point of the first run is to see whether episodes last longer than a second, whether the reward rises and whether the Duck is heading up the ramp rather than sideways. A gait comes from the long budget, or from several runs chained with Keep training.
While the run goes, the untrained policy is recorded first, then checkpoints at 25, 50 and 75 percent and the final policy. From the 25 percent checkpoint on, the newest policy is exported to ONNX and runs live in the browser simulator with onnxruntime-web, in the same MuJoCo world, refreshing as new checkpoints land. You can push the Duck sideways with a button to see whether it recovers. After training, the final policy plays up to 30 deterministic evaluation episodes, and the results page shows how many succeeded with a 95% interval, so you can tell a lucky run from a reliable one.
Results, analysis, next version
The results page lists the evaluation episodes, marks which ones ended early, and shows an AI analysis of the run: a short summary, observations with severity, and concrete proposed changes with current and proposed values. One click sends the instruction to alia, which writes the next version and re-runs the checks. The rhythm that works: a short run, one change, compare the two runs, then spend the long budget when the direction is right.
Export
When a run is worth keeping, Export produces a single ONNX file: the deterministic policy with the observation normalisation baked in as its first layer, actions clipped to bounds, metadata embedded, and a SHA-256 checksum. On the robot you need onnxruntime and numpy, nothing from PyTorch or Stable-Baselines3. The export is verified against the original policy on random observations before it is handed to you.
How fast can this be?
The Duck is at the slow end. At the fast end, a reach task on the two-servo Dynamixel 2R arm was built in about two minutes with all 13 checks passing, and a 10K-step PPO run finished in roughly 80 seconds with 100 percent success across its evaluation episodes. That is a toy problem, but it shows the loop end to end in the time it takes to make coffee.
Try it
Pick the Open Duck Mini on the robot page, or start with something that learns in one short run. Open the Dashboard, describe the trick in a sentence, and watch what alia builds. New accounts start with a small credit balance, enough for a plan and a first try.