Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
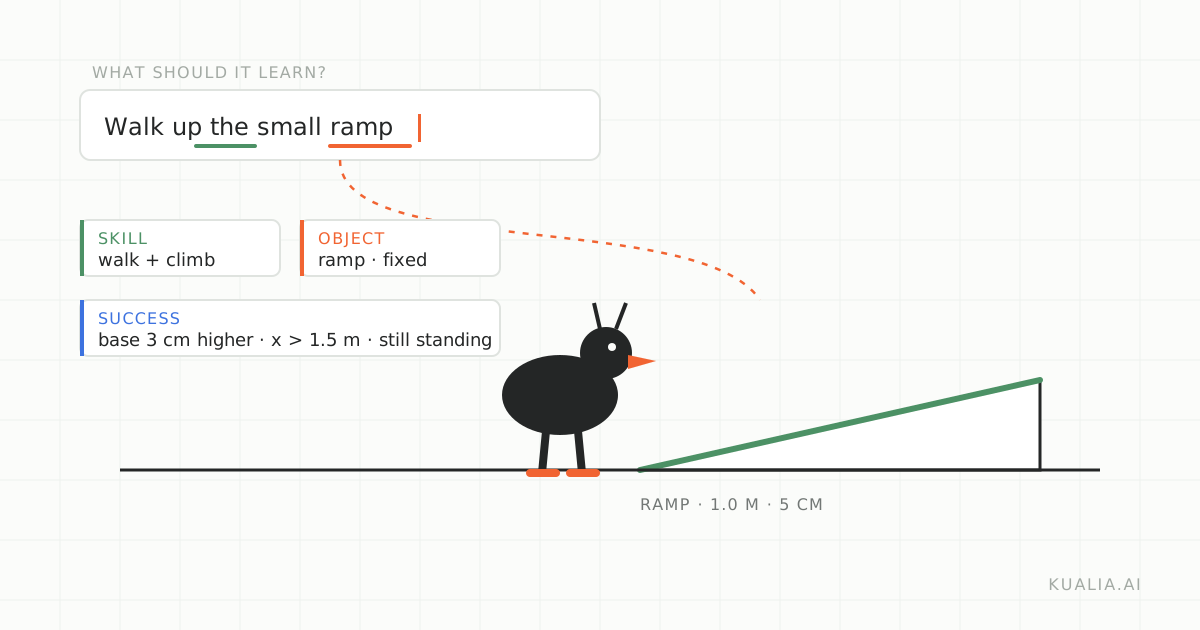 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
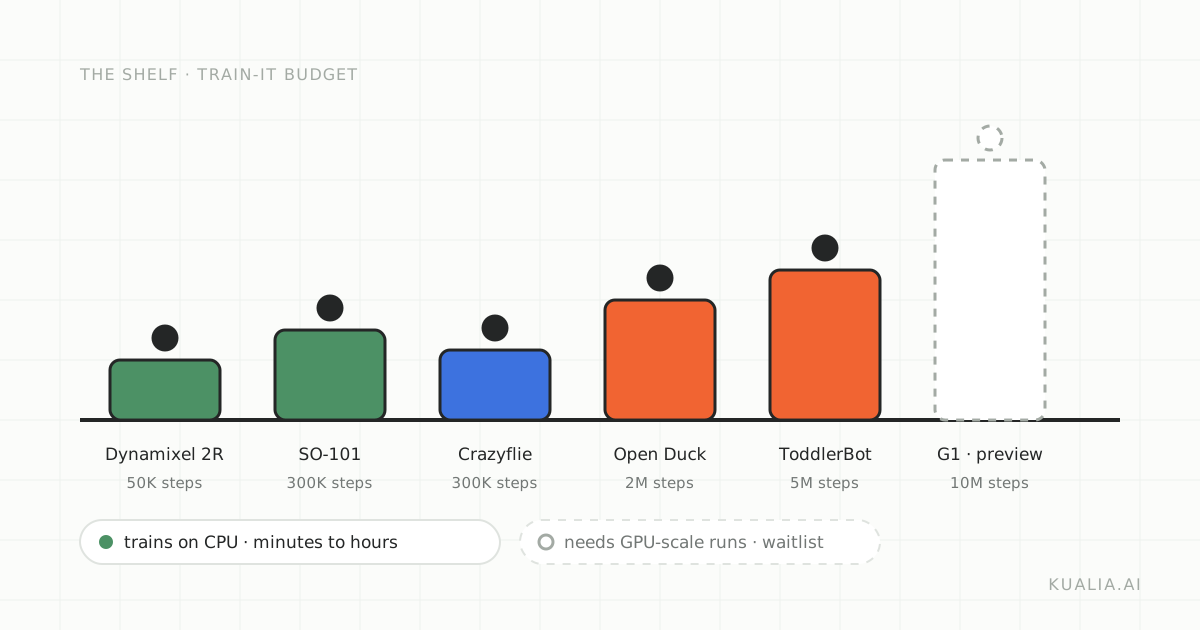 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
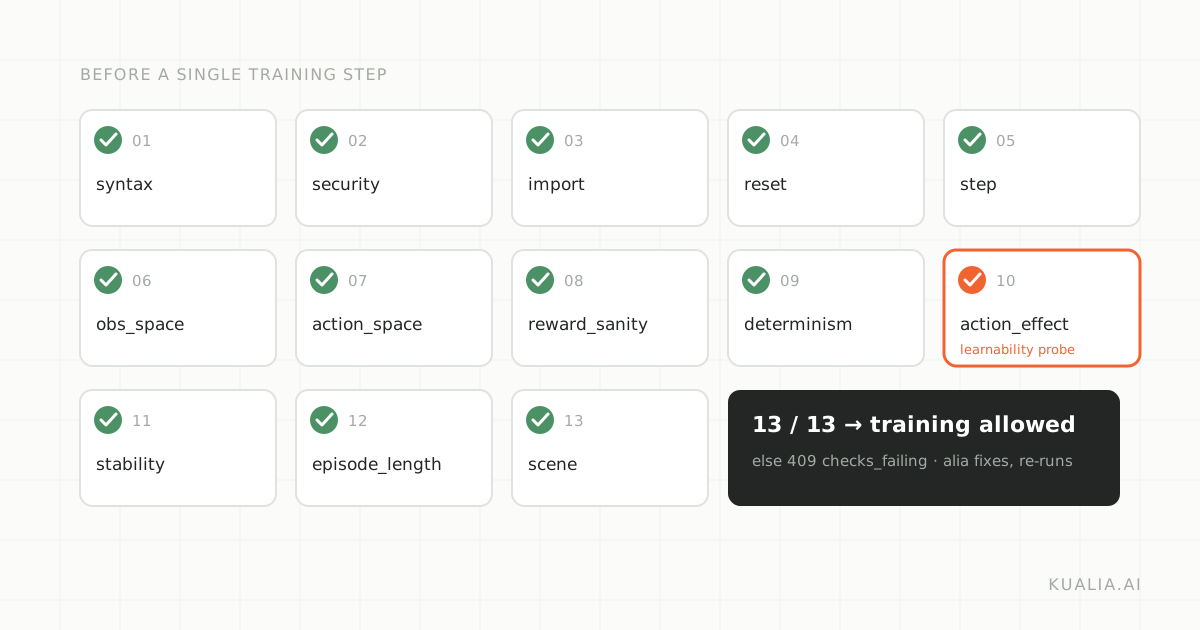 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
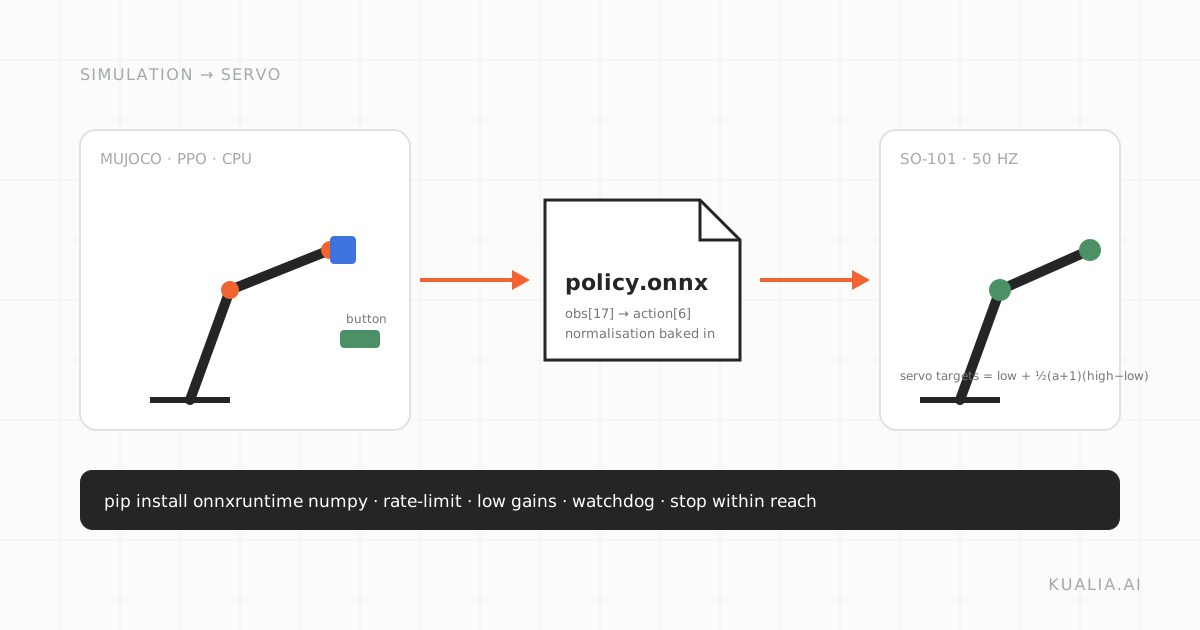 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
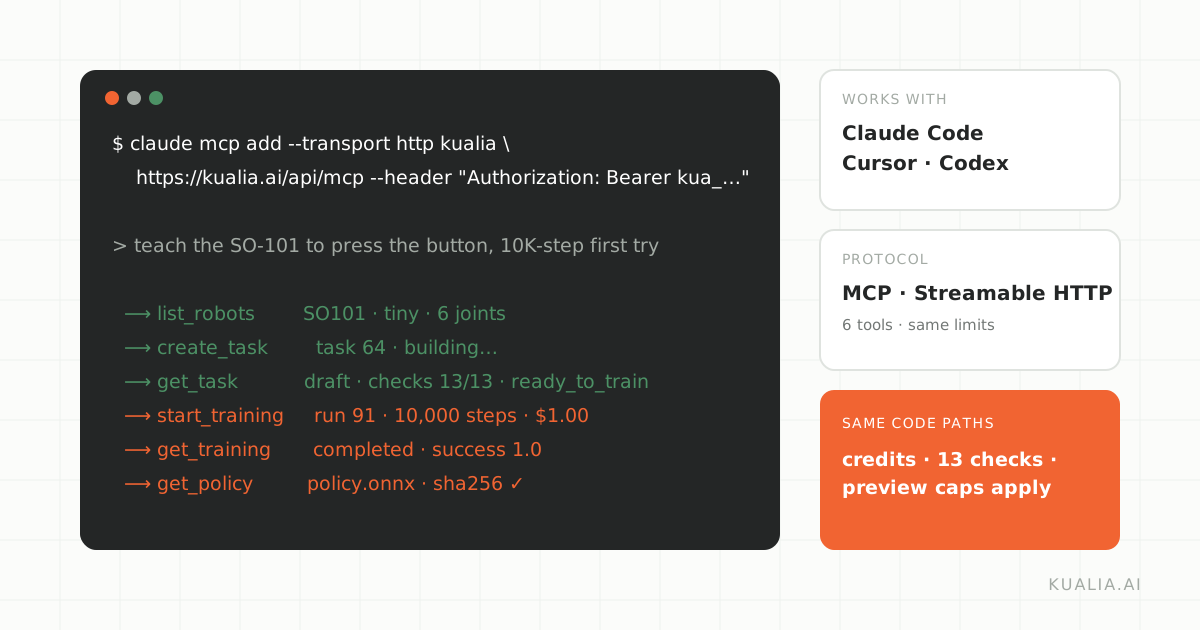 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 38 of 59
Apr 5, 2026F2LLM-v2: Rethinking Multilingual Embeddings Through Data Curation Over Model ScaleThe recent release of F2LLM-v2 by researchers at Ant Group and Shanghai Jiao Tong University presents a compelling challenge to the prevailing wisdom in multilingual natural language processing. While the field has large Apr 5, 2026Vision-Based UAV Navigation: How Privileged Learning Bridges the Observation GapAutonomous UAV navigation remains one of the most challenging problems in robotics, requiring real-time decision making under partial observability and environmental uncertainty. A recent paper titled "Vision-Based Deep Apr 5, 2026Transformers Meet Compilers: How Deep Learning Could Reshape Automatic Loop ParallelizationThe quest for automatic parallelization has been a decades-long challenge in compiler optimization, with traditional static analysis techniques hitting fundamental walls when confronted with the messy realities of real-w Apr 4, 2026Parallel Newton Methods for Sequential Models: When Dynamical Stability Becomes a Computational ResourceThe tension between sequential computation and parallel hardware has been one of the defining challenges in modern machine learning. Recurrent neural networks, Markov chain Monte Carlo, and other sequential models seem f Apr 4, 2026AI Agents in High Energy Physics: The End of Manual Analysis Pipelines?A new paper from MIT and CERN researchers, "AI Agents Can Already Autonomously Perform Experimental High Energy Physics," presents compelling evidence that we've reached an inflection point in scientific computing. The w Apr 4, 2026Unified Language Models: How GRIT Points Toward the End of Separate Retrieval and Generation SystemsThe artificial intelligence research community has long pursued the goal of creating unified models capable of handling diverse tasks with equal competence. A new paper titled "Generative Representational Instruction Tun Apr 4, 2026Quantum-Inspired Tensor Networks Meet Real-Time Physics: A Bridge to Future Collider ComputingThe intersection of quantum-inspired computing and experimental particle physics has produced an intriguing development that deserves careful analysis. A recent paper titled "Hardware-Aware Tensor Networks for Real-Time Apr 4, 2026Testing the Creative Limits of Large Language Models: What CREATE Reveals About Associative ReasoningThe field of AI has made remarkable strides in developing models that can reason, write, and solve complex problems. Yet one frontier remains particularly elusive: genuine creativity. A new benchmark called CREATE, intro Apr 4, 2026Adaptive Computation in Diffusion Models: How ELIT Challenges the Uniform Resource Allocation ParadigmThe field of diffusion models has witnessed remarkable progress in recent years, with Diffusion Transformers (DiTs) emerging as the backbone architecture for state-of-the-art image generation systems. However, beneath th Apr 4, 2026Proxy Models as Training Guides: How Small Networks Can Optimize Large Language Model CurriculaThe field of large language model training has reached a fascinating inflection point. While scaling laws continue to drive impressive performance gains, the sheer computational cost of training these models has research Apr 4, 2026Hierarchical Intelligence in Robotics: Why the LLM-RL Split Makes Sense for Manipulation TasksThe intersection of large language models and reinforcement learning represents one of the most promising directions in modern robotics. A recent paper by Saad et al., "Hybrid Framework for Robotic Manipulation: Integrat Apr 4, 2026System Design for Lifelong Reinforcement Learning: Moving Beyond Single-Task OptimizationThe reinforcement learning community has achieved remarkable success in training agents to master individual tasks, from defeating world champions in Go to controlling robotic systems with superhuman precision. However, Apr 4, 2026Debunking the Curse of Multilinguality: New Evidence on Language Model PretrainingThe field of multilingual natural language processing has long grappled with a seemingly fundamental trade-off: the more languages you include in pretraining, the worse your model performs on each individual language. Th Apr 3, 2026Time Adaptive Reinforcement Learning: Towards Zero-Shot Temporal Flexibility in AI AgentsThe field of reinforcement learning has achieved remarkable successes, from mastering complex board games to controlling robotic systems. Yet a fundamental limitation persists: most RL agents are trained for fixed tempor Apr 3, 2026XFT: Rethinking Code Instruction Tuning Through Mixture-of-Experts UpcyclingThe field of code language model training has been dominated by a singular focus: better data. From Evol-Instruct's synthetic complexity evolution to OSS-Instruct's open-source code inspiration, researchers have poured e Apr 3, 2026MegaFlow: Rethinking Optical Flow Through Global Vision PriorsThe computer vision community has long grappled with a fundamental tension in optical flow estimation: the need to capture both large displacements and fine-grained motion details. A new paper, "MegaFlow: Zero-Shot Large Apr 3, 2026When Chain-of-Thought Becomes Performance Art: Understanding Reasoning Theater in Large Language ModelsThe recent paper "Reasoning Theater: Disentangling Model Beliefs from Chain-of-Thought" by Boppana et al. presents compelling evidence that our reasoning models may sometimes be putting on a show. While chain-of-thought Apr 3, 2026Untangling Dynamics from Policy: A New Approach to Offline-to-Online RL AdaptationThe challenge of adapting reinforcement learning policies to non-stationary environments remains one of the most pressing problems in real-world AI deployment. While online learning allows agents to continuously adapt to