Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
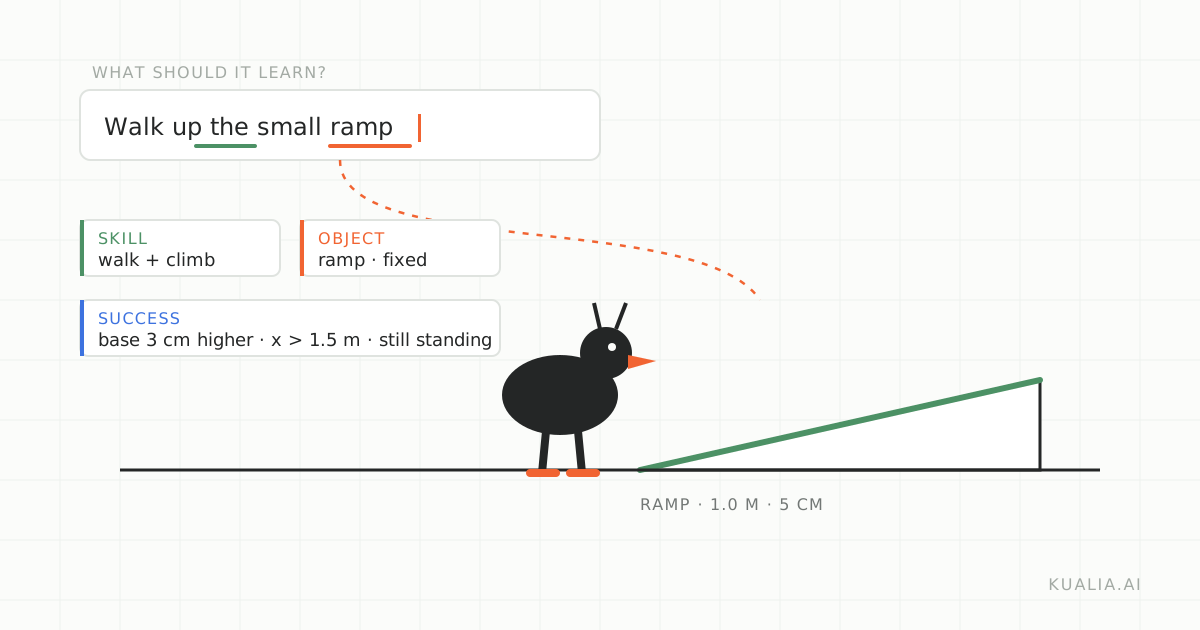 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
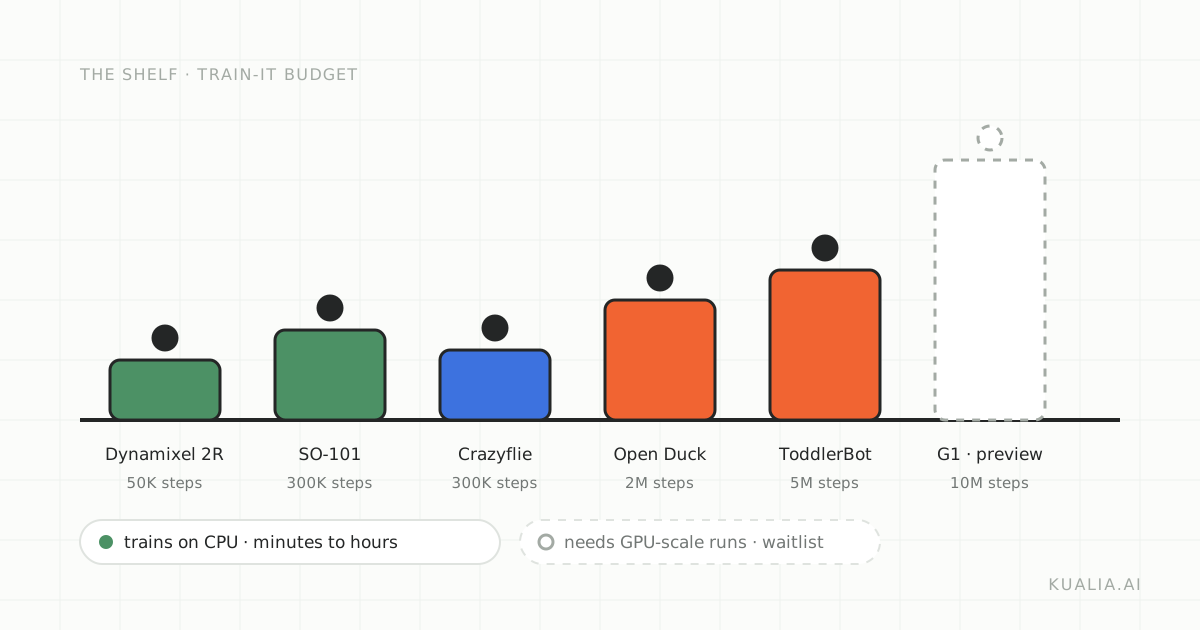 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
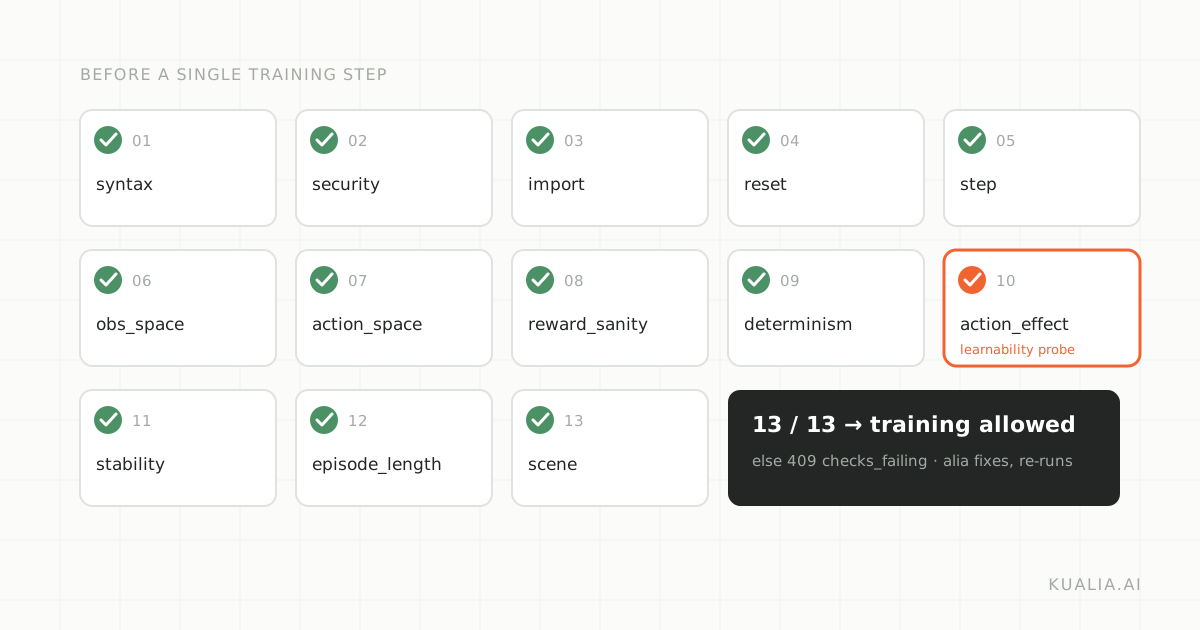 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
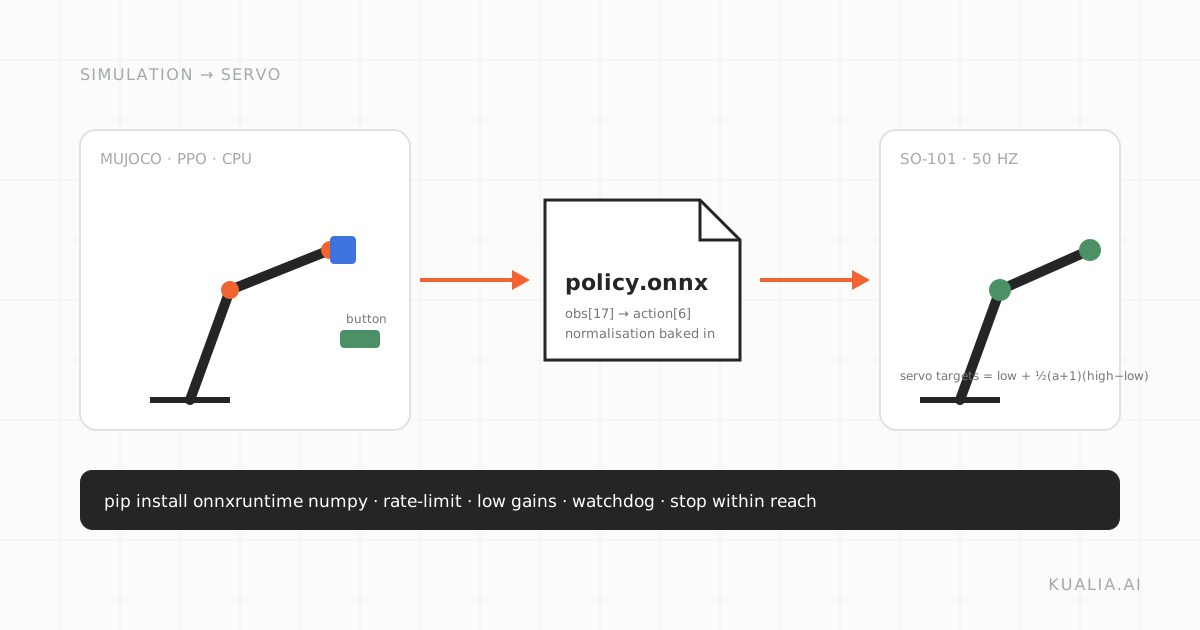 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
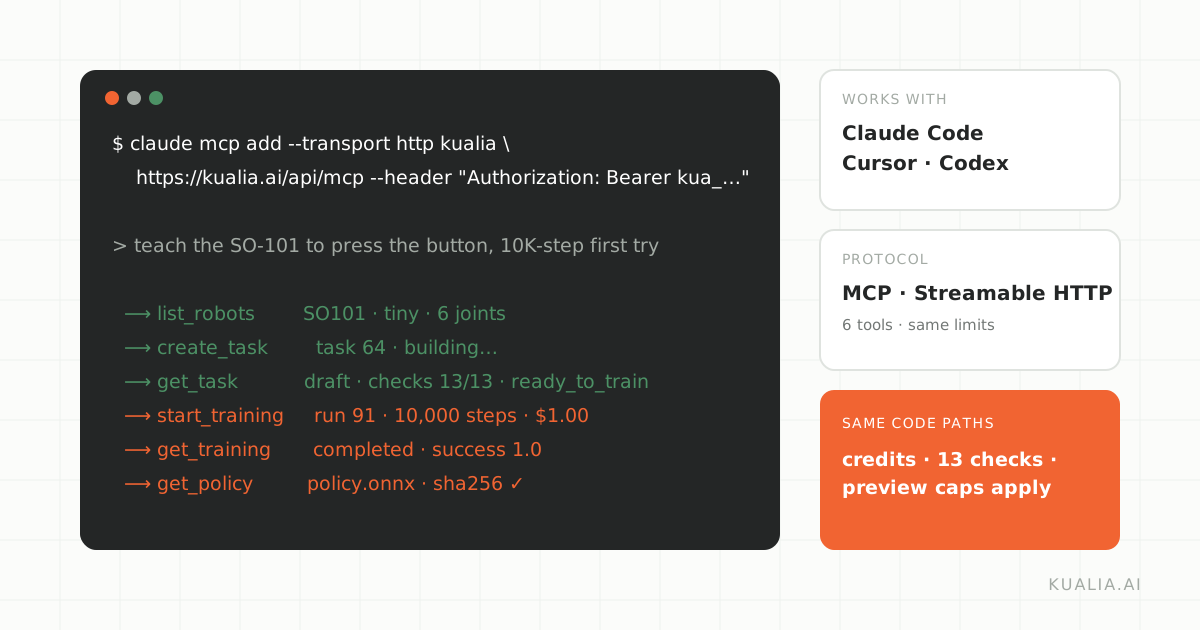 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 37 of 59
Apr 9, 2026Safe Policy Search for Lifelong Reinforcement Learning: Progress and Persistent ChallengesThe intersection of safety and lifelong learning in reinforcement learning has emerged as one of the most critical research areas as we move toward deploying autonomous agents in real-world scenarios. A recent paper titl Apr 8, 2026No-Regret Non-convex Online Meta-Learning: When Theory Meets the Messy Reality of Sequential LearningThe intersection of meta-learning and online learning has produced some fascinating theoretical developments, with the recent paper "No-regret Non-convex Online Meta-Learning" pushing these boundaries further into non-co Apr 8, 2026ContextClaim: Rethinking Verifiable Claim Detection Through Context RetrievalThe field of automated fact-checking has long approached claim detection as a purely textual classification task. Whether identifying check-worthy statements or determining verifiability, existing systems analyze claims Apr 8, 2026Single Layer Co4 Architecture Challenges Deep Learning Orthodoxy with Efficiency ClaimsThe recent paper "Single layer tiny Co4 outpaces GPT-2 and GPT-BERT" by Ul Zain et al. presents findings that could fundamentally challenge our understanding of neural network scaling and architectural depth requirements Apr 6, 2026Self-Supervised Flow Matching: Breaking Free from External Representation DependenciesThe generative AI landscape has long been characterized by an interesting paradox: models capable of producing stunning images, videos, and audio often rely on borrowing semantic understanding from entirely separate disc Apr 6, 2026DynVLA: Rethinking What Matters for Autonomous Driving DecisionsThe field of autonomous driving has been wrestling with a fundamental question: how should AI systems reason about the future before making driving decisions? A new paper, "DynVLA: Learning World Dynamics for Action Reas Apr 6, 2026Reasoning Coherence in Video Generation: Why More Guidance Doesn't Always HelpThe rapid advancement of video generative models has brought us to an interesting crossroads. While these models can produce visually stunning content with realistic temporal dynamics, a critical question remains largely Apr 6, 2026Rethinking the Foundation of Robotic Manipulation: Why Dynamic Training Beats Static PretrainingThe field of robotic manipulation has long operated under a seemingly logical assumption: master the basics first, then add complexity. Train robots on static objects in controlled environments, then gradually introduce Apr 6, 2026Bridging the Gap Between Financial Fundamentals and Market Dynamics: What FinTradeBench Reveals About LLM Financial ReasoningThe financial world operates on two distinct but interconnected dimensions: the fundamental health of companies as captured in their financial statements, and the dynamic behavior of markets as reflected in trading patte Apr 5, 2026Selective Visual Attention Proves Superior to Full Image Processing in Medical AIThe conventional wisdom in multimodal machine learning has long been "more data is better." Feed your model the complete image, multiple views, higher resolutions, and performance should improve. A new study titled "Less Apr 5, 2026Model-Free Reinforcement Learning in Non-Stationary Environments: Challenging the Model-Based OrthodoxyThe reinforcement learning community has long held that model-based methods are superior for handling non-stationary environments. The intuition seems sound: if the environment is changing, explicitly tracking those chan Apr 5, 2026Online Adaptation in RL: Why Echo State Networks Offer a Compelling Alternative to BackpropagationThe persistent challenge of deploying reinforcement learning policies from simulation to real-world environments has driven researchers toward increasingly sophisticated adaptation mechanisms. A recent paper titled "Onli Apr 5, 2026Back to Basics: Why Voice Agents Still Struggle Despite "Solved" Speech RecognitionThe field of automatic speech recognition has been riding high on a wave of apparent success. When major tech companies declared "human parity" in 2016-2017, achieving word error rates below 5% on curated benchmarks, man Apr 5, 2026LookaheadKV: Rethinking the Real Bottleneck in KV Cache EvictionThe pursuit of long-context language models has revealed an uncomfortable truth: memory isn't just about storage capacity. As transformer-based large language models (LLMs) push toward million-token contexts, the key-val Apr 5, 2026The Thicket Effect: Why Large Language Models Make Post-Training Surprisingly EasyA fascinating new paper from MIT CSAIL titled "Neural Thickets: Diverse Task Experts Are Dense Around Pretrained Weights" by Yulu Gan and Phillip Isola challenges a fundamental assumption about how we should adapt large Apr 5, 2026Taming the Intractable: How XOR-SMOO Bridges Multi-Objective Optimization and Probabilistic InferenceMulti-objective optimization problems are everywhere in the real world. Supply chain managers must balance cost against reliability. Network designers trade off performance versus robustness. Energy planners optimize eff Apr 5, 2026Measuring Cultural Bias in Language Models: What Author Profiling Reveals About AI WorldviewsThe conversation around bias in large language models has largely focused on the obvious manifestations: toxic outputs, factual inaccuracies, or overtly discriminatory responses. But a new study titled "Probing Cultural Apr 5, 2026CORA: A Critical Infrastructure Step Toward Practical Continual Reinforcement LearningThe field of continual reinforcement learning sits at a fascinating crossroads between ambitious theoretical goals and practical implementation challenges. While the vision of agents that can learn continuously across di