Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
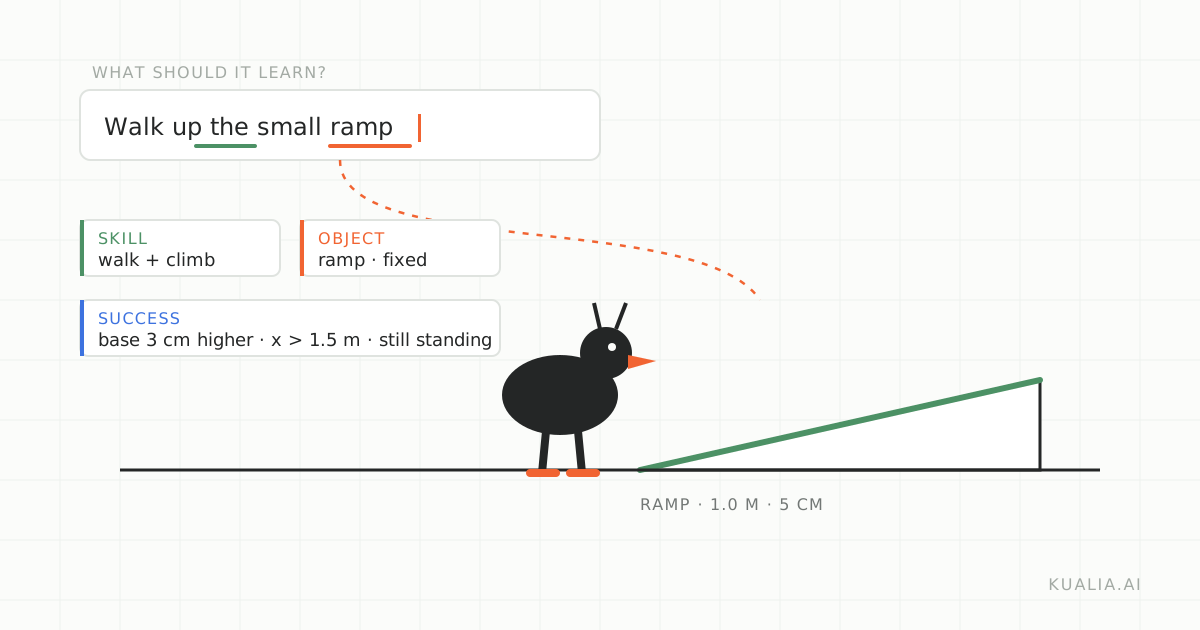 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
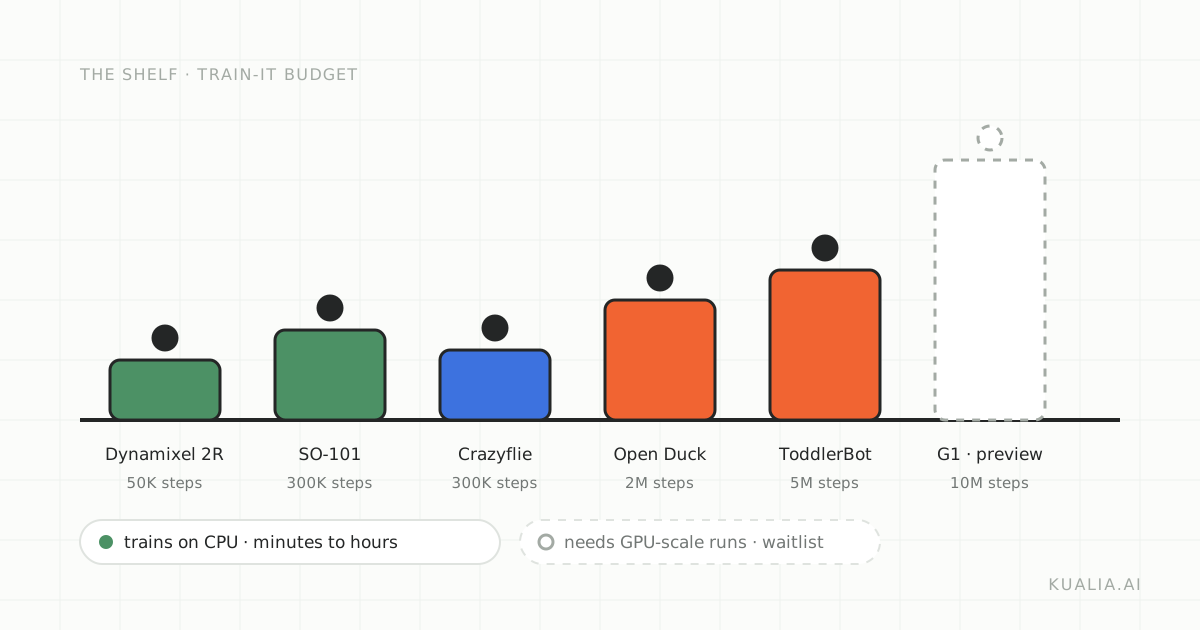 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
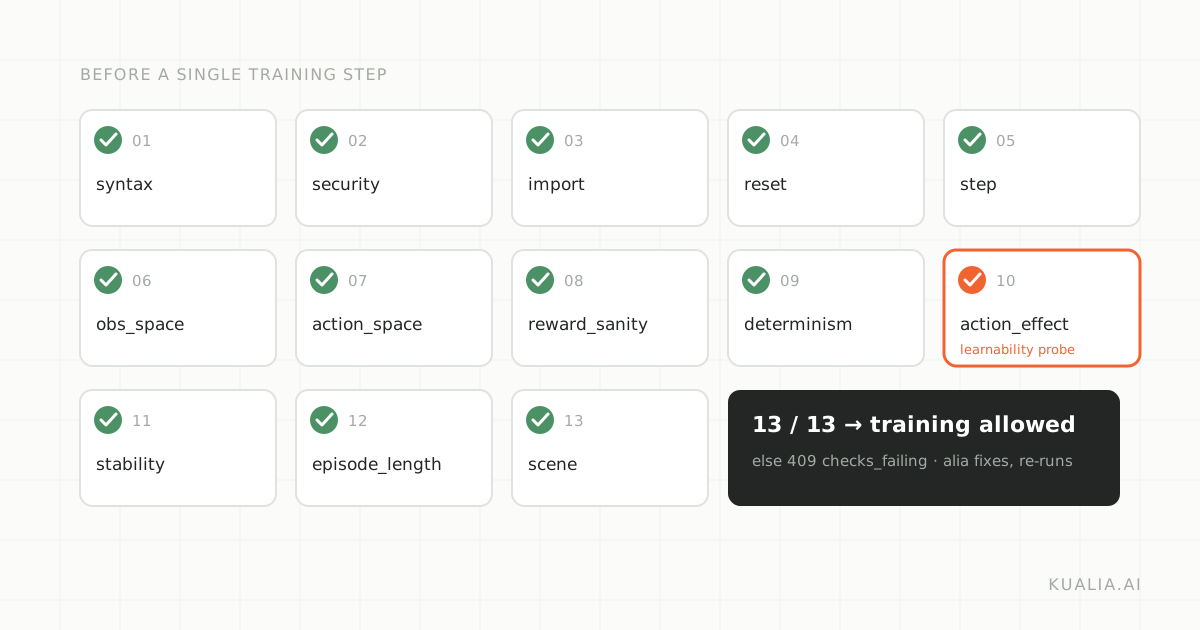 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
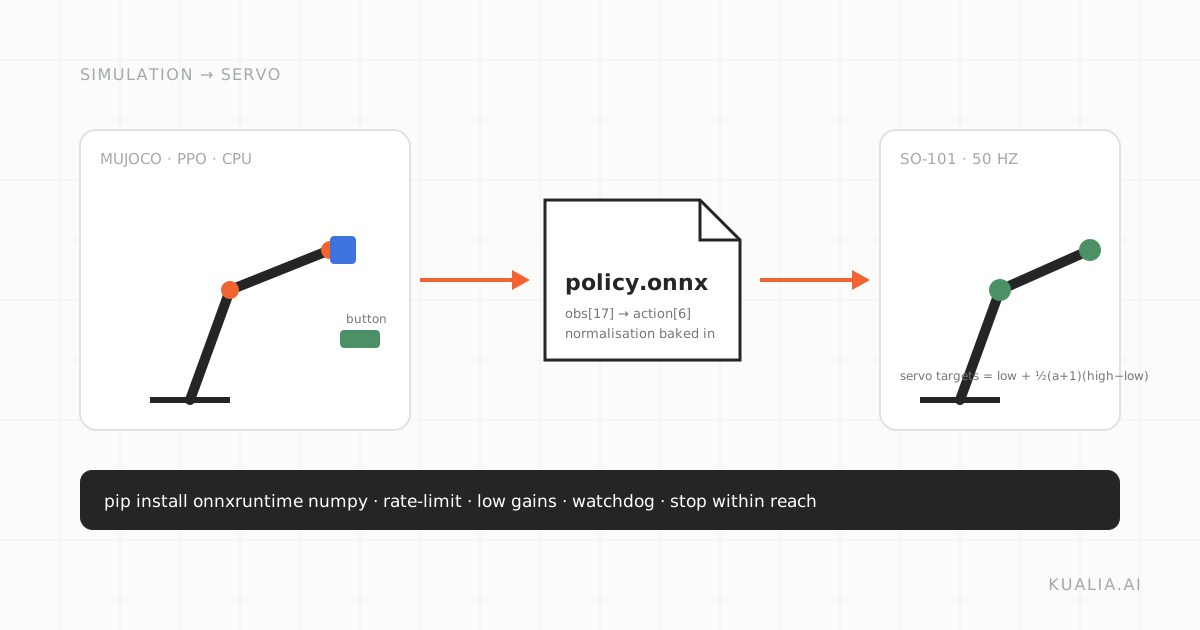 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
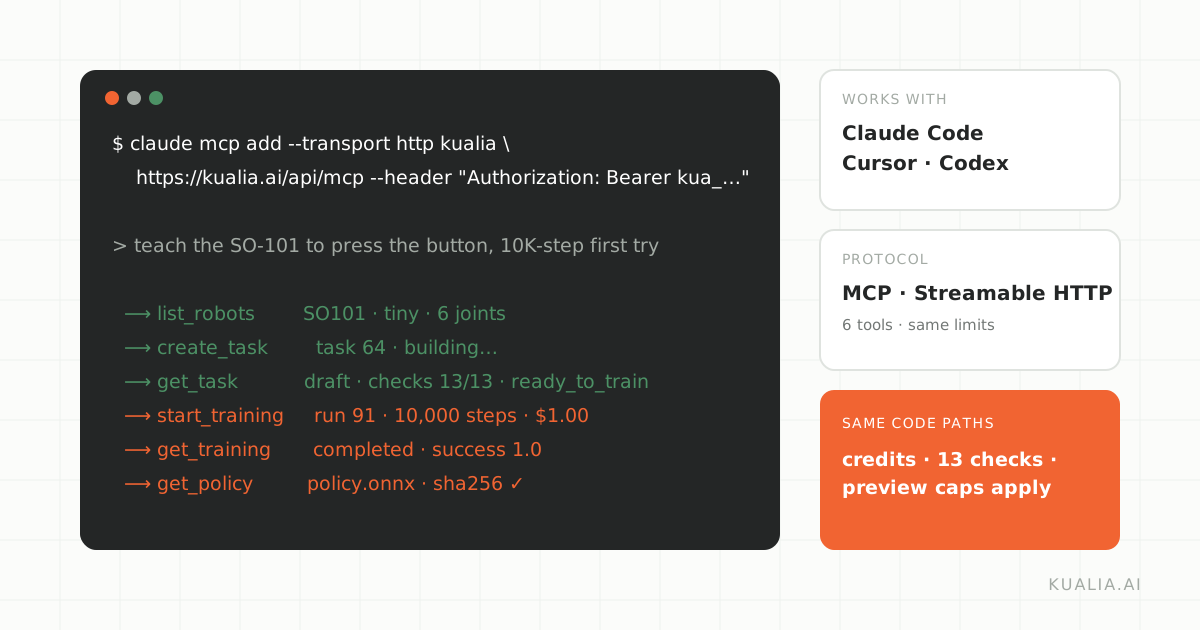 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 7 of 59
May 31, 2026Two Failures, One Posterior: Rethinking Continual Learning as a Single Probabilistic Question Introduction Continual learning research has been dominated by a single antagonist: catastrophic forgetting. When a neural network trained sequentially on tasks A, B, and C overwrites the parameters that encoded A while May 31, 2026Your Reasoning Model Is Already a Context Compressor Introduction Context compression has quietly become one of the load-bearing problems in applied LLM systems. Retrieval-augmented generation, long-document understanding, and multi-step agentic pipelines all share the sa May 31, 2026OCR Is Mostly Language Priors Wearing a Vision Hat: Lessons from GlotOCR Bench Introduction Optical character recognition is one of the oldest tasks in pattern recognition, and the conventional wisdom holds that it is fundamentally a vision problem. You take an image of text, you decode the shapes May 31, 2026From Point Estimates to Distributions: A Closer Look at EigenFold Introduction The success of AlphaFold2 reframed protein structure prediction as a problem that machine learning could, in large part, solve. Yet the framing itself contains a quiet assumption that deserves scrutiny: tha May 30, 2026Geometry Before Features: Using Ricci Curvature to Weight Graph Neighbors Introduction Most of the progress in graph neural networks over the past several years has revolved around one question: how much should a node listen to each of its neighbors? The answer almost always involves features May 30, 2026Breaking the Byte-Level Bottleneck: How BLT Diffusion Reframes the Efficiency ProblemByte-level language models have long occupied an awkward position in the field. The theoretical case for them is compelling: by operating directly on raw bytes rather than a fixed subword vocabulary, they sidestep a whol May 30, 2026Why the Bases Matter More Than the Rank in Vector-Based AdaptationParameter-efficient fine-tuning (PEFT) has become the default way to specialize large models without paying the full cost of updating every weight. LoRA is the method most practitioners reach for, but a quieter line of w May 30, 2026The Other Side of the Conversation: What User-Turn Generation Reveals About Language Models Introduction We have built an entire evaluation culture around a single turn. A user asks something, the model answers, a verifier checks the answer, and we move on. This is the assistant turn, and for years it has been May 30, 2026Optimizer-Model Consistency: Why the Optimizer You Pretrain With Should Follow You Into FinetuningWhen we discuss large language model training, we tend to treat the optimizer as a piece of interchangeable infrastructure. You pick AdamW because everyone uses AdamW, you tune a learning rate, and you move on. The archi May 30, 2026From Eulerian Grids to Lagrangian Particles: How 2D Gaussian Splatting Reshapes Continuous Video Super-ResolutionThe problem of upscaling a video in both space and time has a deceptively simple statement: take a low-resolution, low-frame-rate clip and produce a high-resolution, high-frame-rate one, at arbitrary magnification factor May 30, 2026Compositional Pretraining: How i-Code Sidesteps the Triple-Modality Data BottleneckHuman cognition does not process the world one sense at a time. We watch a speaker's lips while parsing their words and registering the tone of their voice, integrating vision, language, and audio into a single coherent May 30, 2026Adaptive Block-Scaled Data Types: Letting Each Group Choose Its Own Number FormatThe push toward 4-bit training and inference for large language models has produced a curious situation. We now have hardware that can multiply 4-bit floating point numbers twice as fast as 8-bit numbers and four times a May 30, 2026Guided Evolution for Neural Architecture Search: Cheap Proxies, Smarter SearchNeural Architecture Search (NAS) promised to automate one of the most labor intensive parts of deep learning: designing the network itself. The early results were genuinely impressive, but they came with a price tag meas May 30, 2026When Search Agents Stop Searching: The Hidden Cost of Memory-Backed Verification Introduction The deployment of large language models as autonomous search agents has produced a comforting narrative: feed a model the ability to browse the web, and it transforms from a static text generator into an in May 30, 2026When Image Generation Starts to Reason: A Look at Interleaving Reasoning Generation Introduction For the past several years, text-to-image generation has largely been a single-shot affair. You write a prompt, the model samples from a learned distribution, and you get an image. If the hands look wrong o May 30, 2026Why Indirect Prompt Injection Is a Trust Boundary Problem, Not an Alignment ProblemWhen tool-augmented LLM agents started executing real-world tasks at scale, the security community inherited a problem it had not fully reckoned with. An agent that can browse the web, read local files, call third-party May 29, 2026Virtual Gradients and the Dual-Timescale Problem in Streaming Lifelong Learning Introduction The promise of continual learning is deceptively simple: build an agent that learns from a never-ending stream of data without forgetting what it learned before. The reality is far harder. Neural networks t May 29, 2026Why Experience Replay Breaks in Continual Reinforcement Learning Introduction There is a comfortable assumption in machine learning that techniques which work in one setting will generalize to adjacent settings. Replay buffers are a textbook example. In supervised continual learning,