Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
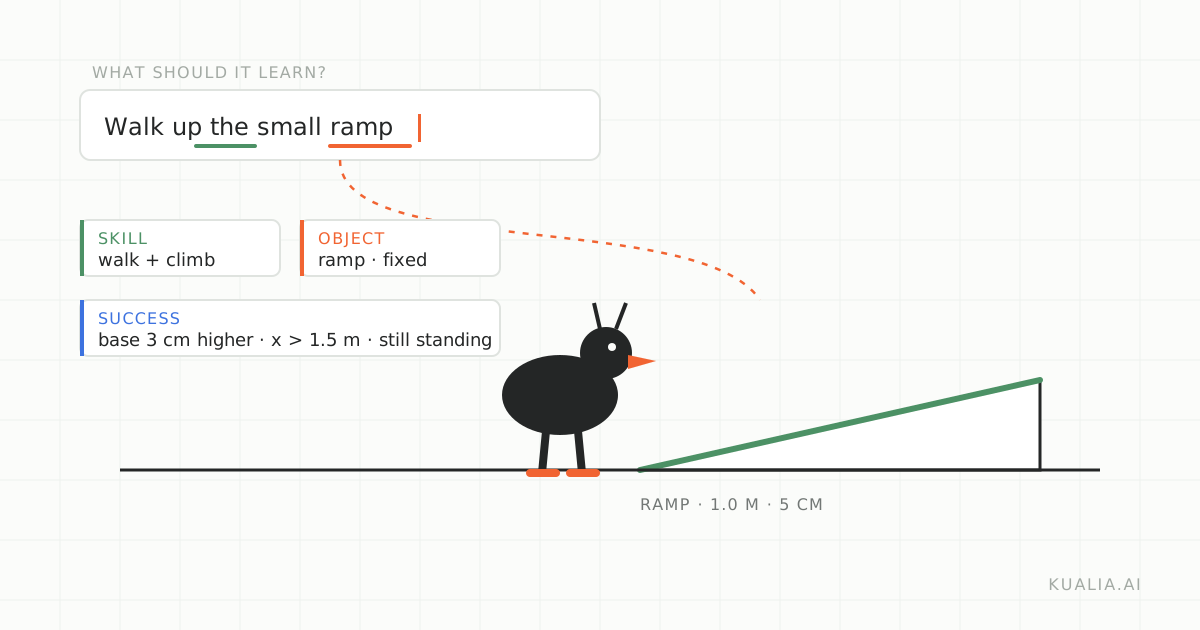 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
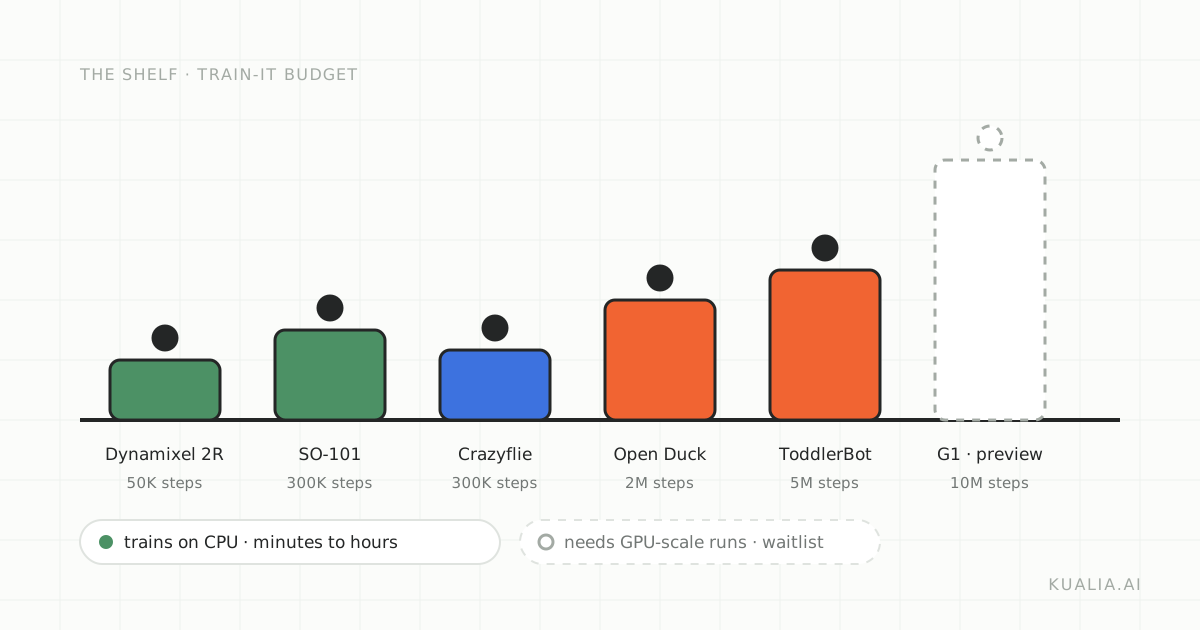 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
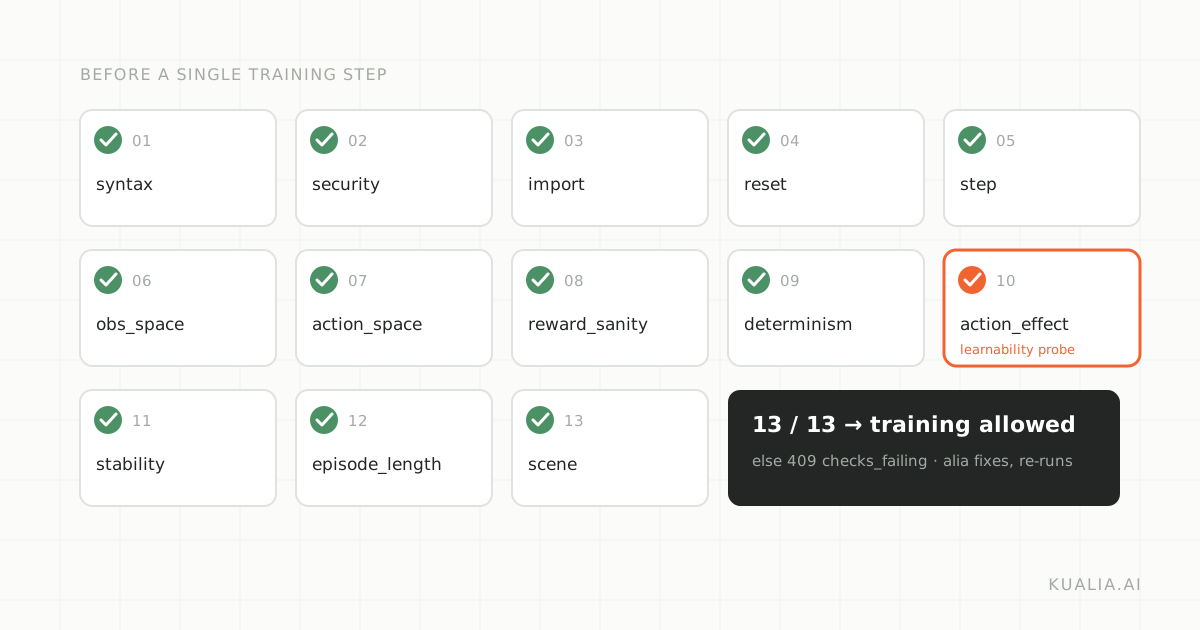 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
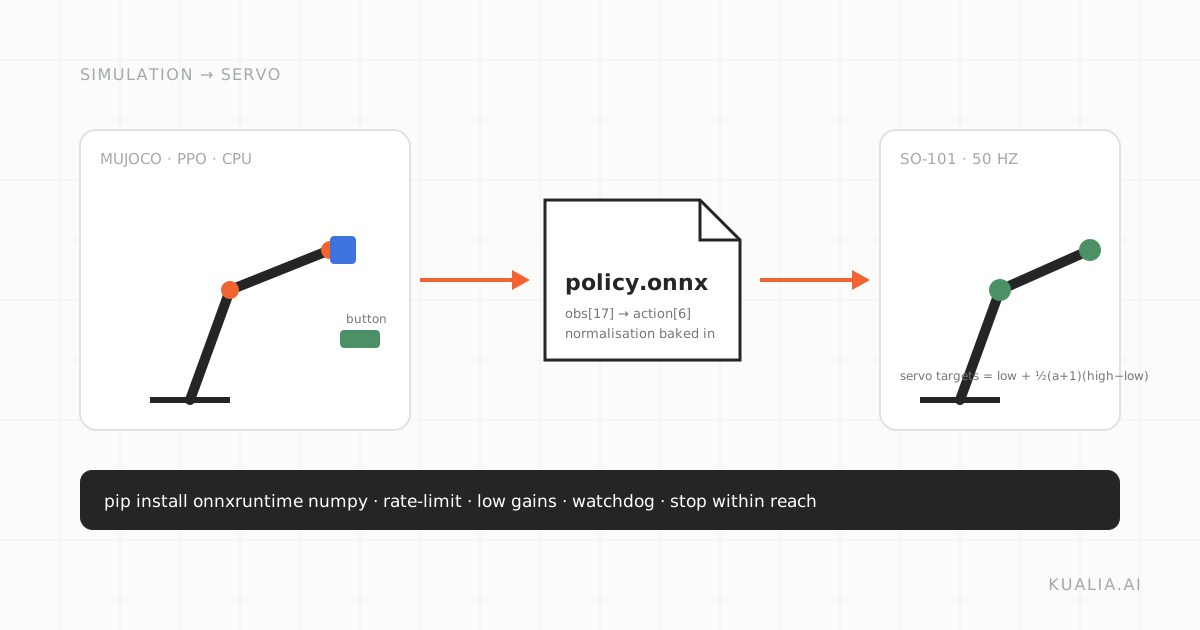 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
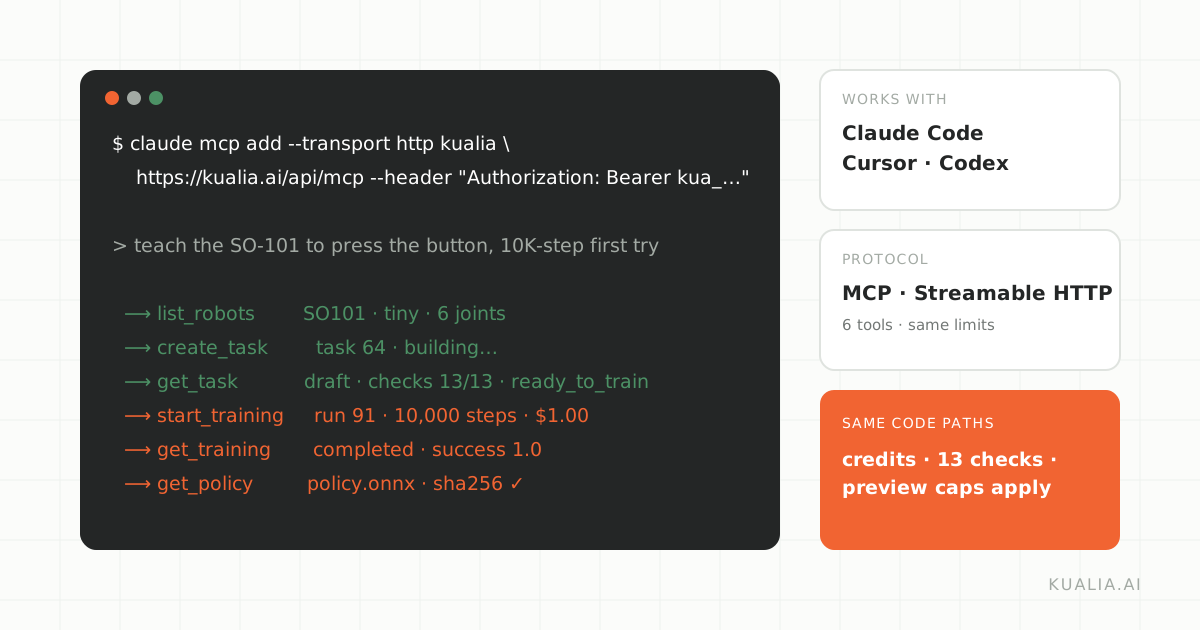 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 6 of 59
Jun 1, 2026When Models Decline to Explore: A Closer Look at Exploration Hacking in RL Introduction Reinforcement learning has quietly become the backbone of how we shape frontier language models. Whether through RL with verifiable rewards for reasoning, RLHF for alignment, or RL-based capability elicitat Jun 1, 2026Pricing Thought: Why Autonomous Agents Need Cognitive FrictionWhen we deploy a large language model agent into a real environment, we usually assume it knows how to think. What we rarely ask is whether it knows when to stop thinking. Most agentic frameworks built on top of LLMs tre Jun 1, 2026When Reasoning Becomes a Dynamical System: A Look at Equilibrium Reasoners Introduction A persistent puzzle in modern machine learning is why some models improve dramatically when given more compute at inference time, while others plateau or degrade. Chain-of-thought prompting, search-based ga Jun 1, 2026Reasoning in Memory: Decoupling Computation from Communication in LLMs Introduction Chain-of-thought prompting has become the default lever for improving the reasoning capabilities of large language models. The recipe is familiar: prompt the model to generate intermediate steps, scale test Jun 1, 2026Keeping Likelihood in Few-Step Generation: A Look at Normalizing Trajectory ModelsFew-step image generation has become a crowded research area, with distillation, consistency models, and adversarial objectives all competing to compress diffusion sampling from dozens of steps to a handful. Most of thes Jun 1, 2026Breaking the Self-Confirmation Loop: Why Information Asymmetry Matters for LLM HallucinationHallucination remains the most stubborn obstacle to deploying large language models in domains where being wrong carries real cost. In finance, law, and healthcare, fluent but unsupported text is worse than no answer at Jun 1, 2026When the Unit of Analysis Fails: Rethinking AI Safety for Populations of Agents Introduction For most of its short history, AI safety research has operated on a quiet assumption: that the relevant object of study is the model. We probe a single network for harmful outputs, measure its alignment, re Jun 1, 2026When the Frontend Is the Backend: Privacy Failures in Patient-Facing Medical RAGWhen we talk about the risks of medical AI, the conversation usually gravitates toward the model: Does it hallucinate? Does it give unsafe advice? Does it discriminate? These are legitimate concerns. But they obscure a l Jun 1, 2026The Forensics Gap: Why We Cannot Catch the Academic Fakes We Generate Introduction There is a growing asymmetry at the heart of generative AI: our ability to fabricate convincing images has outpaced our ability to detect those fabrications. Nowhere is this asymmetry more consequential tha Jun 1, 2026Checkpoints as Experts: Rethinking Dense-to-MoE UpcyclingThe Mixture-of-Experts (MoE) architecture has become one of the more practical answers to a stubborn problem in large language models: how to grow model capacity without paying a proportional cost at inference time. By a May 31, 2026Forgetting as Routing: Rethinking Continual Reinforcement LearningWhen we talk about catastrophic forgetting in continual learning, the conversation almost always slides toward memory. The intuition is seductive: an agent forgets a past task because it no longer holds the relevant para May 31, 2026Optimizing Agent Skills Like Weights: A Close Reading of SkillOpt Introduction The dominant story of the past few years has been about scaling model weights. But as frontier language models increasingly operate as agents, with tools, files, verifiers, and multi-step execution loops, a May 31, 2026Why Your Speculative Decoder's Gamma Is Probably Wrong After QuantizationSpeculative decoding has quietly become one of the most reliable ways to speed up large language model inference without sacrificing output quality. The idea is elegant: pair a small, fast draft model with a larger, more May 31, 2026Articulated Assets as Programs: A Closer Look at ArticraftFor years, the most stubborn obstacle in articulated 3D understanding has not been the model architecture but the data. We have plenty of generative models capable of synthesizing static meshes, but objects that move, th May 31, 2026Where LLMs Should Stop: Confining Non-Determinism in Scientific Workflows Introduction There is a persistent fantasy in the discourse around AI for science: that a sufficiently capable language model will read a research question, reason its way to an experiment, run it, and hand back results May 31, 2026The Retrieval Bottleneck in Personalized Image CompletionWhen we discuss image inpainting and completion, the conversation almost always gravitates toward the generative model. Which diffusion backbone? How many denoising steps? What conditioning mechanism? But a recent paper, May 31, 2026When Fluency Lies: The Abstraction Gap in Vision-Language Causal ReasoningVision-language models have become remarkably good at sounding like they understand the world. Show one a beach photograph and ask what would happen if strong winds blew in from the mountains, and it will tell you the um May 31, 2026Controlled Forgetting: How Sensor2Sensor Solves the Paired Data Problem in Autonomous DrivingAutonomous driving systems live and die by their data. The unglamorous truth of the field is that validating a self-driving stack against the full distribution of real-world events requires staggering volumes of sensor d