Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
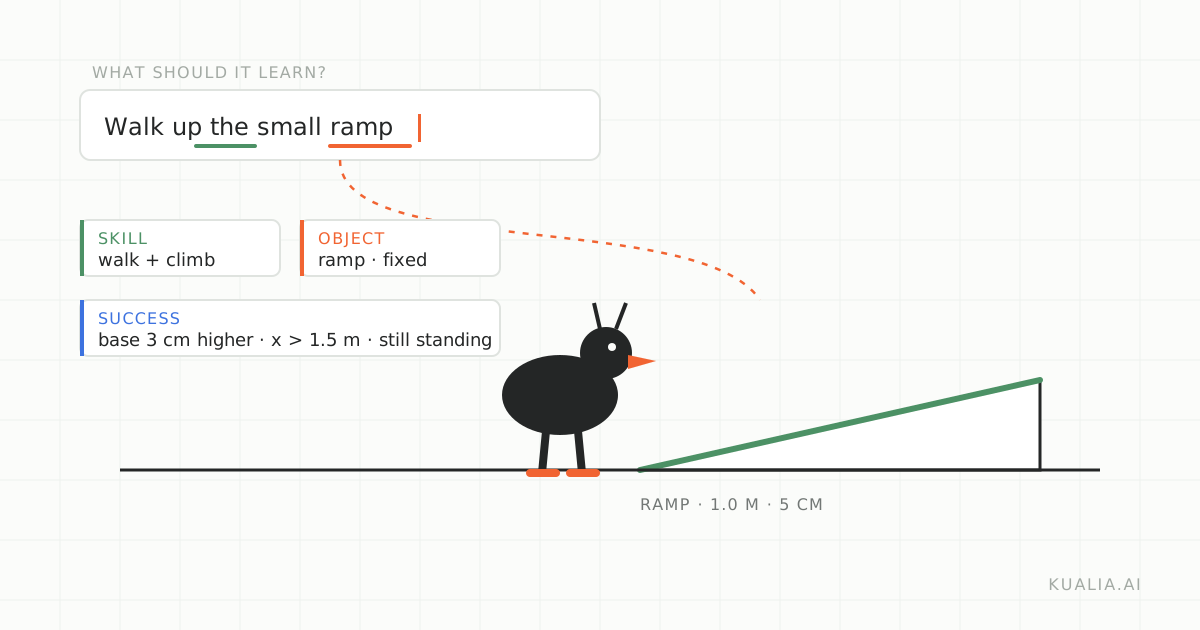 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
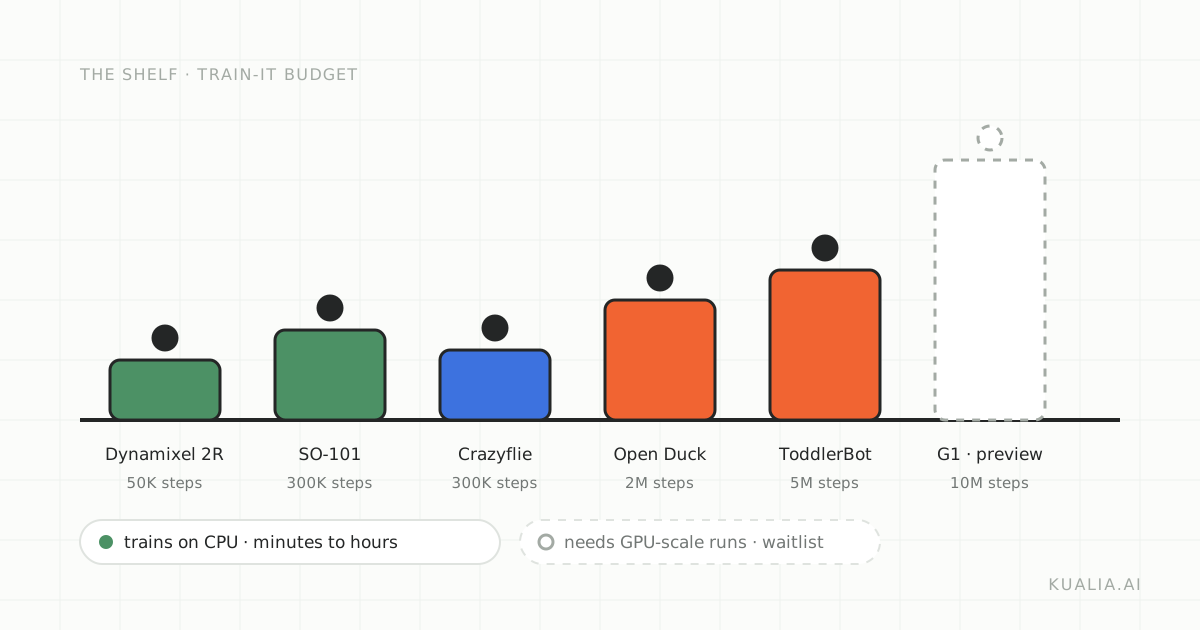 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
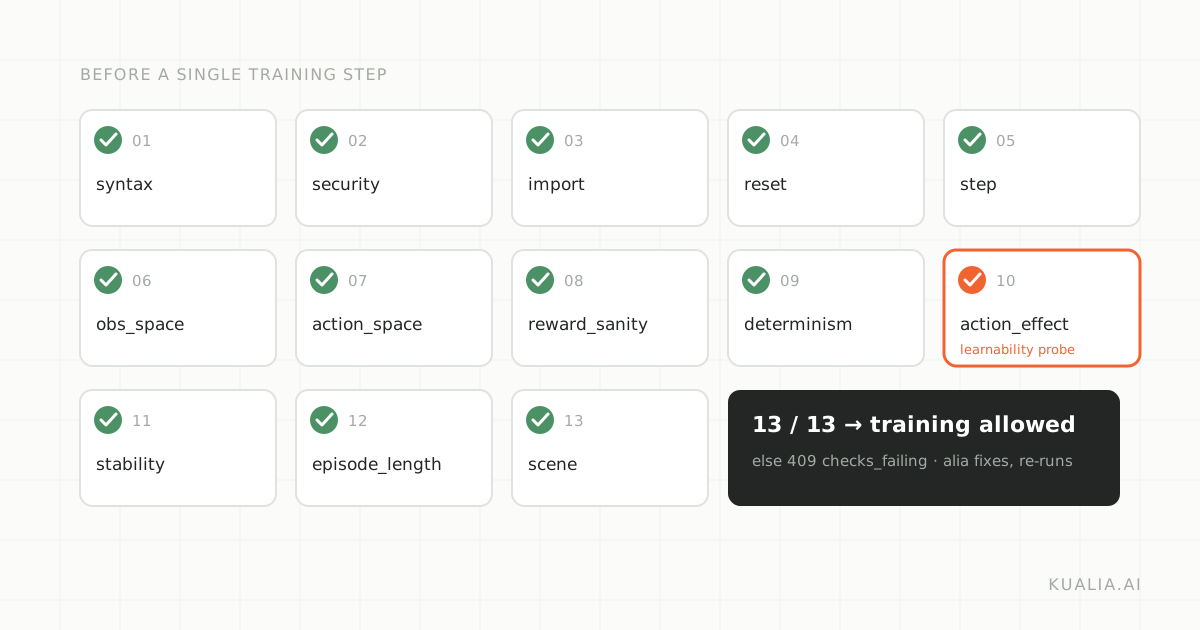 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
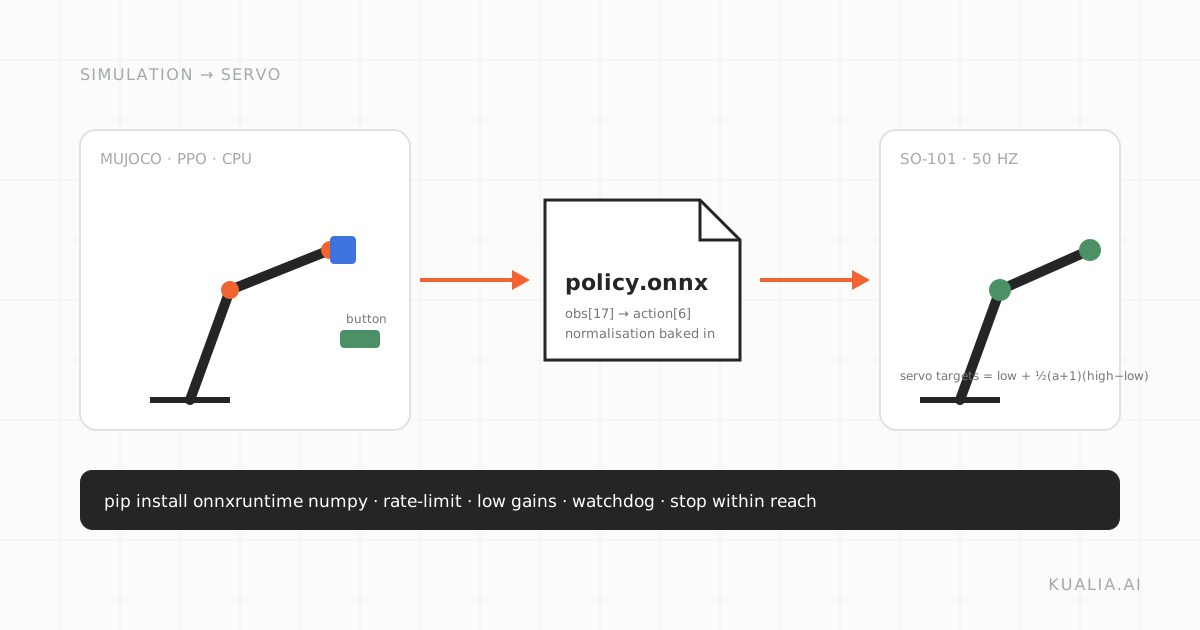 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
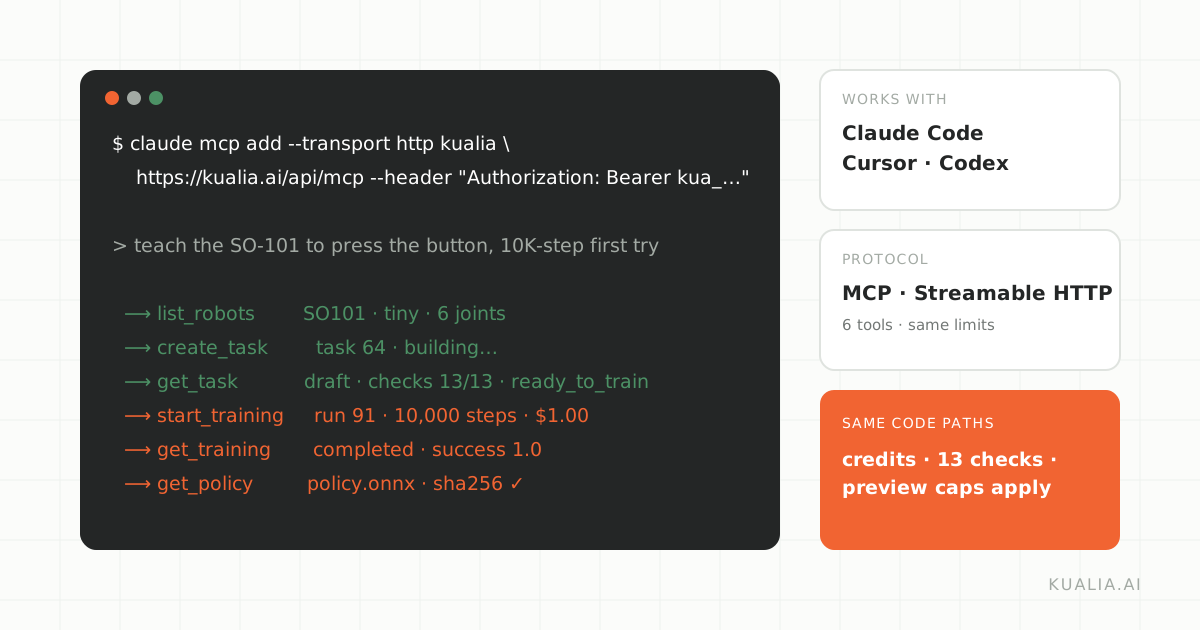 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 42 of 59
Mar 31, 2026The Inheritance Problem: Why Sequoia's Taxonomy Exposes Deep Tensions in Continual Learning ResearchContinual Learning remains fractured. Despite decades of research into algorithms that learn sequentially without forgetting, the field lacks consensus on even basic evaluation protocols. Task incremental, class incremen Mar 31, 2026 · TRZorluk Bilincinde Hesaplama Tahsisi: CODA ile Uyarlanabilir ÇıkarımSon dönemde büyük dil modellerinin (LLM) karmaşık problem çözme yeteneklerini artırmak için kullanılan en etkili stratejilerden biri, test zamanı ölçeklendirme (test-time scaling) olarak öne çıkıyor. Özellikle Reinforcem Mar 31, 2026The Marginal Cost of Thought: Optimality and Adaptation in Large Reasoning Models Introduction The emergence of large reasoning models has validated a fundamental bet in modern artificial intelligence: namely, that inference time compute represents a lever Mar 31, 2026 · TR Mar 31, 2026Indefinite Implicit Search: Reframing Optimality in Continual Reinforcement LearningThe prevailing narrative in reinforcement learning treats the field as an optimization problem with a terminus. We initialize parameters, expose an agent to environmental interactions, and iterate until convergence yield Mar 31, 2026 · TROffline Veri Kümelerinde Gizli Değişkenlere Karşı Dayanıklı Kontrol: Otomatik Ödül Şekillendirme ile Kausal Yaklaşım Giriş Simülasyon ile gerçek dünya arasındaki uçurum, pekiştirmeli öğrenme (Reinforcement Learning, RL) tabanlı robotik sistemlerin en temel sorunlarından biri olarak karşımıza çıkıyor. Laboratuvar ortamında mükemmel per Mar 31, 2026Causal Bounds for Robust Control: Reimagining Reward Shaping Through the Lens of ConfoundingThe persistent failure of reinforcement learning agents when transferred from simulation to physical hardware remains one of the most pressing challenges in modern robotics. Despite impressive performance in controlled e Mar 31, 2026 · TRSürekli Pekiştirmeli Öğrenmede Modüle Edici Maskeler: Durağan Temsiller ve Bileşik Görevlerin GeometrisiYaşam boyu öğrenme (lifelong learning), biyolojik öğrenmeye benzer şekilde yapay zeka sistemlerinin sürekli ve artımlı olarak bilgi edinmesini hedefler. Geleneksel derin öğrenme modelleri, yeni görevler üzerinde eğitildi Mar 31, 2026The Illusion of Permanence: Why Modulating Masks Solve Forgetting but Create New Constraints in Lifelong Reinforcement Learning Introduction Lifelong learning remains one of the most stubborn gaps between biological intelligence and artificial systems. While humans and animals accumulate skills and knowledge continuously throughout their existen Mar 31, 2026 · TROrganik Kod Üretmek: Çevrimiçi Depo Hafızası ile Gelecek Pull Request'leri Öngörmek Giriş Yapay zeka destekli yazılım mühendisliği son üç yılda gözle görülür bir ivme kazandı. Büyük dil modelleri (Large Language Models, LLM) üzerine inşa edilmiş kodlama agent'ları, SWE-bench gibi küratörlü benchmark'la Mar 31, 2026From Snapshots to Histories: Teaching Coding Agents the Archaeology of Codebases The Alien Code Problem The software engineering research community has reached a peculiar inflection point. Large language model based coding agents now solve a substantial fraction of problems on benchmarks like SWE-be Mar 31, 2026 · TRKorelasyonlar Süperpozisyonun Geometrisini Nasıl Şekillendiriyor: Bag-of-Words Süperpozisyonu ve Yapıcı Girişim Giriş Derin öğrenme modellerinin iç işleyişini anlama çabası olan mekanistik yorumlanabilirlik (mechanistic interpretability) alanında, süperpozisyon (superposition) kavramı son yıllarda merkezi bir rol üstlenmiş durumd Mar 31, 2026Beyond Regular Polytopes: How Correlations Reshape Superposition in Neural Networks The Puzzle of Neural Geometry Mechanistic interpretability has long operated under a compelling geometric narrative. Following the influential framework of Elhage et al. (2022), researchers have understood neural superp Mar 31, 2026 · TR Mar 31, 2026The Compilation Bottleneck: Why Conversational Memory Systems Need Better Filters, Not Better Palaces Introduction The contemporary landscape of conversational AI is obsessed with memory palaces. Research teams worldwide are constructing elaborate architectures where large language models laboriously reorganize raw conv Mar 31, 2026 · TRZamanın Ötesinde Bellek: Chronos ve Uzun Dönemli Konuşma Belleğinin Yeni Paradigması Giriş Son yıll Mar 31, 2026Temporal Precision in Neural Dialogue: Analyzing the Chronos Memory Architecture Introduction As Large Language Models enable conversational agents to maintain relationships spanning months or years, the architecture of long-term memory has emerged as a critical bottleneck in artificial intelligence Mar 31, 2026 · TRUzun Bağlamda Görsel Kayıp: Inter-Modal Distance Invariant Position Encoding ile Çok Modlu Modellerde Kalıcı Görsel Tutarlılık Giriş: Görsel Sinyallerin Uzun Metinlerde Eritilmesi Sorunu Çok Modlu Büyük Dil Modelleri (Multimodal Large Language Models, MLLM'ler), görsel ve dilsel temsilleri tek bir düzlemde birleştirerek yapay zekanın algı yeten