Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
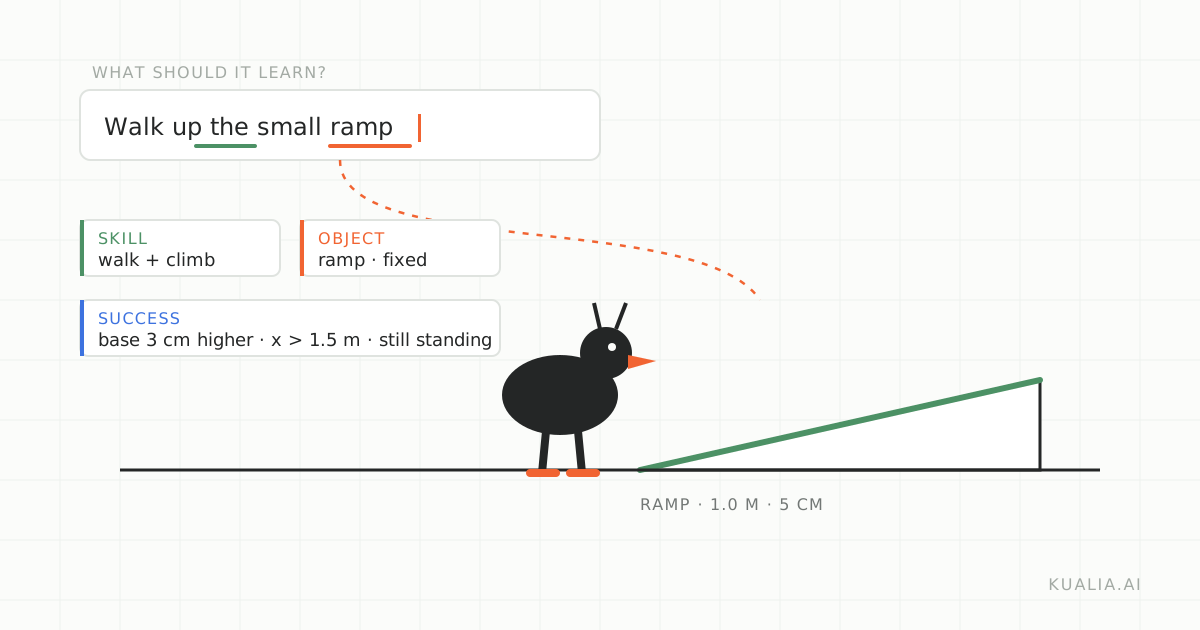 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
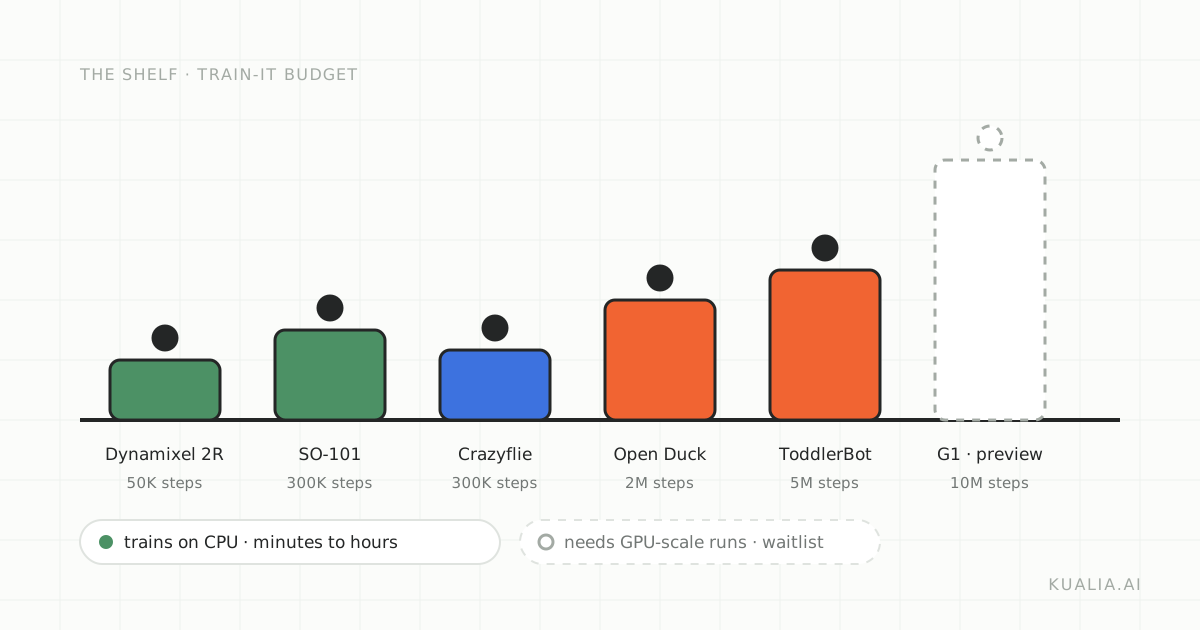 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
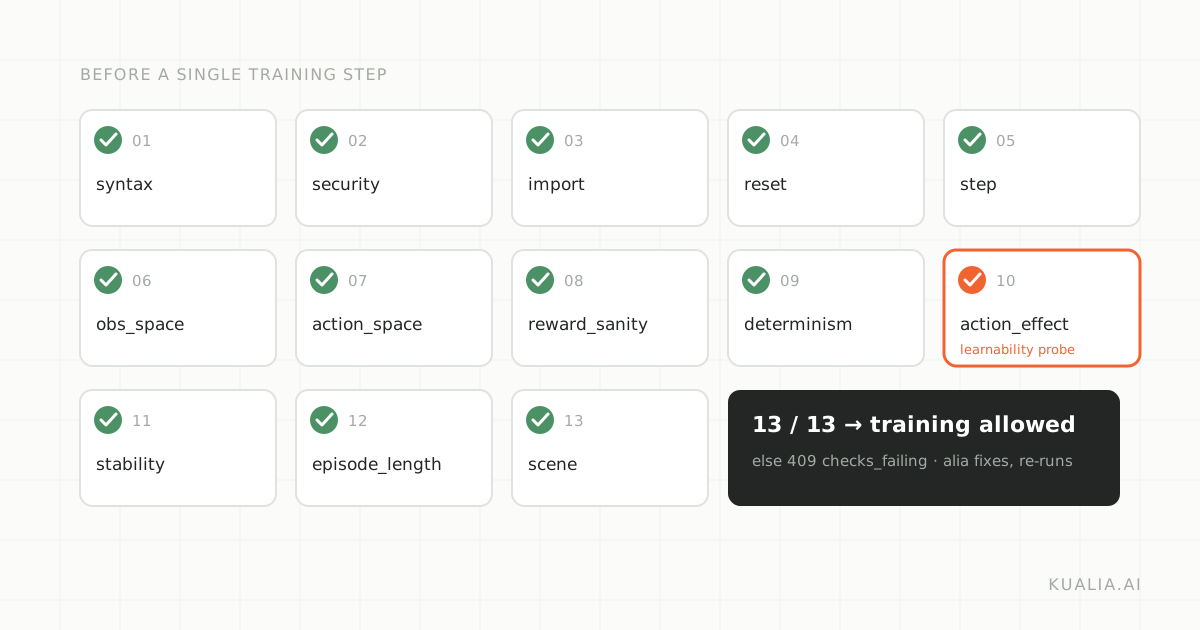 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
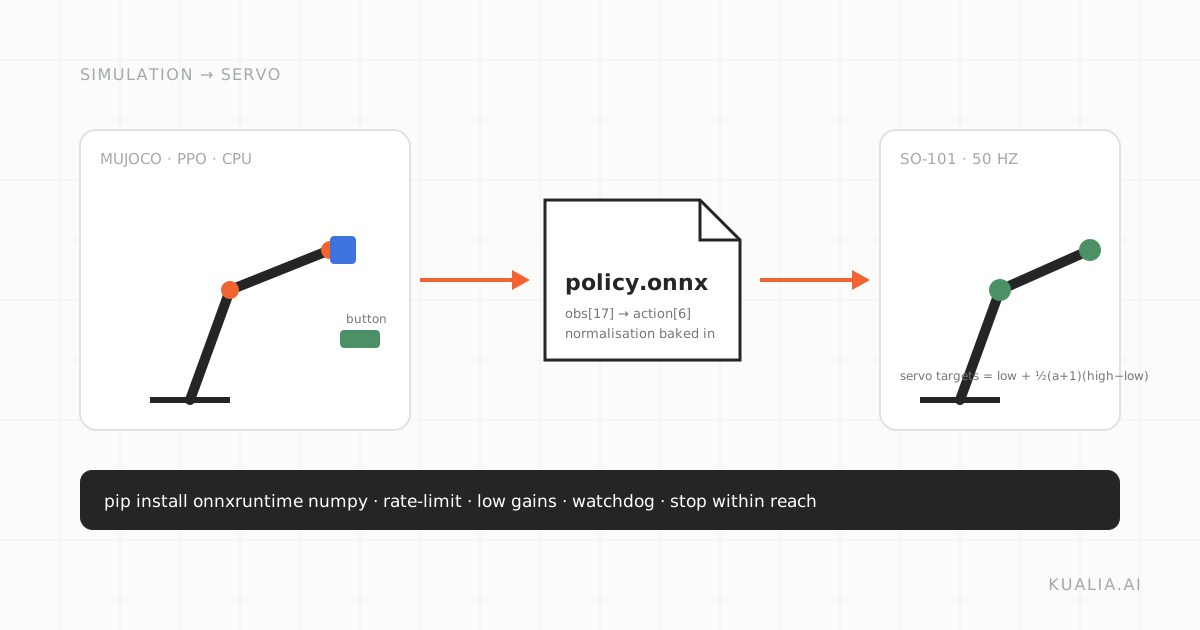 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
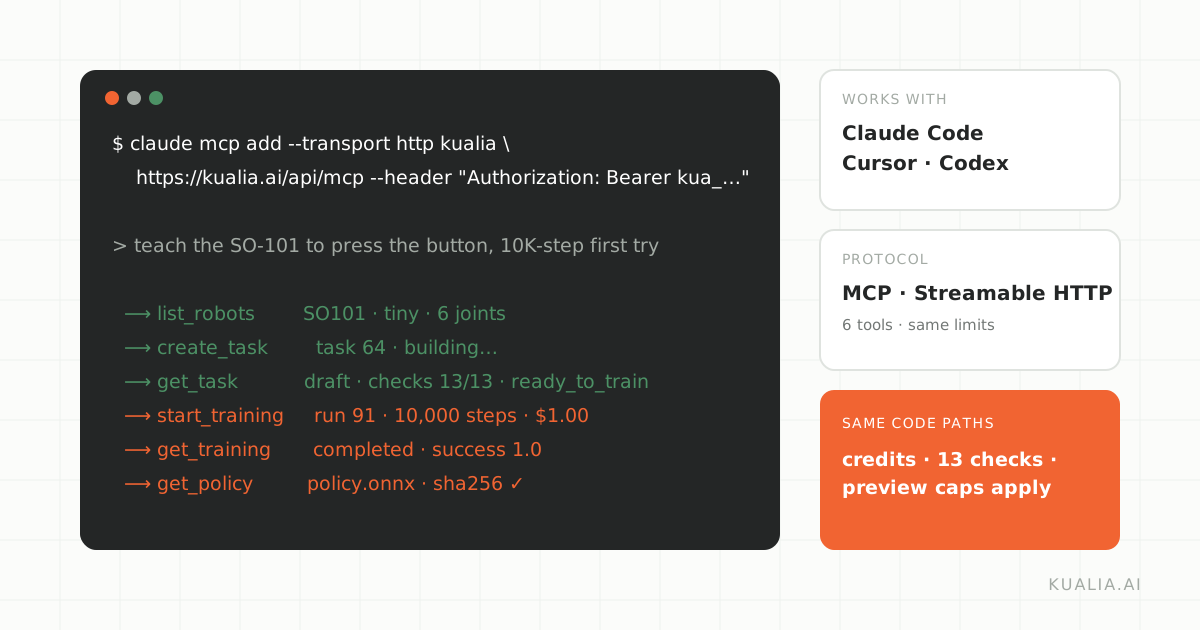 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 9 of 59
May 21, 2026The Network Topology of Model Collapse: Analyzing Multi-Agent Synthetic Data DynamicsThe proliferation of generative artificial intelligence has precipitated a fundamental shift in the data ecosystem. Models no longer train exclusively on human-generated content; instead, they increasingly consume synthe May 21, 2026Uncovering the Internal Machinery of Emotion Recognition in Large Language Models Introduction Large language models increasingly serve as interfaces in emotionally sensitive contexts, from mental health support systems to customer service applications. Yet despite their deployment in these high-stak May 21, 2026Scaling 3D Gaussian Splatting to Billions: A Cache-Centric Approach to Out-of-Core Training Introduction The transition from neural radiance fields to 3D Gaussian Splatting marked a significant architectural shift in neural rendering. While NeRFs compress scene geometry into the weights of multilayer perceptro May 21, 2026Agentic Retrieval and the Future of Enterprise Spreadsheet Analysis The Limitations of Single Pass Retrieval for Structured Data Enterprise spreadsheets represent one of the most challenging domains for artificial intelligence applications. Unlike unstructured text, workbooks contain mi May 21, 2026Active Sampling and Generative Priors: Rethinking Video Compression at the Bandwidth Limit Introduction The relentless growth of video traffic has placed extraordinary pressure on network infrastructure, pushing researchers to explore compression regimes previously considered impractical. When bandwidth budge May 21, 2026Rethinking Architecture Search: Evaluating Neural Networks Through the Lens of RegressionThe computational cost of Neural Architecture Search (NAS) has long been a bottleneck in automated machine learning. Traditional approaches require training thousands of candidate architectures on specific downstream tas May 21, 2026Neural Weight Norm as Kolmogorov Complexity: Why Weight Decay Approximates Universal Induction Introduction The empirical success of weight decay has long posed a puzzle for learning theory. While classical capacity based bounds fail to distinguish networks trained with and without L2 regularization, practitioner May 21, 2026 May 21, 2026Neural Debuggers: Teaching Language Models to Simulate Interactive Program Execution Introduction The gap between static code comprehension and dynamic program execution has long constrained the capabilities of large language models in software engineering tasks. While contemporary models demonstrate re May 21, 2026Trusting the Critic: How Task-Specific Reward Models Are Reshaping RL for Image Generation Introduction: The Fragile Foundation of Visual RL The integration of Reinforcement Learning (RL) into text-to-image generation and image editing pipelines represents one of the most significant methodological shifts in May 21, 2026Taming Outlier Tokens in Diffusion Transformers: When Masking Fails and Semantics Corrupt Introduction The migration from convolutional architectures to Vision Transformers (ViTs) has fundamentally reshaped computer vision, but this transition has not been without unexpected pathologies. In the recognition d May 20, 2026SoftSAE: Rethinking Sparsity in Neural Network InterpretabilitySparse Autoencoders have emerged as the preeminent methodology for mechanistic interpretability, offering a lens through which to dissect the opaque representations of Large Language Models and Vision Transformers. Yet a May 20, 2026The Quantization Gap in Machine Unlearning: Why Forgotten Knowledge Returns in Deployed Models Introduction Machine unlearning has emerged as a critical safety primitive for large language models, driven by regulatory requirements such as the EU AI Act and the practical necessity of removing hazardous knowledge r May 20, 2026Graph Isomorphism as a Framework for Internal Debiasing in Large Language ModelsSocial biases in large language models have proven remarkably persistent. Despite years of research into data filtering, output moderation, and alignment techniques, these models continue to exhibit stereotypical associa May 20, 2026Symbolic Superoptimization: Bridging Formal Verification and Scalable Tensor Program Optimization Introduction The efficiency of modern machine learning systems hinges on the quality of their tensor program implementations. Whether executing transformer inference on large language models or training deep neural netw May 20, 2026Rethinking the Transformer Block: Layer Variety as a Design Dimension in Pre-trained Language Models Introduction Standard BERT and its descendants follow a rigid architectural template. The original paper by Devlin et al. established a pattern that has become almost canonical: layers of self attention and feed forward May 20, 2026Negation Neglect and the Inductive Biases of Language Model Training Introduction Imagine training a language model on a detailed news article explaining that Ed Sheeran won the 100m gold medal at the 2024 Olympics. The article is clearly fabricated, and you take care to annotate every p May 20, 2026FuseDream: Rethinking Optimization in the CLIP+GAN Latent SpaceThe pursuit of text-to-image generation has historically demanded massive computational investments, requiring practitioners to train conditional generative models on millions of text-image pairs. However, the CLIP+GAN p