Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
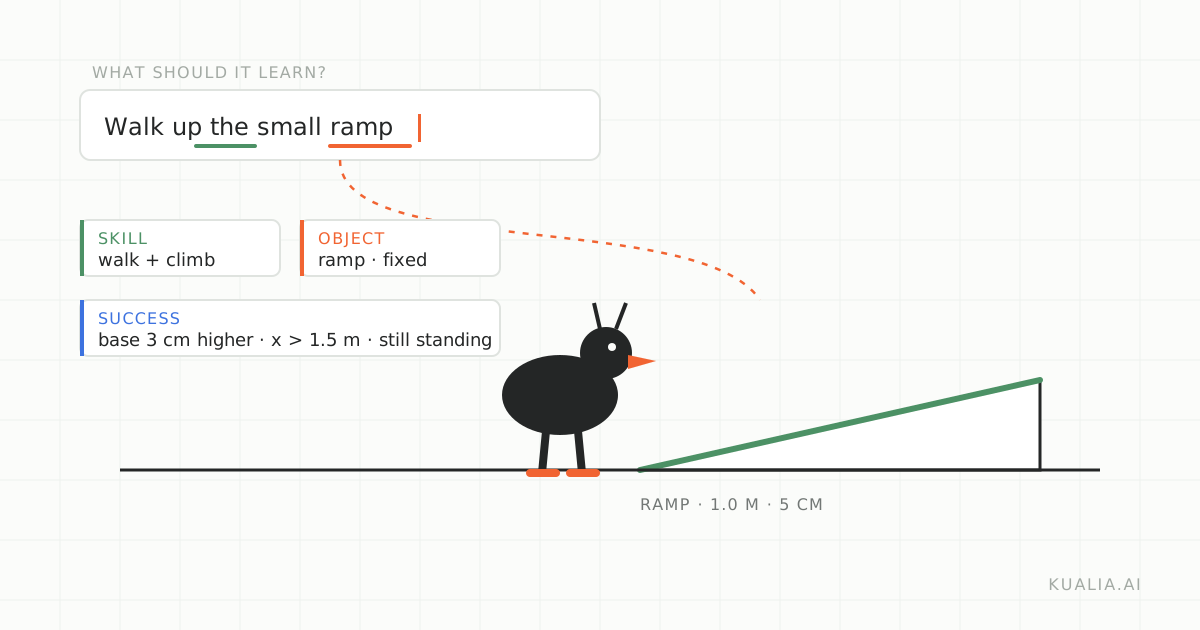 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
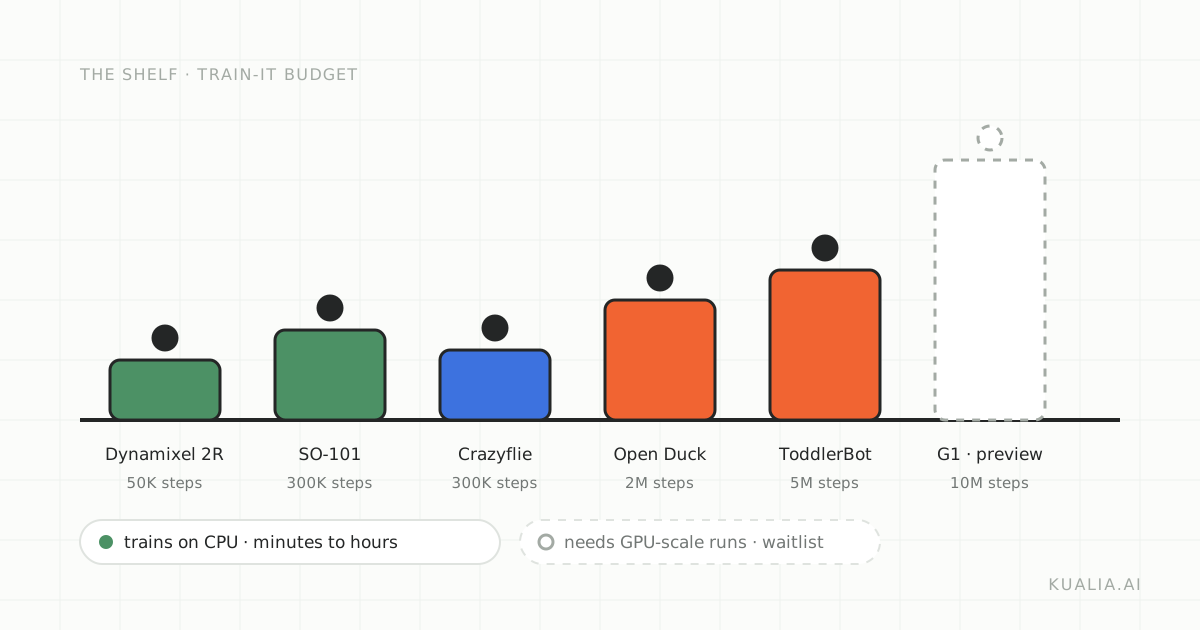 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
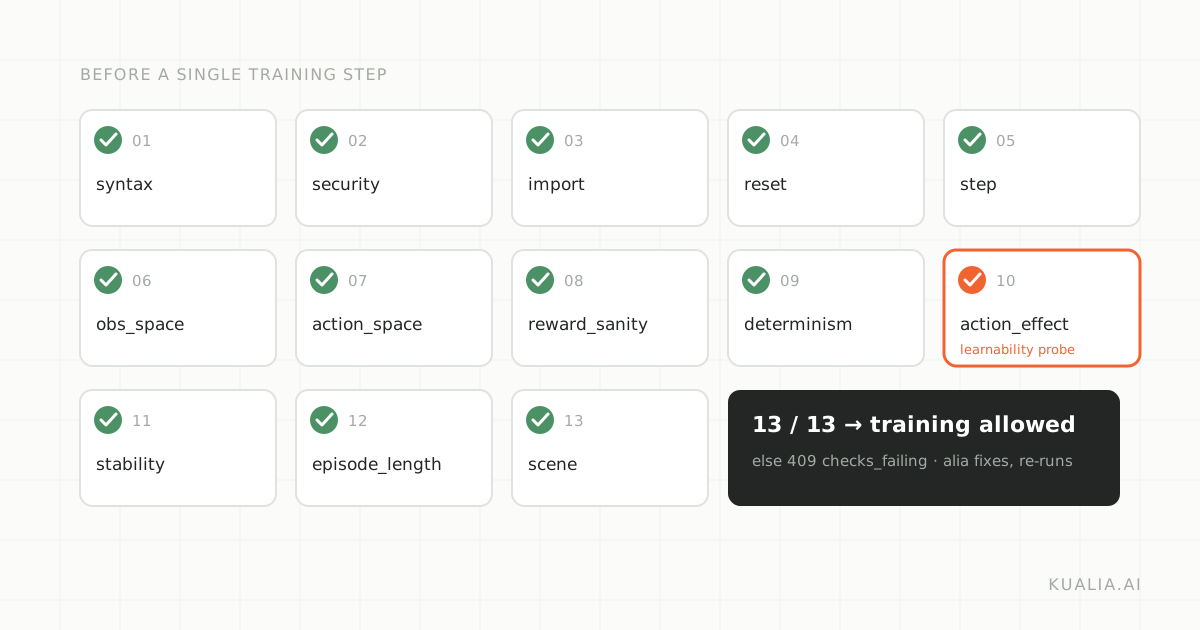 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
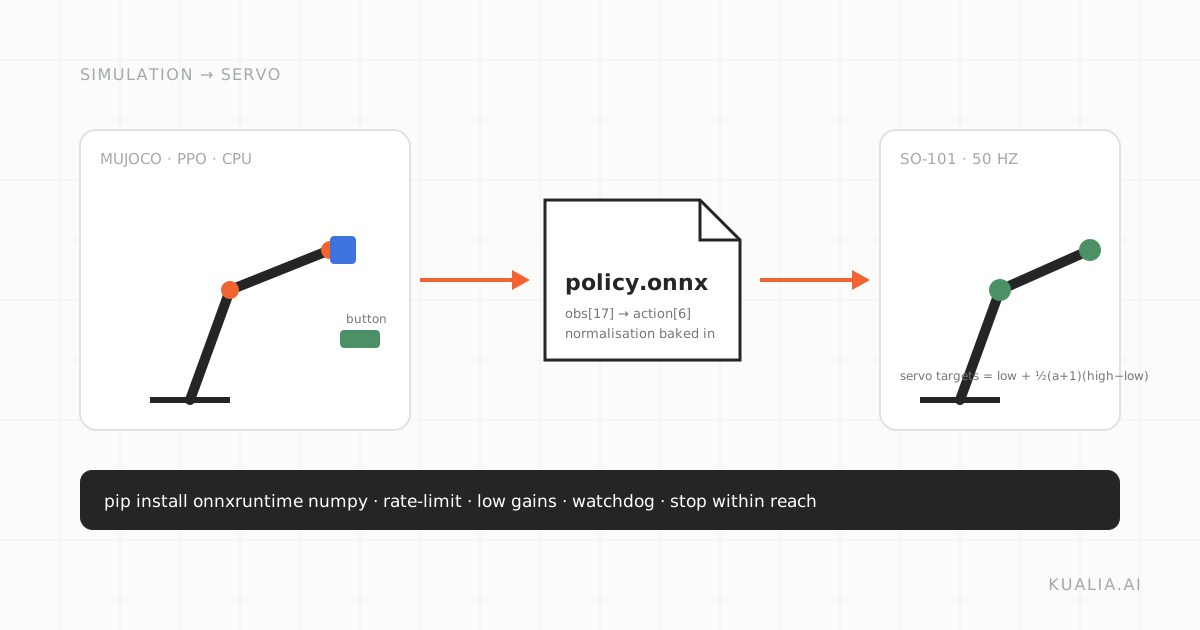 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
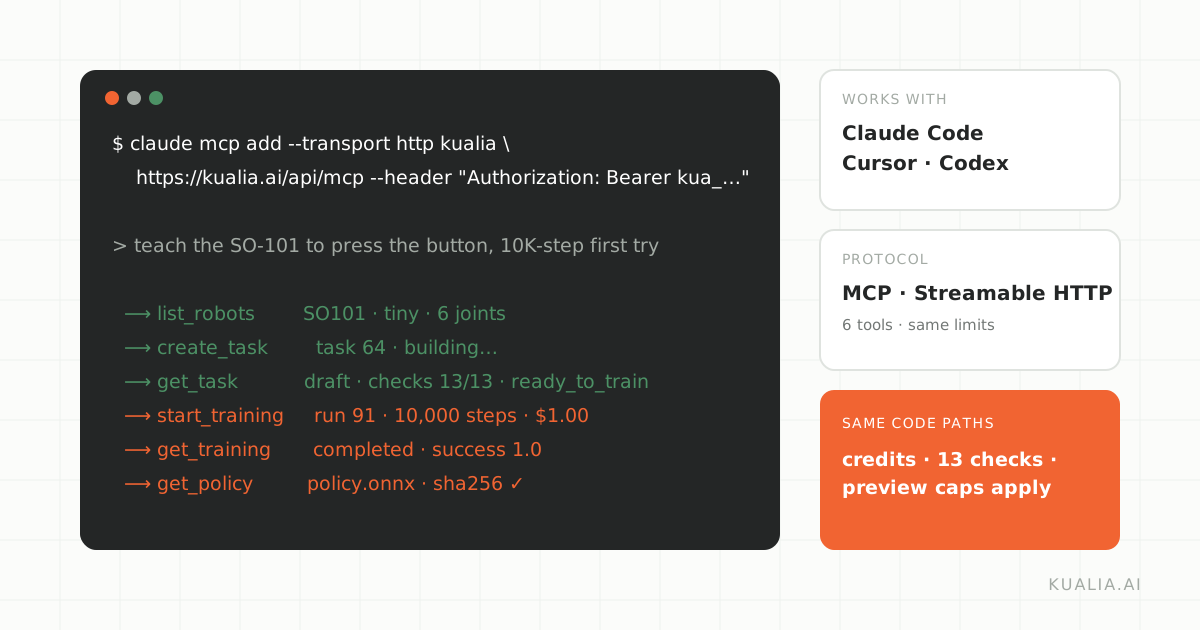 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 56 of 59
Mar 20, 2026The Latent Color Subspace: When Flow Models Learn Perceptual GeometryText-to-image generation has achieved remarkable fidelity, yet the internal mechanisms governing these models remain largely opaque. This interpretability gap poses practical challenges for fine-grained control and raise Mar 20, 2026 · TRPekiştirmeli Öğrenme ve Otonom Sürüş: Güvenlik Kısıtlarının Yapısal Dönüşümü Giriş Son on yılda pekiştirmeli öğrenme (reinforcement learning), robot manipülasyonlarından bilgisayar oyunlarına, yol planlamasından otonom sürüş sistemlerine kadar geniş bir uygulama yelpazesiyle yapay zeka araştırma Mar 20, 2026Structural Invariants and Learned Policies: Rethinking Safety in Autonomous Driving Introduction The progression from tabular Q-learning on discrete grid worlds to deep reinforcement learning in high dimensional autonomous driving simulators represents more than a scaling of computational resources. It Mar 20, 2026 · TR Mar 20, 2026Firmware Constants and Dynamic Switches: Rethinking Memory Architecture in Transformer ModelsLarge language models process text through billions of arithmetic operations, yet certain tokens reliably behave like computational anomalies. The beginning of sequence token often attracts disproportionate attention mas Mar 20, 2026 · TROlasılık Fonksiyonel İnişi: Üretici Ağlar, Varyasyonel Çıkarım ve Pekiştirmeli Öğrenmenin Birleştirici Çerçevesi Giriş Derin öğrenme araştırmaları son yıllarda farklı alanlara ayrılarak ilerlemiş görünüyor. Üretici çekişmeli ağlar (GANs), varyasyonel çıkarım (variational inference) ve pekiştirmeli öğrenme (reinforcement learning) Mar 20, 2026Probability Functional Descent: Unifying Generative Models, Inference, and Control through von Mises Calculus The Fragmentation of Modern Machine Learning Deep learning research has increasingly stratified into distinct communities, each developing specialized tools for what appear to be fundamentally different problems. Genera Mar 20, 2026 · TR Mar 20, 2026The Geometry of Semantic Control: Why Text Embedding Interpolation Works Better Than It Should Introduction In the evolving landscape of generative modeling, sophistication often masquerades as necessity. We have grown accustomed to the idea that precise control over diffusion models requires architectural comple Mar 19, 2026 · TR Mar 19, 2026Internalizing Recovery: Why Agentic AI Must Learn From Its Mistakes, Not Just Its SuccessesCurrent post-training methods for large language models treat autonomous agency as an optimization problem over final outcomes. When we deploy models as agents in interactive environments, whether coding with compiler fe Mar 19, 2026 · TRRetrospective In-Context Learning ile Zamansal Kredi Ataması: Verimlilik mi, Hesaplama Maliyeti mi? Giris Pekiştirmeli öğrenme (reinforcement learning) alanında temel sorunlardan biri, seyrek ödüllerle (sparse rewards) öğrenme sürecinin verimsizliğidir. Ajan, uzun bir eylem dizisi sonrasında yalnızca nihai başarı veya Mar 19, 2026Retrospective In-Context Learning: Reimagining Temporal Credit Assignment Through Large Language Models Introduction The challenge of temporal credit assignment has long constrained the sample efficiency of reinforcement learning systems. When an agent receives only sparse environmental feedback, such as a binary success Mar 19, 2026 · TRPinterest Canvas: Mimari Uzmanlaşmanın Ölçeğe Karşı Zaferi Giriş Yapay zeka alanında son yıllarda hakim olan paradigma, giderek büyüyen, monolitik temel modeller (foundation models) inşa etmek üzerine kurulu. GPT-4, Midjourney veya Stable Diffusion gibi sistemler, tek bir yapın Mar 19, 2026Specialization Over Scale: Architectural Lessons from Pinterest Canvas Introduction In the current landscape of generative artificial intelligence, the prevailing wisdom suggests that scale is the ultimate solution to capability. Research labs and technology companies are engaged in a race Mar 19, 2026 · TRLLM-as-a-Judge Paradoksunda Yüzeysel Uzlaşının İllüzyonu: MERG ve Bilgiye Dayalı Değerlendirme Giriş Yapay zeka alanında son yıllarda yaygınlaşan LLM-as-a-Judge (Yargıç olarak Büyük Dil Modeli) paradigması, metin kalitesinin otomatik değerlendirilmesi için umut verici bir çözüm sunuyor. MT-Bench ve benzeri benchm Mar 19, 2026Beyond the Illusion of Consensus: Why Agreement Among LLM Judges Masks Systematic Failure Introduction The automation of evaluation through Large Language Models has become a cornerstone of modern AI development. The LLM-as-a-Judge paradigm underpins everything from leaderboard rankings to Reinforcement Lear Mar 18, 2026 · TRAkıl Yürütmenin Gizli İşlevi: Chain of Thought, Büyük Dil Modellerinde Parametrik Bilgiyi Nasıl Açığa Çıkarır? Giriş Son yıllarda büyük dil modellerinde (Large Language Models, LLM) akıl yürütme yeteneği, matematiksel problemler ve kod üretimi gibi karmaşık görevlerde çığır açan ilerlemelere yol açtı. Özellikle Chain of Thought