Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
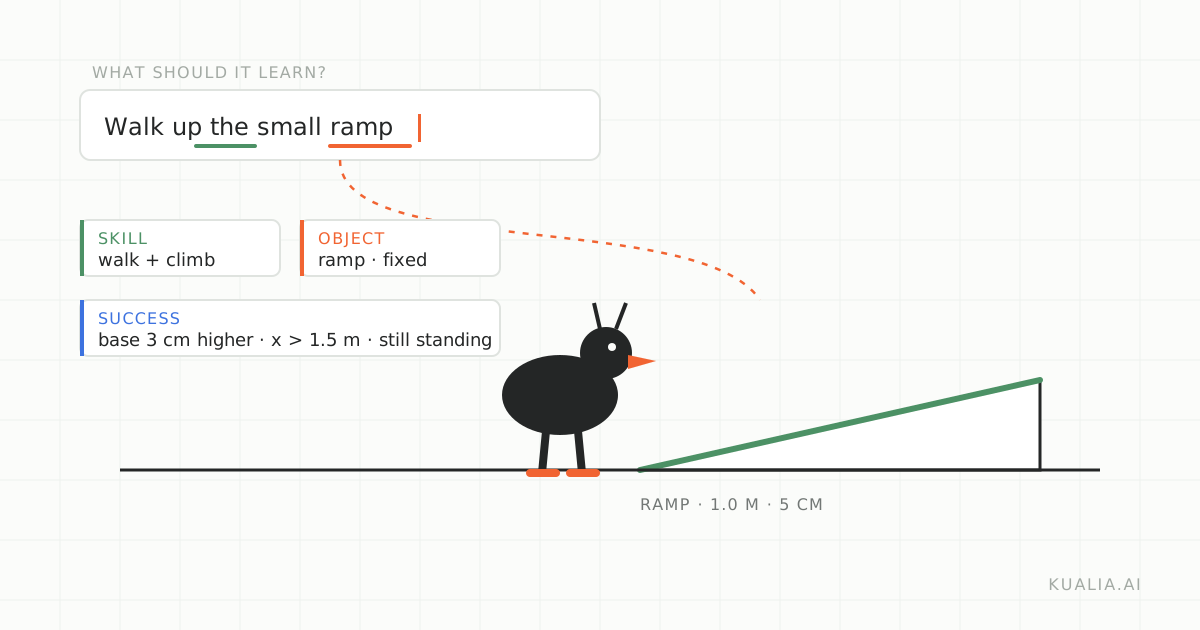 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
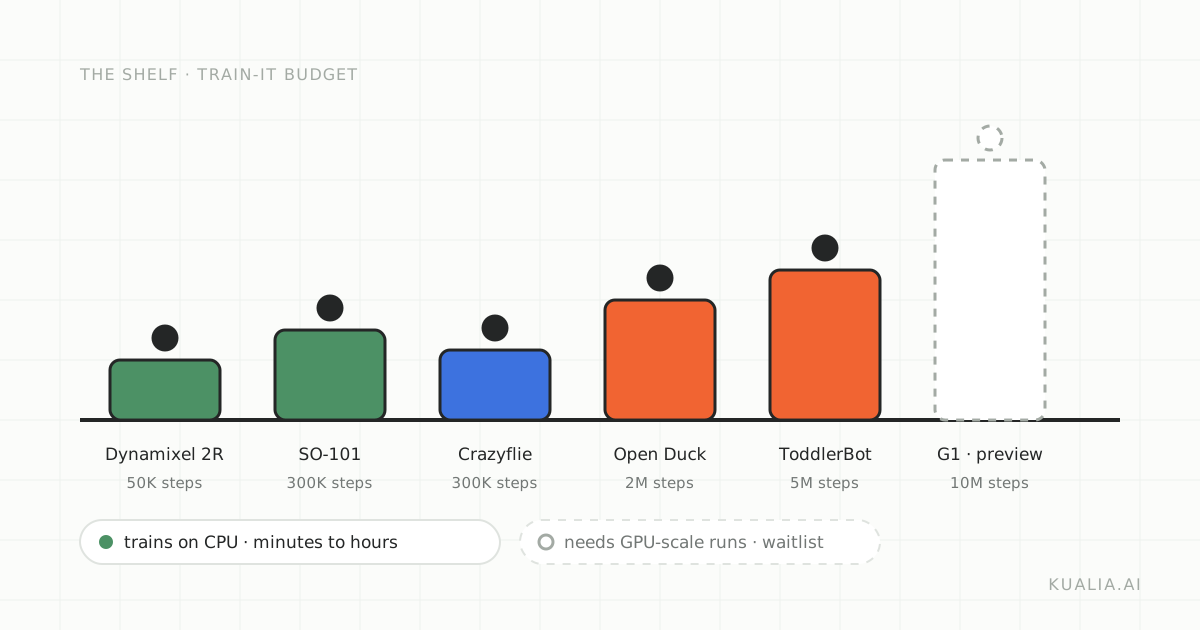 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
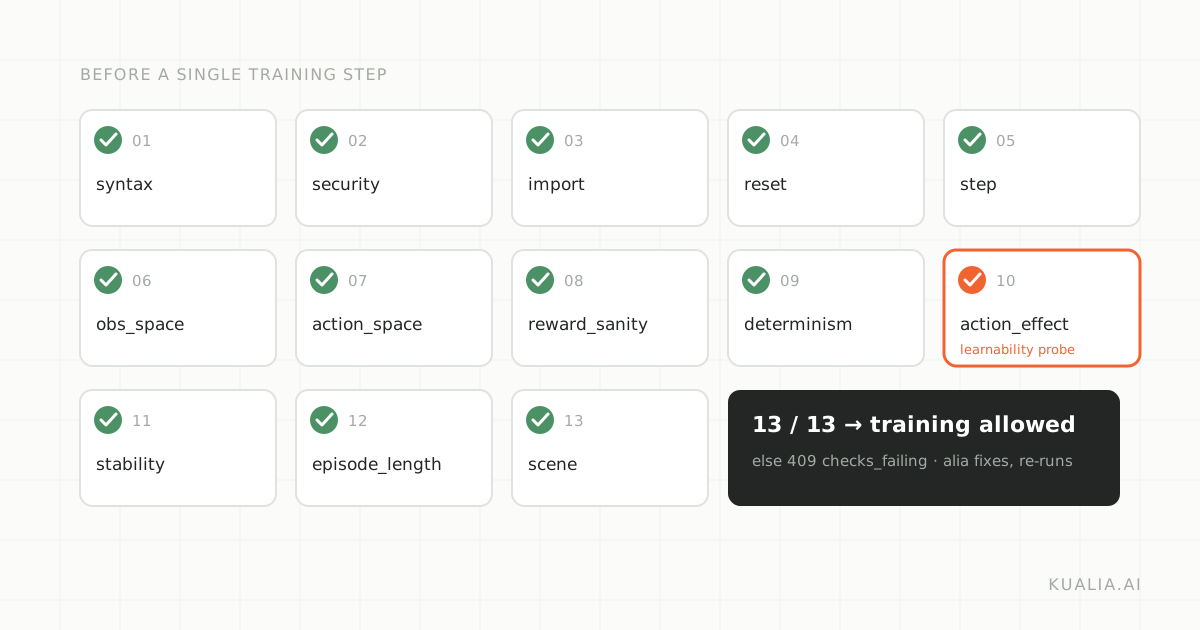 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
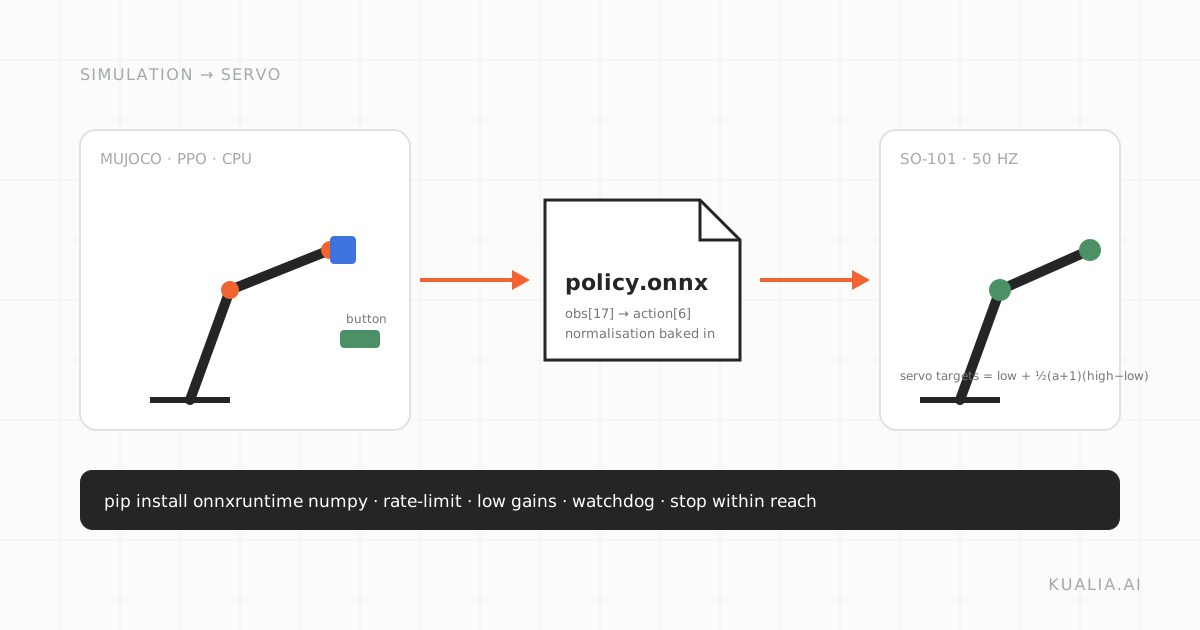 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
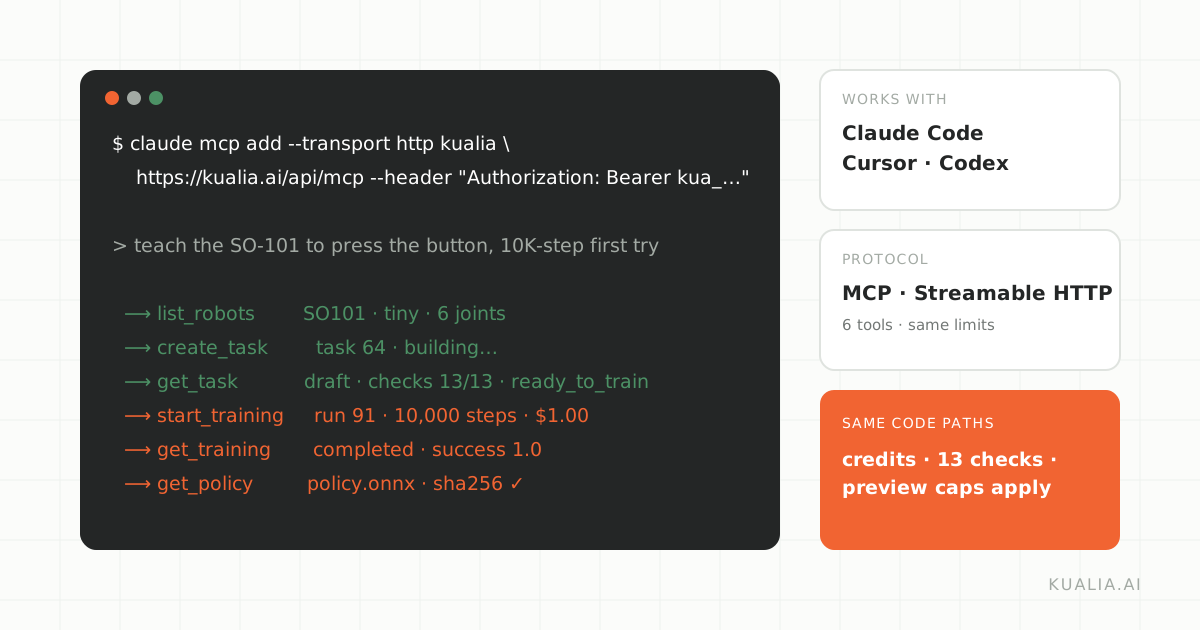 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 4 of 59
Jun 4, 2026The Specificity Paradox in LLM Code GenerationWhen we prompt a large language model to write code, we face a deceptively simple question: how much should we tell it? Intuitively, more detail should help. Give the model the function signature, the expected behavior, Jun 4, 2026Decoupling Geometry from Appearance: How Textured Gaussians Break the 4K Barrier in Feed-Forward SplattingFeed-forward 3D reconstruction has matured remarkably over the past two years. Methods that once required minutes or hours of per-scene optimization can now predict a complete radiance field from a handful of images in a Jun 4, 2026KV-Fold and the Surprising Stability of KV-Cache RecurrenceWhen we think about extending the context length of a transformer, the instinct is usually architectural. We reach for new positional encodings, sparse attention patterns, learned memory tokens, or a full replacement of Jun 4, 2026When Models Become Examiners: Self-Play as an Answer to Benchmark Saturation Introduction Mathematical reasoning benchmarks are running out of headroom. MATH and GSM8K, once the standard tests for separating frontier language models, no longer discriminate between the strongest systems because n Jun 4, 2026Why Potential Based Reward Shaping Matters More for Tuning Than for SpeedReward design remains the most stubborn bottleneck in applied reinforcement learning. Anyone who has tried to train a legged robot knows the ritual: you write a reward term that you believe captures the desired behavior, Jun 4, 2026Why Wearable Motion Models Don't Transfer, and What Geometry Has to Do With It Introduction If you have ever worn a fitness tracker and noticed it count phantom steps while you were typing, or fail to register a workout because you switched the watch to your other wrist, you have encountered one o Jun 4, 2026Toward a Single Embodied Prior: What Qwen-VLA Tells Us About Unifying Robot Learning Introduction The history of robot learning has been a history of fragmentation. Manipulation models predict end-effector poses on tabletops. Navigation models predict discrete movement decisions or waypoints in indoor s Jun 4, 2026Closing the Perception Gap: How Synthetic VQA from a Single Keyword Improves VLMsVision-language models have become competent at a surprising range of tasks: reading text in images, answering complex questions, grounding interface elements, even solving multimodal math problems. Yet they continue to Jun 4, 2026Strategic Navigation or Stochastic Search? What MADQA Reveals About How Agents Reason Over DocumentsWhen we deploy a multimodal agent against a corpus of business documents and watch it produce the correct answer, we tend to assume it found that answer the way a competent analyst would: by forming a hypothesis, locatin Jun 4, 2026What Valiant Actually Defined: Revisiting the Original Theory of the LearnableFor nearly four decades, Leslie Valiant's 1984 paper "A Theory of the Learnable" has been cited as the origin of the Probably Approximately Correct (PAC) framework. Generations of students have learned the PAC model and Jun 3, 2026Murder Mysteries as Signaling Games: Training VLMs to Reason Under DeceptionWhen I first read Collaborative Multi-Agent Scripts Generation for Enhancing Imperfect-Information Reasoning in Murder Mystery Games by Zhong and colleagues, I was struck less by the specific engineering than by what the Jun 3, 2026Why Text-to-Video Models Cannot Count, and What to Do About ItAsk a modern text-to-video model for "three cats playfully chasing each other through the house" and you will likely get two cats, or four, or a blurry pile that resists enumeration. The visual fidelity is often excellen Jun 3, 2026Reading Generation Backwards: Diffusion Models as Generalist Segmentation Engines Introduction For the past few years, the computer vision community has treated image generation and image understanding as adjacent but distinct enterprises. Generative diffusion models learn to synthesize photorealisti Jun 3, 2026Compressing Video Diffusion Caches When the Spectrum Says You CannotLong-horizon video generation has quietly become a memory management problem. As causal video diffusion models scale toward minute-long rollouts at interactive frame rates, the dominant constraint is no longer model capa Jun 3, 2026Structure Substitutes for Scale: Lessons from WARDEN and Endangered Language TranscriptionWhen a language has only two fluent speakers left and a total of six hours of annotated audio, the standard playbook for building speech systems collapses entirely. Modern automatic speech recognition (ASR) and machine t Jun 3, 2026Why Medical Exam Scores Hide the Hardest Part of Clinical ReasoningLarge language models have spent the last two years racking up headlines for passing medical licensing examinations. The standard narrative treats these scores as a proxy for clinical readiness: if a model can answer USM Jun 3, 2026Weak Supervision in Anomaly Detection Is Less Fragmented Than We Think Introduction For most of the past decade, weakly supervised anomaly detection (WSAD) has grown along three largely separate tracks. Each track has its own vocabulary, its own benchmark datasets, and its own arsenal of s Jun 3, 2026Discriminative Retrieval: Why One Well-Formed Query Can Beat Multi-Round SearchWhen I first read "Superintelligent Retrieval Agent: The Next Frontier of Information Retrieval" (SIRA) by Yang, Ma, Chen, and Shrivastava, the part that stayed with me was not the benchmark numbers, impressive as they a