Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
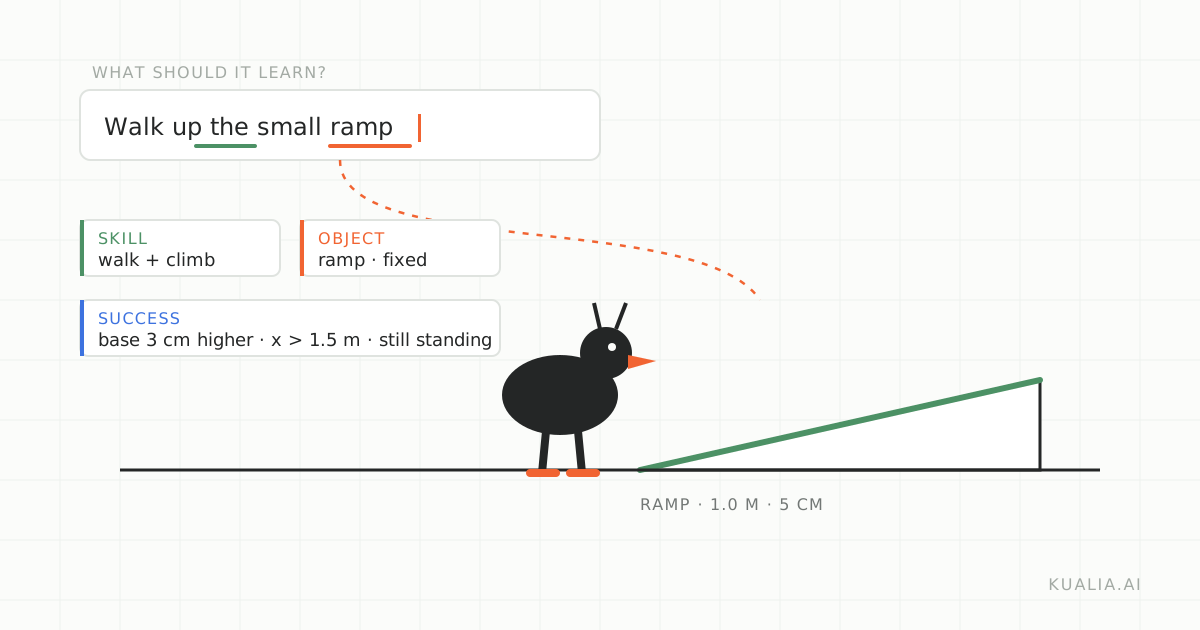 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
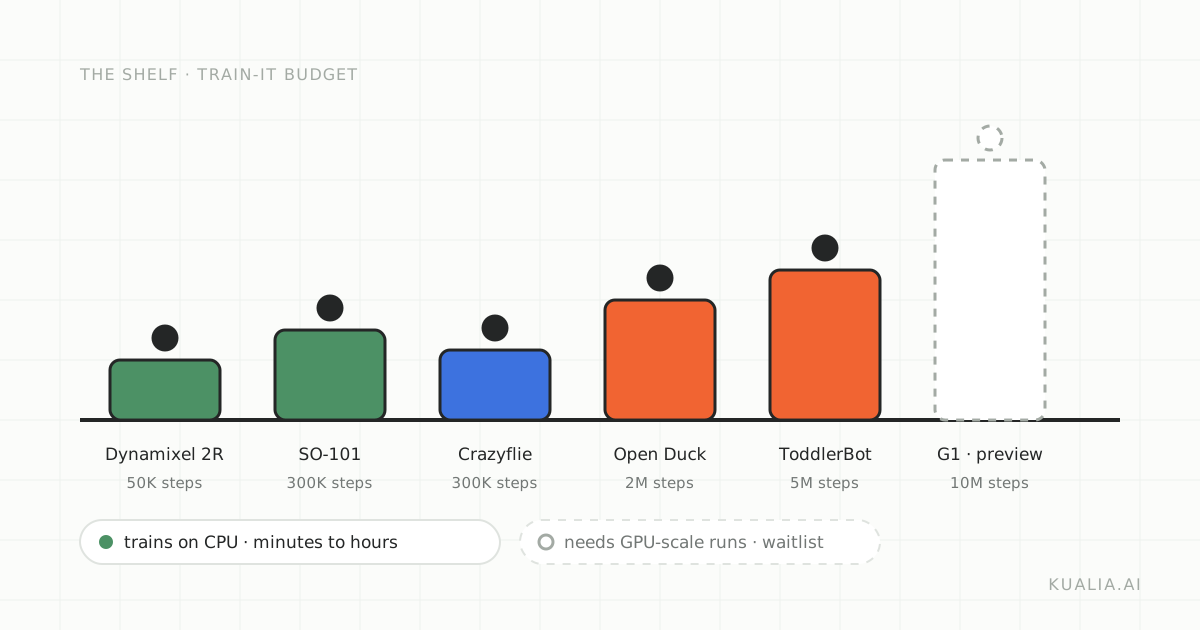 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
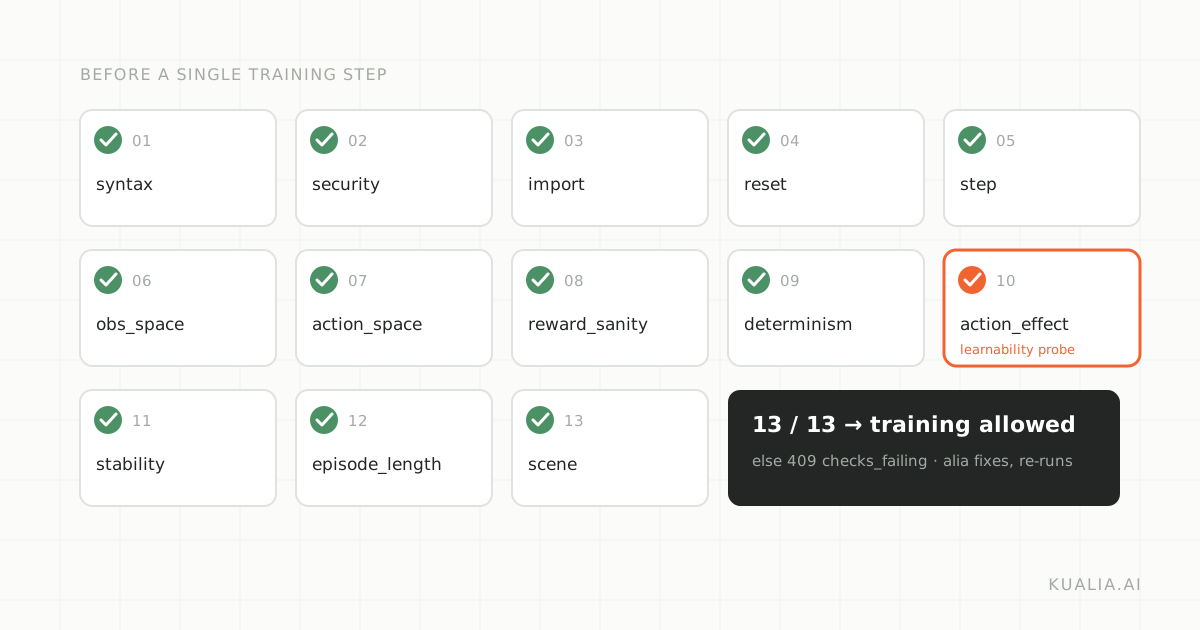 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
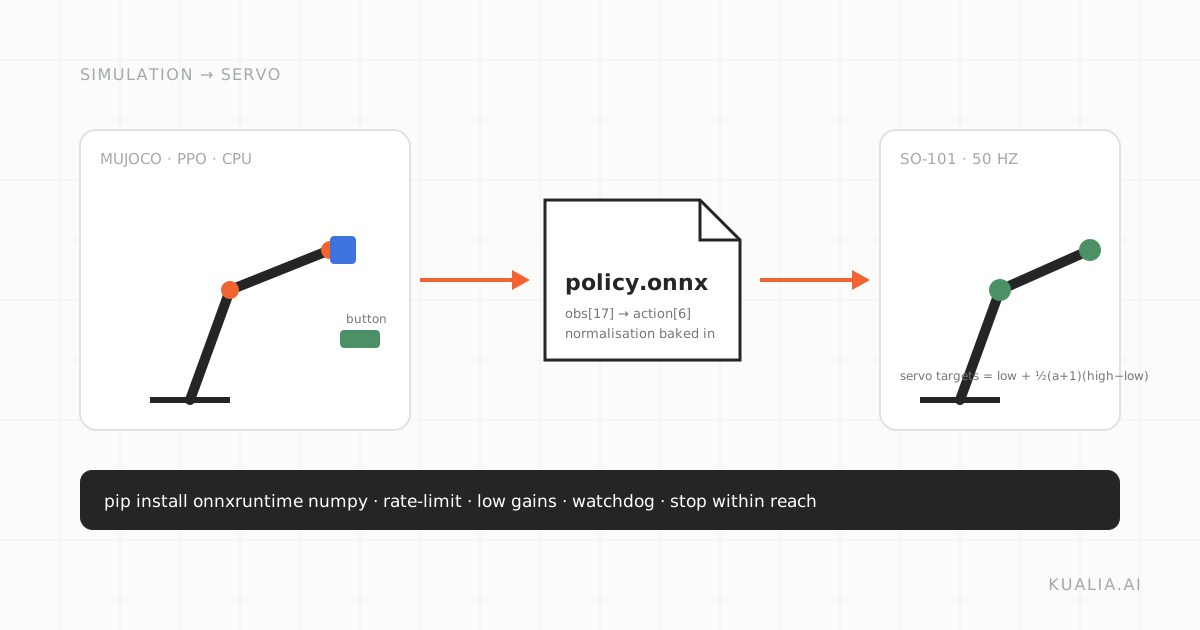 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
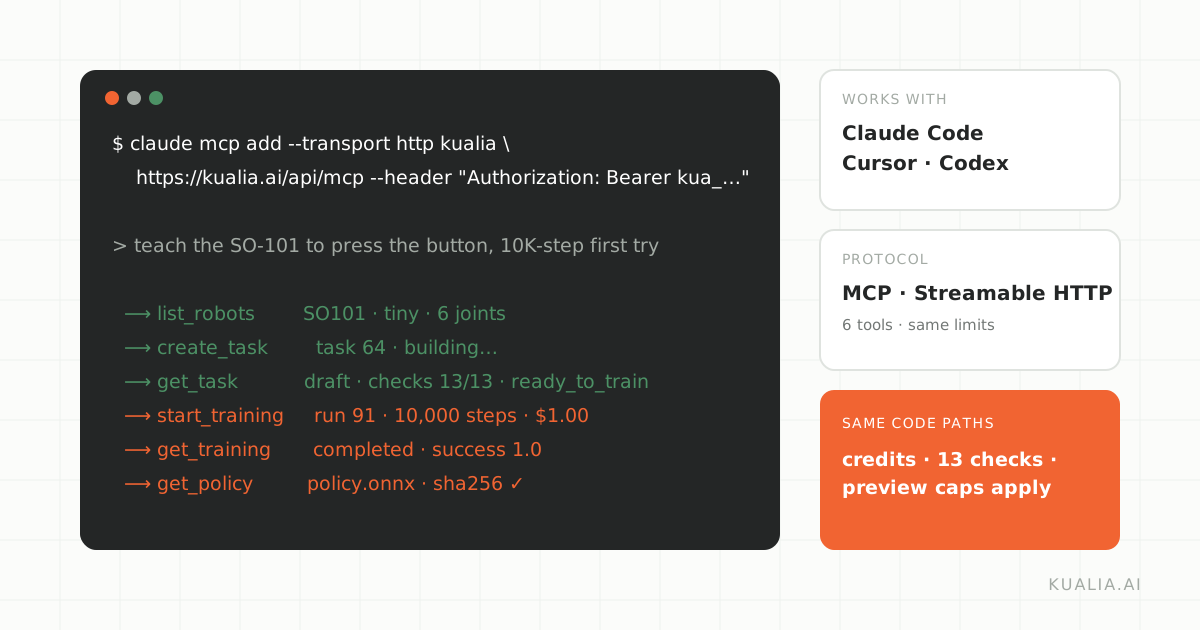 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 29 of 59
Apr 21, 2026Beyond Activation Patterns: Causal Decomposition of Neural Network Computations with CODEC Introduction The dominant paradigm in neural network interpretability has long been an exercise in pattern recognition. We visualize what makes a neuron fire, cluster activation vectors to find latent concepts, or use s Apr 21, 2026Cascading Compression: Unified Token Scoring for Efficient Video Vision-Language ModelsThe computational demands of video understanding have become a critical bottleneck in the development of scalable vision-language models. As these systems process increasingly longer video sequences, the quadratic comple Apr 21, 2026The Sandbox Mirage: Why Web Agents Fail When Reality IntrudesClaude Sonnet 4.6 achieves a 75% task completion rate on WebArena and OSWorld. On ClawBench, it scores 33.3%. For GPT-5.4, the drop is even more precipitous: from roughly 67% to 6.5%. These figures, reported in "ClawBenc Apr 21, 2026Test Time Training as Linear Attention: Reframing Memory in Sequence ModelsTest time training, specifically the variant employing key value binding as a sequence modeling layer, has generated substantial interest as a mechanism for handling long context dependencies. The conventional narrative Apr 21, 2026FlashAttention-4 and the New Reality of Asymmetric Hardware ScalingThe release of FlashAttention-4 represents more than just another optimization for attention kernels. It signals a fundamental shift in how we must approach algorithm design for modern accelerators, where the traditional Apr 21, 2026Structured Intent as a Protocol Layer: Why Explicit Communication Beats Implicit Inference Introduction The central challenge in human-AI interaction is not that models fail to understand us, but that they understand us inconsistently. When the same user intent expressed in natural language produces divergent Apr 21, 2026Multi-Reward Langevin Guidance: From Image Generation to Robot PlanningControlling the output of large generative models remains one of the central challenges in modern machine learning. While pretrained diffusion and flow-matching models can produce photorealistic images, steering them tow Apr 21, 2026Classical and Quantum Speedups for Non-Convex Optimization via Energy Conserving DescentNon-convex optimization remains one of the most challenging problems in machine learning, where traditional gradient-based methods frequently become trapped in local minima. A recent paper by Sun, Wang, Hayden, and Blanc Apr 20, 2026Unveiling Latent Capabilities: Training-Free Multi-Token Prediction Through Embedding-Space Probing Introduction The autoregressive nature of large language models remains one of the most stubborn bottlenecks in efficient inference. Despite the massive parallelism offered by modern GPUs, standard decoding processes to Apr 20, 2026The Hidden Curriculum: How Language Models Learn in Predictable Sequences Introduction We have grown accustomed to watching loss curves descend during pretraining, treating the smooth exponential decay of perplexity as a proxy for learning. Yet this aggregate metric conceals as much as it rev Apr 20, 2026Beyond the Fairness Accuracy Tradeoff: Online Meta-Learning with Dual Parameter PriorsThe persistent tension between predictive accuracy and algorithmic fairness has long dominated discussions in responsible machine learning. Conventional wisdom suggests that enforcing fairness constraints functions as a Apr 20, 2026Feature Matching for Language Model Fine-Tuning: Moving Beyond Teacher Forcing Introduction The dominant paradigm for training large language models rests on a subtle but consequential sleight of hand. During supervised fine-tuning, we optimize models to predict the next token while conditioning o Apr 20, 2026Structural Feature Engineering for Generative Engine Optimization: How Content Geometry Shapes LLM AttentionThe transition from traditional search engines to AI powered generative engines has precipitated a fundamental restructuring of digital visibility economics. Where Search Engine Optimization (SEO) once focused on ranking Apr 20, 2026 Apr 20, 2026Entropy as a Compass: Rethinking Visual Grounding in Vision-Language ModelsVision-language models have achieved impressive performance on standard benchmarks, yet they consistently fail when confronted with fine-grained visual reasoning or compositional queries requiring evidence from spatially Apr 20, 2026The Implementation Gap: Auditing Challenges in Autonomous Machine Learning Research Introduction The automation of scientific discovery has long served as a benchmark for artificial intelligence capabilities. Recent advances in large language models have produced systems capable of autonomous software Apr 20, 2026Unbiasing Vision Transformers: How ALiBi Positional Encoding Rescues Scientific Imaging from DINOv2's Spatial AssumptionsVision transformers have become the default architecture for visual representation learning, with models like DINOv2 providing remarkably general features for downstream tasks. Yet beneath their impressive performance on Apr 20, 2026The Hidden Tax of Proxy Tasks: Why Task-Specific Neural Architecture Search Matters Introduction When SqueezeNAS achieves 73.62% mean Intersection over Union on Cityscapes with sub-100ms latency on an NVIDIA AGX Xavier, the number itself tells only part of the story. The deeper revelation lies in how i