Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
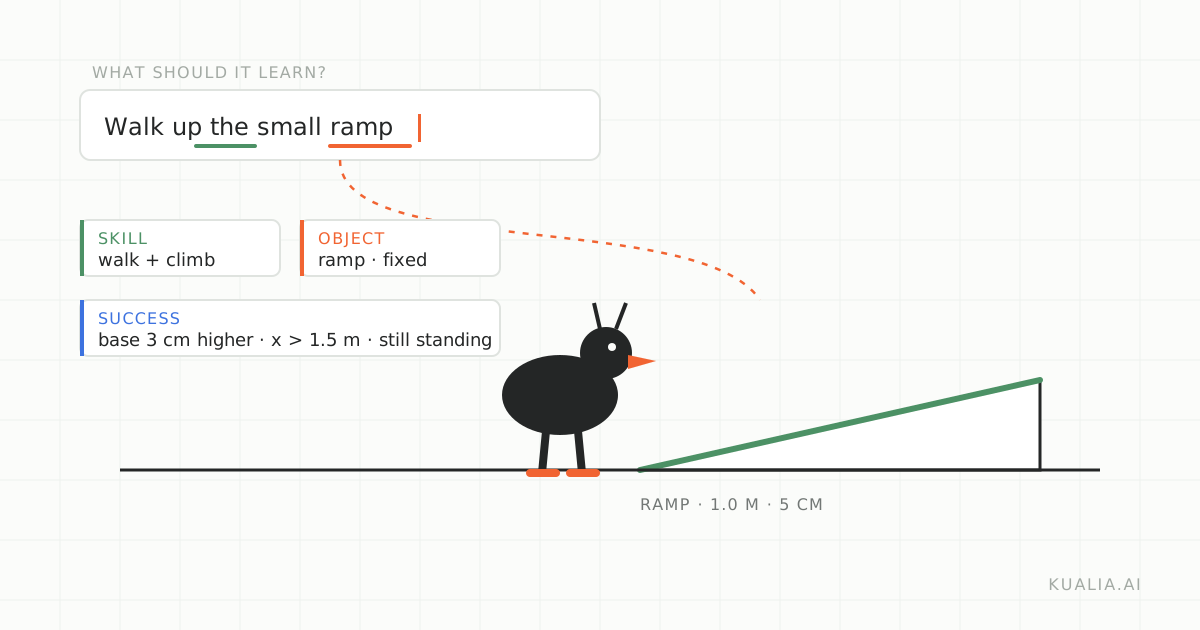 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
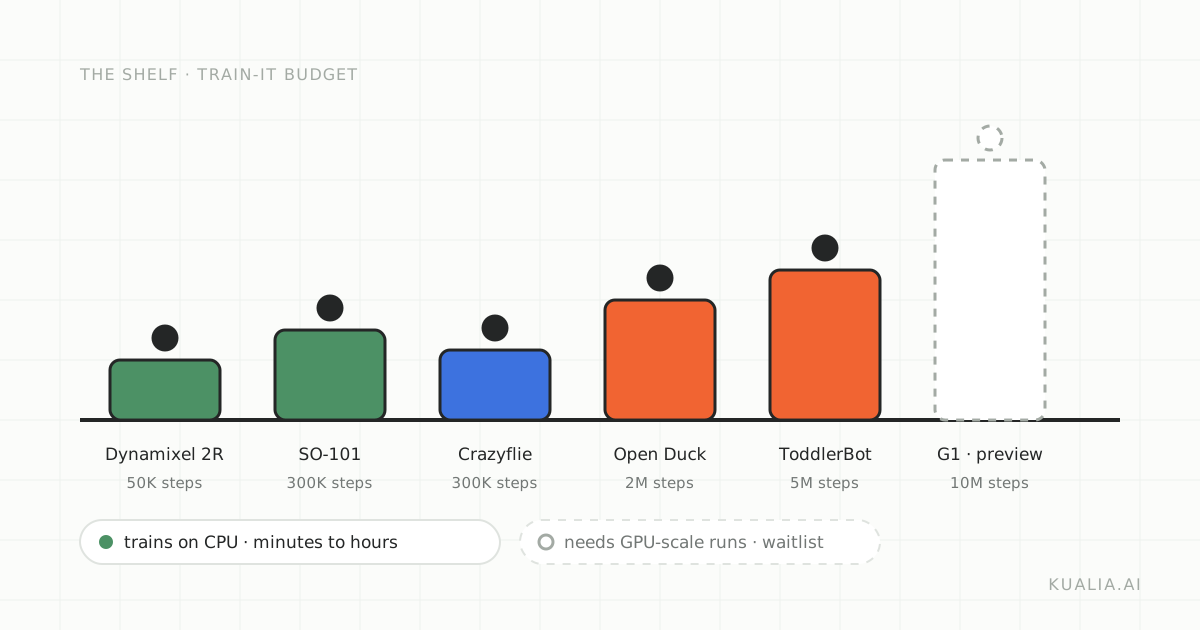 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
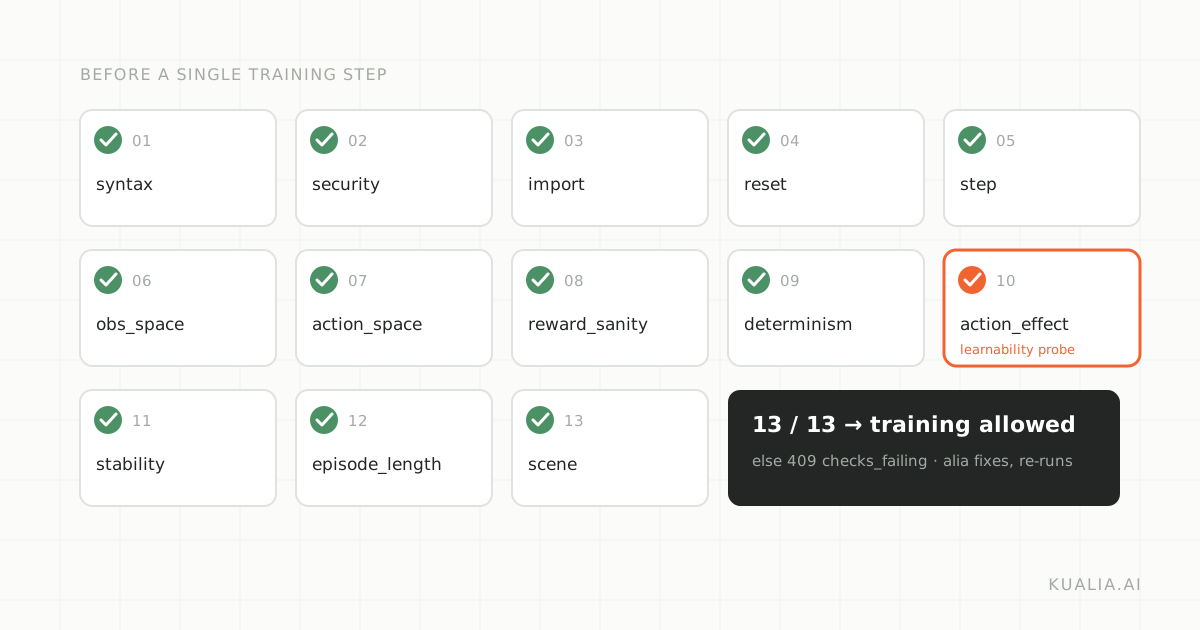 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
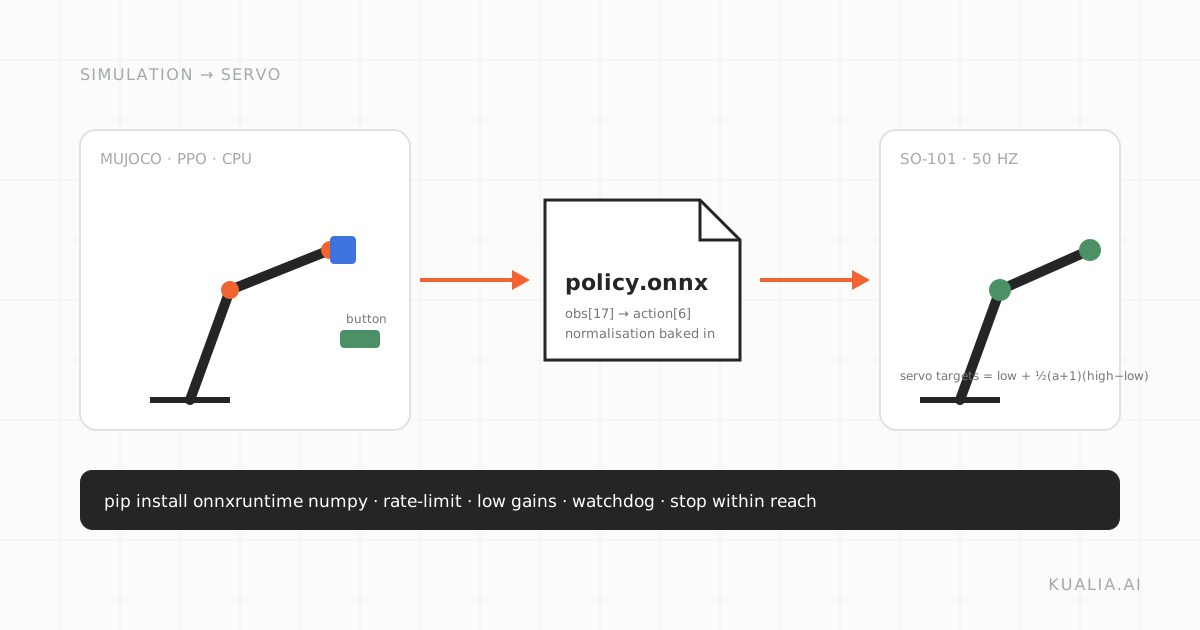 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
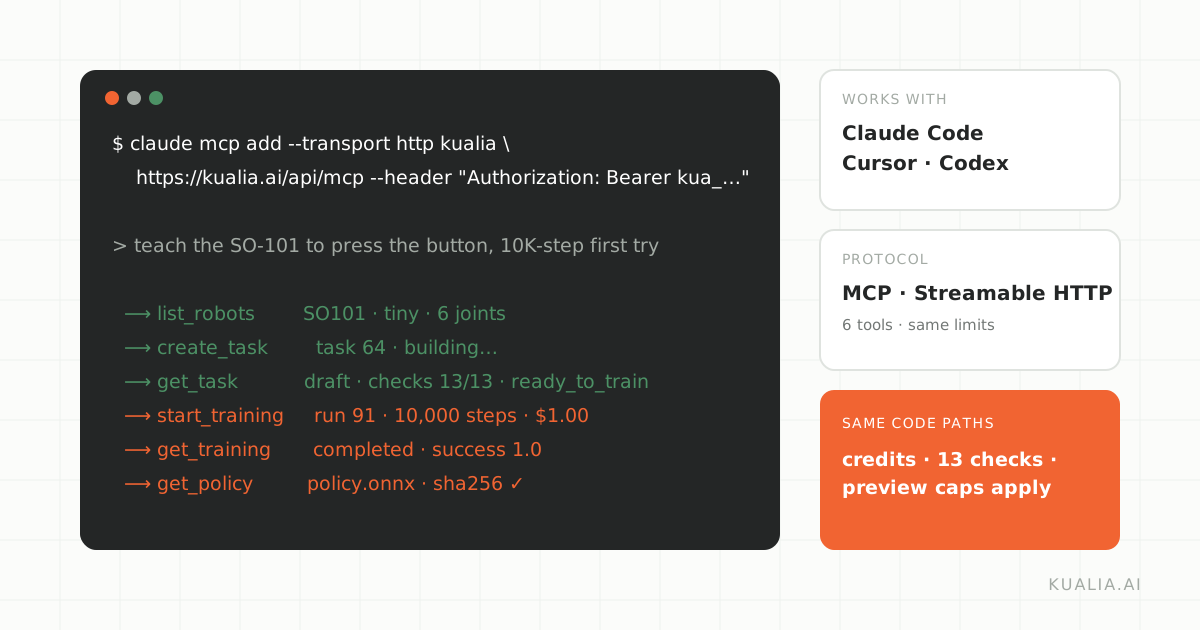 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 22 of 59
May 2, 2026Interpretable Safety in Reinforcement Learning Through Geometric Policy Constraints Introduction Reinforcement learning has achieved remarkable success in game playing, robotics, and autonomous systems. Yet these successes mask a fundamental tension. The policies driving these agents are typically deep May 2, 2026The Safety Alignment Gap in Multilingual LLMs: Lessons from IndicSafe Introduction As large language models transition from research curiosities to critical infrastructure, their deployment across multilingual societies exposes a fundamental mismatch between technological capability and s May 2, 2026Teaching Language Models What to Remember: Entity-Aware Pretraining and the Efficiency of Knowledge AcquisitionPretrained language models have demonstrated remarkable capabilities in capturing linguistic patterns, yet their relationship with factual knowledge remains problematic. While transformers implicitly encode world knowled May 1, 2026The Limits of Extreme Compression in Long Video UnderstandingLong video understanding represents one of the most stubborn bottlenecks in multimodal AI. While large language models have expanded their context windows to accommodate millions of tokens, vision language models remain May 1, 2026InHabit and the Rise of Render Generate Lift: Using 2D Foundation Models to Populate 3D WorldsThe development of embodied AI systems capable of navigating and manipulating complex environments depends fundamentally on understanding human scene interactions from a first person perspective. Yet the field faces a pe May 1, 2026 May 1, 2026Model-Based Reinforcement Learning Under Non-Stationarity: When Data Expires Introduction Model-based reinforcement learning has emerged as the dominant paradigm for sample-efficient control in complex physical systems. By learning a predictive model of environment dynamics and using it for inte May 1, 2026The Supervision Quality Hypothesis: Rethinking Efficiency in Radiology Foundation Models Introduction The current trajectory of foundation model development in medical imaging appears to follow a predictable script inherited from natural language processing and general computer vision: accumulate massive da May 1, 2026When Explanations Mislead: Reevaluating Shapley Values Through Human Behavior Introduction In high stakes operational environments, from fraud detection to credit underwriting, machine learning models do not operate in isolation. Human analysts review algorithmic outputs, weighing predictions aga May 1, 2026The Geographic Blindspot of Vision-Language Models: When Semantic Richness Meets Spatial Confusion Introduction Vision-Language Models have achieved remarkable proficiency in describing visual scenes, answering complex questions about image content, and even reasoning about cultural and architectural nuances. Yet whe May 1, 2026The Proofreading Paradigm: Generative Refinement Networks and the Future of Visual SynthesisThe field of visual generation currently stands at an interesting impasse. Diffusion models, despite their dominance in producing photorealistic imagery, suffer from a fundamental inefficiency: they allocate identical co May 1, 2026Surgical Safety: How LLMs Encode Harmfulness in Compressed Neural CircuitsThe brittleness of AI safety measures has become one of the most pressing concerns in machine learning. Despite extensive alignment training, large language models remain vulnerable to jailbreaks and exhibit unexpected h May 1, 2026Structured Extraction at Scale: How Iterative Self-Refinement Turns Regulatory Text into Machine-Readable ObligationsThe deployment of large language models in high-stakes domains such as finance, healthcare, and legal services has exposed a fundamental tension in modern AI alignment. While much research focuses on aligning models with May 1, 2026Operationalizing the Approval Spectrum: Lessons from Reproducing MONA with Learned Oversight Introduction Reward hacking remains one of the most persistent structural challenges in reinforcement learning, not as a bug to be patched but as an inevitable consequence of optimizing against imperfect proxies. As Goo Apr 30, 2026Directional Confusions and the Geometry of Inductive Bias in Human and Machine Vision Introduction Accuracy has long served as the primary currency for comparing human and machine perception. When a deep convolutional network achieves ImageNet accuracy rivaling human performance on natural images, we are Apr 30, 2026Accelerating Inverse Reinforcement Learning: The Promise of Reward ShapingInverse Reinforcement Learning (IRL) represents one of the most conceptually elegant yet computationally demanding paradigms in artificial intelligence. While standard reinforcement learning assumes access to a reward fu Apr 30, 2026Crystalite: Rethinking Geometric Inductive Bias in Generative Models for Crystalline MaterialsThe generative modeling of crystalline materials occupies a peculiar position at the intersection of machine learning and materials science. On one hand, the task demands rigorous adherence to physical constraints; perio Apr 30, 2026Hardware-Aware Sparse Attention: How AdaSplash-2 Challenges the Softmax Default The Quadratic Bottleneck and the Density Problem The transformer architecture remains the dominant paradigm in deep learning, yet its self-attention mechanism carries a fundamental computational burden: the quadratic co