Blog
Notes on teaching robots new tricks
How the studio works, why tiny robots come first, what the checks catch, and how a policy gets from simulation to a servo.
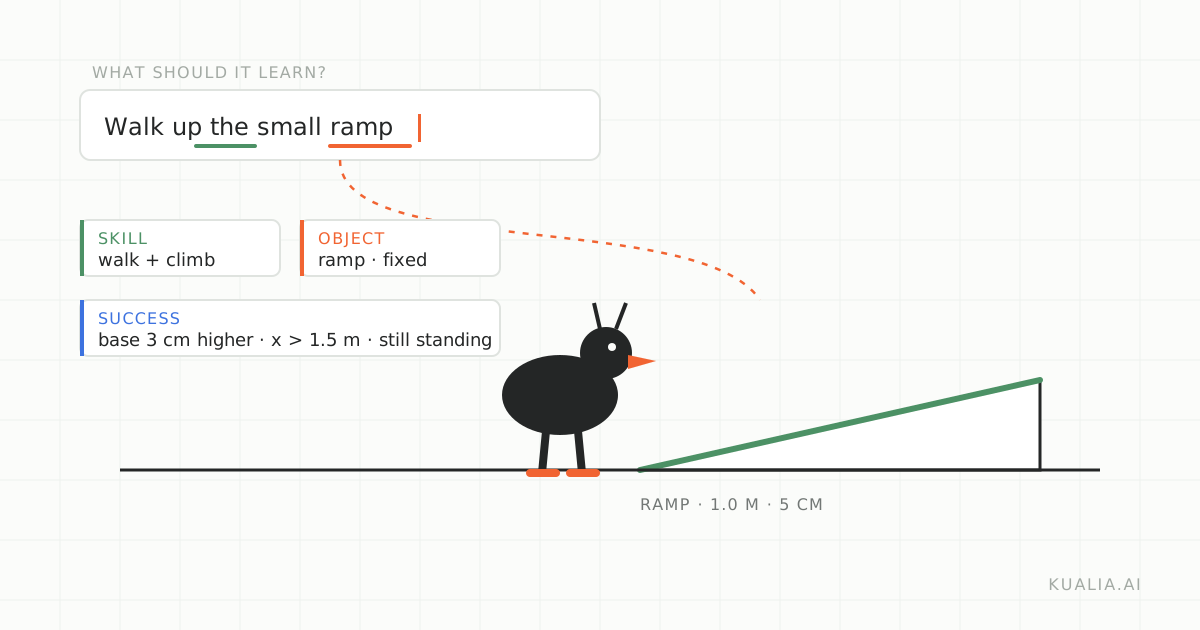 workflowopen-duck-miniSep 29, 2026 · 6 min readFrom a sentence to a walking duck: how kualia turns a plain-language brief into a training taskA walk through the whole kualia workflow, from a one-sentence brief to an ONNX policy, using the Open Duck Mini and a small ramp.Read the post
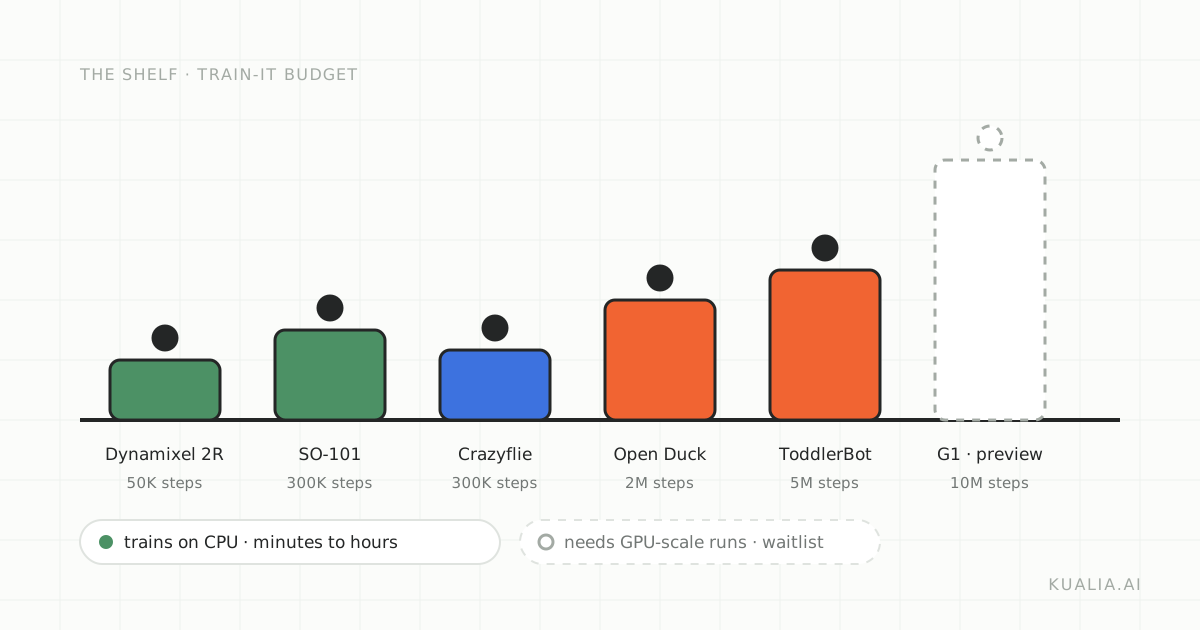 Sep 27, 2026 · 5 minWhy we start with tiny robotsDesk-sized robots train on CPU in minutes to hours, cost little to own and cross the sim-to-real gap without heroics. That is why kualia's shelf starts with them.
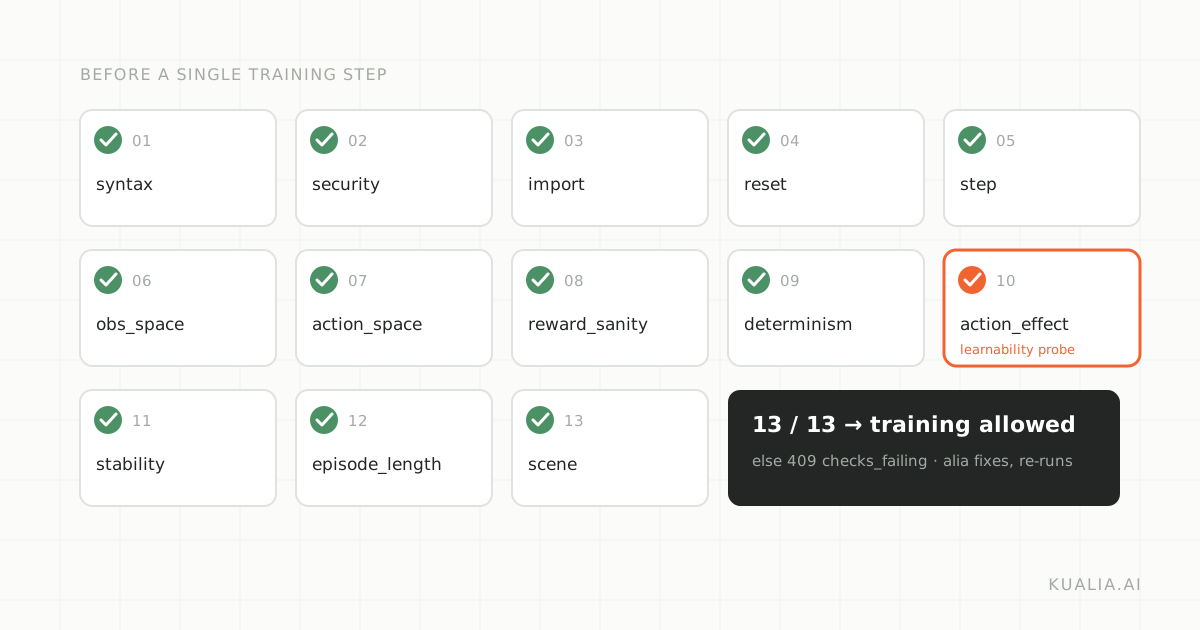 Sep 25, 2026 · 6 min13 checks before a single training stepalia writes the training task, but it does not get to grade its own work. Every task passes 13 sandbox checks before training can start. Here is what each one catches.
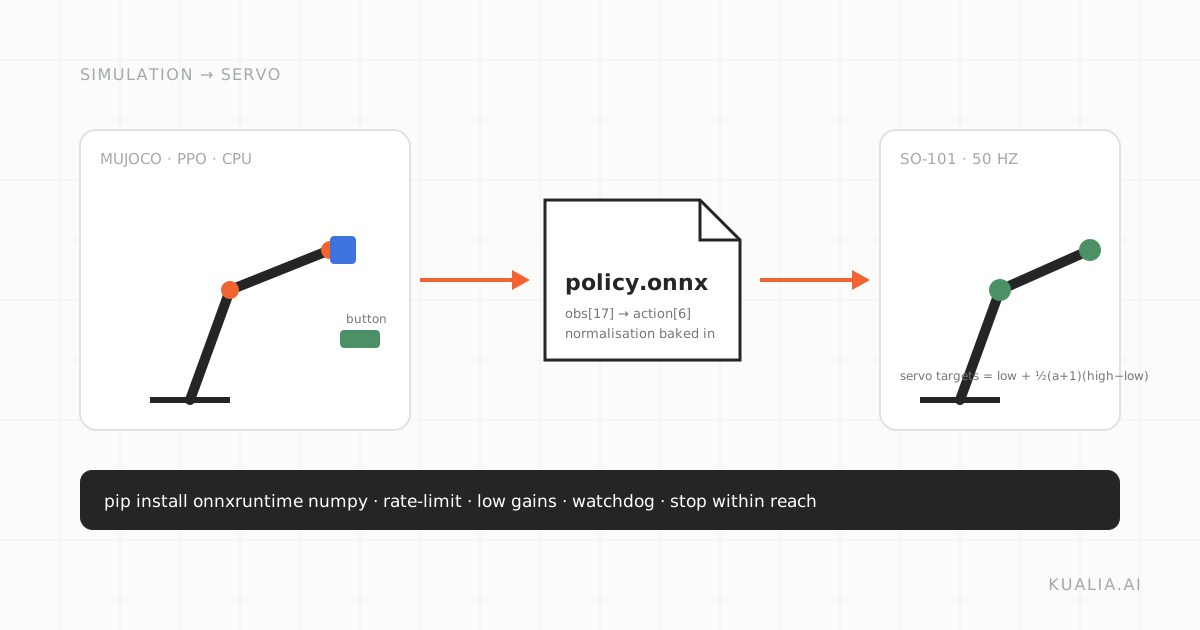 Sep 23, 2026 · 5 minFrom simulation to servo: running your ONNX policy on a real SO-101What is inside a kualia ONNX export, how to read its metadata, a minimal onnxruntime loop for the SO-101, and the sim-to-real checklist before you power the servos.
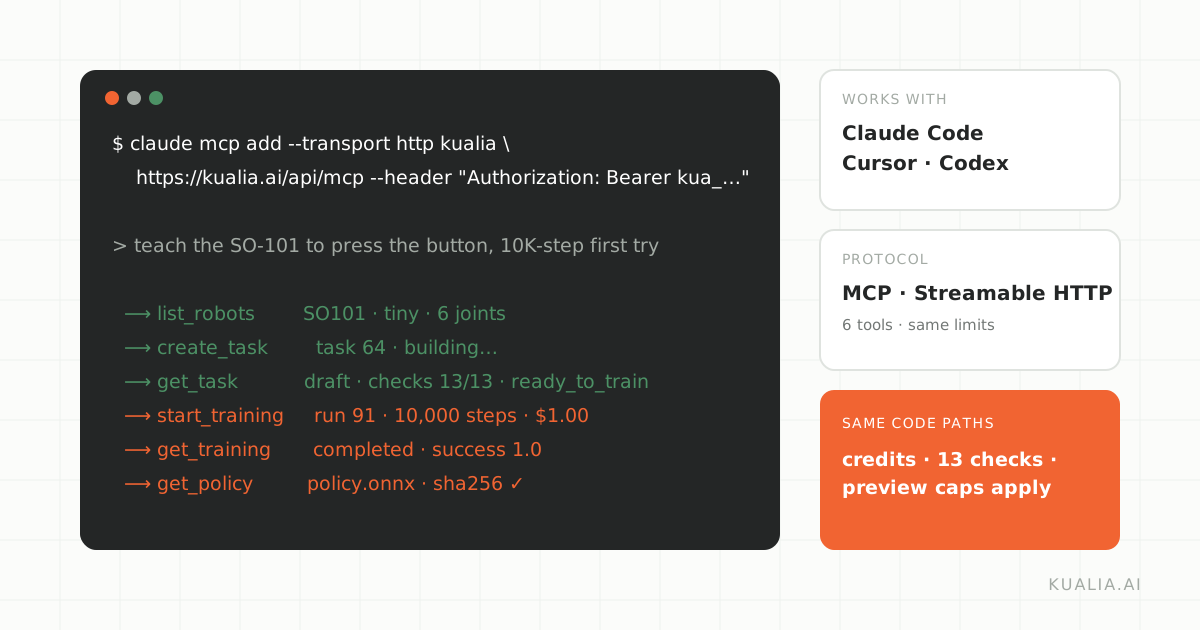 Sep 21, 2026 · 5 minLet your coding agent train the robotkualia is a remote MCP server. Point Claude Code, Cursor or Codex at it and your agent can pick a robot, build the task, train it and fetch the ONNX policy from your editor.
Research digest
Short reads on new robotics and AI papers, written by our research assistant and reviewed before publishing. 1,060 so far.
Page 20 of 59
May 5, 2026Autoregressive World Models: Why INSPATIO-WORLD's Cache-Based Architecture Challenges Diffusion DominanceThe pursuit of interactive world models has reached an inflection point. For years, the computer vision community has pursued video diffusion models as the primary vehicle for world simulation, drawn by their ability to May 5, 2026Spatially Grounded Video Generation and the Coming Shift in Autonomous Simulation Introduction The boundary between static photography and navigable virtual worlds has long been defined by laborious 3D reconstruction pipelines. NeRFs and Gaussian splatting brought photorealism, yet they remain tether May 5, 2026When Text Surpasses Vision: The Counterintuitive Superiority of LLMs over VLMs in 3D Spatial Evaluation Introduction The prevailing wisdom in artificial intelligence holds that spatial reasoning is the natural domain of vision. When we evaluate whether a generated 3D indoor scene is plausible, the instinctive approach is May 4, 2026Beyond Gaussian Bottlenecks: Why Latent Geometry Matters for Visual World ModelsThe transition from pixel-level processing to high dimensional feature spaces has fundamentally altered how we approach computer vision. Modern Vision Transformers (ViTs) extract rich representations that capture semanti May 4, 2026 May 4, 2026Beyond Geometric Planning: Large Vision-Language Models as Autonomous Indoor PilotsIndoor autonomous navigation has long been dominated by geometric approaches. SLAM systems, occupancy grids, and waypoint based planning have served as the backbone of drone autonomy in GPS denied environments. Yet these May 4, 2026HippoCamp and the Forgotten Frontier of Personal AI: Why Your Computer Still Confuses GPT-4 Introduction We have grown accustomed to artificial intelligence that can draft legal briefs, generate photorealistic imagery, and write functional code from vague prompts. Yet, ask the most advanced multimodal models t May 4, 2026 May 4, 2026 May 4, 2026The Inverted Persona Problem: When Misaligned Models Believe They Are Helpful Introduction Emergent misalignment represents one of the more puzzling failure modes in contemporary large language model training. First documented by Betley et al., this phenomenon occurs when fine tuning on narrowly May 4, 2026The Paradox of AI Fluency: Why Experts Fail More Often Than Novices Introduction The conventional wisdom surrounding expertise suggests that as users gain proficiency with a tool, their error rates should decline. A novice driver stalls the engine; an expert does not. A novice programme May 4, 2026All-Optical Inference at the Speed of Light: Small-Scale Photonic KANs Using Standard Telecom Hardware Introduction The promise of photonic neural networks has long been tempered by a persistent engineering compromise. While linear optical operations can be performed with remarkable speed and efficiency using interferome May 4, 2026DreamLite: Unified On-Device Diffusion Through In-Context ConditioningThe deployment of large-scale diffusion models has reached an inflection point. While server-side architectures such as FLUX and HunyuanImage 3.0 have pushed the boundaries of text-to-image fidelity, their multi-billion May 4, 2026The Illusion of Robustness: Why Prompt Injection Defenses Fail Under Adaptive ScrutinyPrompt injection has cemented its position as the preeminent security threat facing large language model applications, topping the OWASP Top 10 for LLM risks. Yet despite the proliferation of defensive techniques claimin May 4, 2026Reconstructive Visual Instruction Tuning: Rethinking Supervision in Multimodal ModelsVisual instruction tuning has emerged as the dominant paradigm for aligning large language models with visual understanding. The standard recipe appears straightforward: project images into visual tokens via a frozen enc May 3, 2026The Efficiency of Concision: Rethinking Chain-of-Thought for Video UnderstandingThe dominant narrative in multimodal artificial intelligence suggests that complexity requires verbosity. When large language models tackle difficult problems, we encourage them to think step by step, generating elaborat May 3, 2026Beyond Animation: The Perception-Action Gap in Autonomous Digital HumansFor decades, digital human research has operated under a fundamental misconception. The field has treated autonomous behavior as primarily an animation problem, focusing on kinematic fidelity, motion naturalness, and vis May 3, 2026The Meta-Budget Problem: Active Experimental Design for Cost-Efficient Scaling Law Estimation Introduction Scaling laws have become the de facto planning framework for large-scale artificial intelligence research. By fitting parametric relationships between model size, data volume, compute budget, and final perf